` → `` → `` hierarchy
- **No text in images:** AI can't read screenshots. Use actual text + `
`
- **Lists > paragraphs:** Bullet points are easier to extract than walls of text
- **Scannable structure:** Headers every 2-3 paragraphs
A 2,000-word article with 3 headers is harder to cite than a 2,000-word article with 15 headers. AI needs to find the specific section that answers the user's question.
### 5. Metadata Completeness
Even though AI ignores ``, it checks:
- Canonical URL (to avoid duplicate content)
- Open Graph image (for preview context)
- Article `datePublished` (to know how old your content is)
Stale content (3+ years old) gets deprioritized. Fresh content gets cited more often.
### 6. Answer-Ready Format
The best AEO content directly answers common questions:
- "What is X?" → Definition box at the top
- "How do I X?" → Step-by-step with numbered lists
- "Why does X matter?" → Clear benefits, quantified where possible
Content written as "walls of paragraphs" is less likely to be extracted. Content structured as "question → answer → proof" is gold. I built my [autonomous blog agent](/blog/openclaw-autonomous-blog-agent) around this principle. Every draft follows the question-answer-proof structure automatically.
---
## AEO vs SEO vs GEO: Three Optimization Disciplines
The search landscape now has three distinct optimization disciplines. SEO targets traditional search rankings, AEO targets AI answer citations, and GEO (Generative Engine Optimization) targets how generative AI models represent your brand and content in synthesized responses. They overlap but reward different signals.
| Factor | SEO (Google) | AEO (AI Engines) | GEO (Generative AI) |
|--------|-------------|-----------------|---------------------|
| Goal | Rank in search results | Get cited in AI answers | Shape AI's representation of your brand |
| Crawling | robots.txt | robots.txt + llms.txt | robots.txt + llms.txt + ai.txt |
| Ranking | Backlinks + engagement | Content accuracy + structure | Entity clarity + topical authority |
| Signal count | 200+ factors | ~6 critical factors | Emerging, entity-centric |
| Meta descriptions | Shown to users | Ignored | Ignored |
| Title tags | Shown to users | Used for context | Used for entity recognition |
| Content format | Long-form preferred | Any length, needs structure | Definition-dense, claim-backed |
| Freshness | Can rank for years | Deprioritized after ~10 months | Training data snapshots, slower refresh |
| Citations | Implied (link juice) | Explicit (source linked in answer) | Implicit (model "knows" you) |
| Key differentiator | Popularity | Extractability | Entity recognition |
### When to prioritize which
- **SEO first** if your revenue depends on organic click-through traffic today.
- **AEO first** if you produce reference content (definitions, tutorials, comparisons) that AI engines synthesize into answers.
- **GEO first** if brand perception matters more than individual page traffic. You want AI to describe your company correctly when users ask about your category.
Most sites benefit from all three, and the technical foundations overlap heavily. The good news: structured data, semantic HTML, clear headings, and answer-first formatting improve all three simultaneously. The differences are in emphasis, not in contradiction.
**The opportunity:** A well-structured blog post with schema and semantic HTML will rank on Google, appear in AI answers, *and* inform how generative models represent your expertise. The cost of doing all three is marginally higher than doing one.
---
## How Do You Start Optimizing for Answer Engines?
Start by confirming AI crawlers can access your site via robots.txt, then create an llms.txt file at your site root. Audit your top five pages to add schema markup, restructure them with more headers, and rewrite openings to directly answer the question in the title. Those four actions deliver the most AEO impact.
## How to Start with AEO
Four actions deliver 80% of your AEO impact: unblock AI crawlers in robots.txt, create a two-paragraph llms.txt at your site root, add FAQPage schema to your three best posts, and rewrite each post's opening paragraph to directly answer the title question. You can finish all four in under an hour.
### Step 1: Check if AI Can Find You
```bash
# Can Perplexity, Claude, etc. access your site?
curl -I yoursite.com/robots.txt
# Look for GPTBot, ClaudeBot, PerplexityBot allow rules
```
### Step 2: Create `/llms.txt`
Add this file to your site root:
```
# Content policy for LLMs
All content available for training and search.
Please attribute as: [Article] by [Author] (yoursite.com)
Sitemap: https://yoursite.com/sitemap.xml
RSS: https://yoursite.com/rss.xml
```
### Step 3: Audit Your Best Content
Pick your 5 best-performing pages and:
- Add schema (BlogPosting, HowTo, FAQ)
- Restructure with more headers
- Move key info to the top
- Add a definition box for the main question
### Step 4: Monitor in Perplexity
Search your main topics in Perplexity. Are you being cited? If not, your content isn't being discovered.
---
## Platform-by-Platform AEO Strategy
Each AI engine has distinct citation behavior and source preferences. Perplexity favors Reddit and reference-style content; ChatGPT is highly selective and freshness-sensitive; Google AI Overview mirrors traditional search rankings; Claude rewards structured technical writing. A platform-specific approach compounds your overall citation rate significantly beyond what generic AEO delivers.
### Perplexity
Perplexity cites the most sources per answer (~21.9) and favors Reddit heavily (46.7% of top sources, per Profound's 2025 citation-pattern study). To optimize for Perplexity:
- **Participate in Reddit discussions** about your expertise topics. Perplexity's retrieval pipeline weights Reddit as a high-trust source for niche questions. Genuine contributions with links to your detailed writeups outperform any on-site optimization alone.
- **Structure content as reference material.** Perplexity favors pages that read like authoritative references: tables, definitions, numbered lists, and comparative data. Pure opinion pieces get cited less.
- **Keep content updated.** Perplexity's real-time retrieval means recently updated pages get priority. Pages with `dateModified` schema that reflect genuine content updates outperform stale pages.
- **Include original data.** Benchmark results, survey findings, and original research get cited at higher rates because they provide information Perplexity can't synthesize from other sources.
### ChatGPT (SearchGPT / Browse)
ChatGPT is the most selective citer (~7.9 sources per answer) and leans heavily on Wikipedia (4.8% of all citations, per Qwairy's Q3 2025 provider study). To optimize:
- **Answer the exact question in paragraph one.** ChatGPT extracts more aggressively than other platforms. If your answer is in paragraph four, it may not get extracted at all.
- **Target Wikipedia-adjacent queries.** ChatGPT cites Wikipedia for broad topics but turns to specialized sources for niche questions. The sweet spot is questions too specific for Wikipedia but too authoritative for forums.
- **Prioritize freshness.** AI-cited pages skew markedly fresher than traditional search results (Ahrefs measured AI-cited URLs at roughly 26% fresher than same-query SERP pages). A page that hasn't been updated in a year is competing at a measurable disadvantage.
- **Use canonical URLs consistently.** ChatGPT deduplicates aggressively. If your content appears at multiple URLs (www vs non-www, trailing slashes, paginated versions), citations may be split or lost.
### Google AI Overview
Google AI Overview draws 76% of its citations from the traditional top 10 results. This makes it the most SEO-correlated AI citation source.
- **Rank in Google first.** Unlike other AI engines, Google AI Overview primarily cites pages that already rank well in traditional search. AEO-only optimization without SEO foundations won't work here.
- **Add FAQPage schema.** Google AI Overview preferentially extracts from pages with structured FAQ markup. The question-answer format maps directly to how Overview constructs its responses.
- **Target featured snippet queries.** Queries that currently trigger featured snippets are the most likely to trigger AI Overview. If you can win the snippet, you're positioned for the Overview citation.
### Claude
Claude doesn't have a live search product with citations in the same way, but its training data preferences and retrieval behaviors are worth understanding:
- **Maintain an llms.txt file.** Claude's parent company (Anthropic) respects llms.txt as a content policy signal. Having one is a positive signal for ClaudeBot crawling.
- **Provide structured, well-organized technical content.** Claude's training pipeline favors content with clear hierarchical structure, code examples with context, and explicit reasoning chains.
- **Avoid content that reads like AI-generated filler.** Claude's quality filters are sensitive to low-information-density content. Dense, opinionated, experience-backed writing gets weighted higher than generic explainers.
---
## Common AEO Mistakes
The six mistakes that most often keep well-written content invisible to AI engines are: blocked crawlers, buried answers, image-only key information, assuming Google rank equals AI visibility, bumping date metadata without changing content, and skipping FAQ schema. Each is fixable in under an hour once you know to look for it.
### Mistake 1: Blocking AI crawlers unintentionally
The most common AEO failure is a robots.txt that blocks crawlers the site owner doesn't know about. A blanket `Disallow: /` for unlisted user agents, or a hosting platform that adds `X-Robots-Tag: noai` by default, silently makes your entire site invisible. Run `curl -I yoursite.com/robots.txt` and check what it actually says. Don't assume.
### Mistake 2: Burying the answer
SEO rewards content that keeps users scrolling: long intros, context-setting, narrative buildup. AEO rewards the opposite. If your page title is "What is Answer Engine Optimization?" and the definition doesn't appear until paragraph three, AI engines may extract from a competitor who puts it in paragraph one. Move the answer up. Context can follow.
### Mistake 3: Using images instead of text for key information
Infographics, diagrams, and screenshots are invisible to AI extraction. If your comparison table is an image, AI engines can't read it. If your step-by-step tutorial is a screenshot of a terminal, AI can't extract the commands. Use real HTML tables, real code blocks, and real text. Add `alt` attributes to images, but don't rely on `alt` for primary content.
### Mistake 4: Assuming Google ranking equals AI visibility
This is the most expensive mistake. A page ranking #1 on Google may not be cited by any AI engine. Google and AI engines evaluate different signals: Google weighs backlinks and click-through rate; AI engines weigh extractability and structural clarity. The only AI engine with strong Google correlation is Google AI Overview (76% overlap). For Perplexity, ChatGPT, and Claude, your Google rank is largely irrelevant.
### Mistake 5: Updating `dateModified` without changing content
Pages with `dateModified` schema get 1.8x more AI citations, but only if the content actually changed. Bumping the date on unchanged content is detectable (AI engines can diff cached versions) and triggers a trust penalty. When you update `dateModified`, make substantive changes: new data, expanded sections, corrected claims, or added examples.
### Mistake 6: Ignoring FAQ schema
FAQPage schema is the single highest-ROI structured data for AEO. It maps directly to how AI engines construct answers: question in, answer out. A page with five well-structured FAQ entries gives AI engines five separate extraction opportunities. A page without it gives AI engines one: the entire article body, which they then have to parse themselves with lower accuracy.
---
## How Do You Measure AEO Performance Without a Dashboard?
Measure AEO manually each month by querying ChatGPT, Perplexity, Claude, and Gemini with the exact questions your content answers, then checking whether you are cited. Track AI referral traffic in analytics using domain segments, and monitor Google's AI Overview for your target queries to identify citation gaps.
## Measuring AEO Progress
Track AEO performance with four monthly checks: a manual citation audit across ChatGPT, Perplexity, Claude, and Gemini; AI referral traffic segments in analytics; an automated infrastructure scan via citability.dev; and a Google AI Overview review for your target queries. No single dashboard does this yet.
The hardest part of AEO is knowing if it's working. Traditional SEO has rankings and impressions in Search Console. AEO doesn't have a dashboard yet.
### Manual citation audit (monthly)
Open ChatGPT, Perplexity, Claude, and Gemini. Ask the exact questions your content answers:
- "What is AEO?"
- "How do I optimize for Perplexity?"
- "What is llms.txt?"
Are you cited? If not, who is? Read the content that does get cited and compare it to yours. The differences are usually structural: their definition is in the first paragraph, yours is in paragraph four. Their page has 12 question-format headers, yours has three. These gaps are fixable.
### Want to See Which URLs ChatGPT Cites From Your Site?
The manual audit above is free but slow, and it only samples a few questions. That exact problem is why I built [citability.dev](https://citability.dev/?utm_source=chudidev&utm_medium=referral&utm_campaign=aeo-answer-engine-optimization-explained): the paid citation audit asks ChatGPT and Perplexity real questions in your topic and records which URLs from your site they actually cite, with the raw AI responses kept as receipts. Nothing is scored that wasn't tested. Start with the free [30-second infrastructure scan](https://citability.dev/scan?utm_source=chudidev&utm_medium=referral&utm_campaign=aeo-answer-engine-optimization-explained) to clear crawl-access and structure blockers first, then run the citation test for your URL-level results.
### AI referral traffic in analytics
Create a segment for sessions from AI engine domains: `chatgpt.com`, `perplexity.ai`, `claude.ai`, `gemini.google.com`, `copilot.microsoft.com`. Track this monthly. Growth here is a leading indicator of citation growth. Direct AI traffic often comes before organic traffic from AI-influenced searches.
### Automated infrastructure auditing
Manual citation checks tell you the outcome but not the cause. Infrastructure audits identify the specific technical gaps preventing citations. Tools like [citability.dev](https://citability.dev/scan?utm_source=chudidev&utm_medium=referral&utm_campaign=aeo-answer-engine-optimization-explained) run 10 automated checks against your site: robots.txt permissions, sitemap completeness, answer-first content structure, content freshness via dateModified schema, JSON-LD coverage, meta descriptions, canonical URLs, HTTPS, heading hierarchy, and social sharing tags. The scan takes under 30 seconds and shows exactly which signals pass and which need fixing.
### Google AI Overview tracking
Search your target queries in Chrome incognito. Does Google's AI Overview cite you? If it does, you're in the 2–7% of pages that get sourced for that query. If it doesn't but competitors are cited, run their pages through the AEO checklist. FAQPage schema and answer-first formatting are usually the gap.
### The minimum viable AEO setup
If you want to start today with 30 minutes of work:
1. Add `User-agent: GPTBot / Allow: /` and similar for ClaudeBot, PerplexityBot to your robots.txt
2. Create a 200-word `llms.txt` at your root with your sitemap URL and preferred attribution format
3. Add FAQPage schema to your three best posts
4. Rewrite the opening paragraph of each post to directly answer the question in the title
That's it. Nothing else in the AEO checklist will have as much impact as those four actions. Do them before optimizing for any specific engine.
## Deciding whether to buy help
Everything above is the manual version. If you are a B2B SaaS team deciding whether to pay someone, the commercial questions have their own pages: [what an AI visibility audit should measure](/blog/ai-visibility-audit-b2b-saas) before you spend, [how to choose an AI SEO agency](/blog/how-to-choose-best-ai-seo-agency-b2b-saas) and [what a generative engine optimization agency should actually charge for](/blog/generative-engine-optimization-agency-what-you-pay-for) when comparing proposals, [what changes for an existing SaaS SEO budget](/blog/seo-for-saas-ai-search-era), and [whether you need a B2B SEO agency or an AI search specialist](/blog/b2b-seo-agency-vs-ai-search-specialist) at all.
## Advanced AEO: Beyond the 6 Factors
After the six core factors are in place, three techniques compound your AI visibility further: publishing an ai.txt policy file, implementing WebMCP so AI agents can query your site programmatically, and stacking entity mentions across Wikidata, GitHub, LinkedIn, and Crunchbase. These are differentiation plays, not baseline requirements.
### ai.txt: Declaring your AI interaction policy
While `llms.txt` tells AI crawlers what content to index and how to cite it, `ai.txt` goes further. It declares your site's full AI interaction policy including tool use, embedding permissions, and content licensing terms. Place it at `yoursite.com/ai.txt` alongside your `robots.txt` and `llms.txt`.
An `ai.txt` file signals to AI systems that your site is intentionally designed for AI interaction, not just passively crawlable. This is a differentiator: most sites are accidentally AI-visible (or accidentally invisible). A site with `ai.txt` is declaring intent, which AI systems can use as a trust signal.
### WebMCP: Making your site callable by AI agents
AEO gets your content cited in AI answers. WebMCP gets your content *used* by AI agents. WebMCP is a browser-side protocol that registers tools AI agents can call (search your site, query your data, interact with your product) directly from the browser context.
This is the frontier of AI-visible web architecture: a site that isn't just readable by AI, but usable by it. When an AI agent needs to find information in your domain, WebMCP lets it query your site programmatically rather than scraping HTML.
### Entity stacking: Building your knowledge graph footprint
AI engines identify entities (people, companies, products) by cross-referencing structured data across the web. The more high-authority platforms that contain consistent information about your entity, the more confidently AI engines will cite you.
Key platforms for entity stacking:
- **Wikidata:** Add a structured entry for yourself or your company. Wikidata is a primary knowledge source for most AI systems.
- **Crunchbase:** For companies and products. Crunchbase data feeds into multiple AI training pipelines.
- **GitHub:** Active repositories with clear README files and consistent author attribution.
- **LinkedIn:** Detailed profile matching your site's author schema exactly (same name, same title, same description).
- **Product Hunt:** For SaaS products. Product Hunt pages are high-authority and frequently cited by AI when discussing tools.
The key is consistency: the same name, same description, same URL across all platforms. Inconsistent entity data confuses AI systems and splits your citation authority across multiple "versions" of you.
### Topic hubs: Building topical authority for AI
AI engines evaluate topical authority differently than Google. Google uses backlinks as authority proxies. AI engines use content depth and internal linking density. A site with one article about AEO is a mention. A site with ten interconnected articles about AEO (definitions, tutorials, case studies, comparisons, tooling) is a topical authority.
Build topic hubs by:
1. **Writing a pillar article** (like this one) that defines the topic comprehensively.
2. **Creating supporting articles** that go deep on subtopics: each of the 6 factors, platform-specific guides, case studies, tool comparisons.
3. **Internal linking densely.** Every supporting article links to the pillar. The pillar links to every supporting article. AI engines follow these internal link graphs to gauge content depth.
4. **Using consistent terminology.** If your pillar calls it "Answer Engine Optimization," every supporting article should use the same phrase, not alternate between "AEO," "AI SEO," and "answer engine marketing."
---
## The Future is Plural Search
Over 30% of searchers now use AI answer engines for complex queries, and that share is growing monthly. AEO is not a replacement for SEO. It is a second optimization layer for a second type of search engine, one that extracts passages directly rather than ranking pages for users to click.
Google won't be the only search engine anymore. By 2026, over 30% of searchers use answer engines for complex queries. You need to be visible in *all* of them.
AEO isn't replacing SEO. It's extending your reach to a new search engine that's growing fast and underserved.
The technical foundation is the same as good SEO: well-structured, authoritative content with clear headings and direct answers. What changes is the mental model. SEO rewards findability: rank high enough and users click through. AEO rewards extractability: your H2 sections get lifted verbatim into AI responses. A page that ranks #3 on Google but buries its main answer in paragraph five won't get cited by AI even if Google loves it.
Write for systems extracting specific passages, not just readers scanning for reasons to click. Each H2 should be a complete, self-contained answer to the question it poses. Enough context to stand alone if extracted.
The easiest time to optimize for AEO was 2024. The second easiest time is today.
The six factors above are the whole method, and they are yours to run. If you would rather have the diagnosis handed to you, page by page, with the fixes already ordered, that is [the AEO audit I run at a fixed price](/services).
**Next:** Check out the [optimization checklist for AI search](/blog/how-to-optimize-for-perplexity-chatgpt-ai-search).
**See also:** [Why Domain Authority Is Irrelevant for AI Search (And What to Build Instead)](/blog/domain-authority-irrelevant-ai-search) and [How to Structure Content So AI Actually Cites Your URL](/blog/how-to-optimize-for-perplexity-chatgpt-ai-search)
--- END POST ---
================================================================================
POST: How to Test AI-Generated Code Before Shipping: 57 Bugs Caught
================================================================================
URL: https://chudi.dev/blog/ai-code-verification-evidence-based
Date: 2026-01-17T00:00:00.000Z
Tags: claude-code, ai, quality, verification, debugging
Pillar: ai-building
Reading Time: 9 min
Word Count: 1764
TL;DR: 'Should work.' The AI said it. I believed it. Six hours later, I was still debugging a fundamental error from line one. I trust AI completely. That's why I verify everything. The paradox makes sense once you've been burned enough. Forced evaluation mode achieves 84% compliance by requiring actual evidence before marking done.
Key Takeaways:
- Red flag phrases ('should work', 'probably fine', 'I'm confident') indicate confidence without evidence
- Three psychological traps: authority transfer, completion illusion, and optimism bias
- Forced evaluation protocol: evaluate each skill → activate every YES → then implement (84% compliance)
- Replace confidence claims with facts: 'Build completed: exit code 0', 'Tests passing: 47/47'
- Add verification hooks that reject red flag phrases and require evidence before task completion
--- CONTENT ---
"Should work." Six hours later, I was still debugging a fundamental error that had existed from line one. If your AI development workflow verification stops at a confident sentence from the model, that six hours is coming for you too, and it usually lands the week you can least afford it.
AI code verification means replacing model confidence with build output, test results, and concrete evidence before any task is treated as complete. That shift matters because AI-assisted development fails in predictable ways when proof is optional, not random ones. It is the same discipline behind my [Claude Code complete guide](/blog/claude-code-complete-guide), the implementation checks in [WebMCP for SvelteKit](/blog/webmcp-sveltekit-implementation), and the adversarial validation loop from [bug bounty false-positive reduction](/blog/bug-bounty-automation).
Evidence-based completion for AI code means blocking confidence phrases and requiring proof before any task is marked done. Not "should work"--actual build output. Not "looks good"--actual test results. The psychology is simple: confidence without evidence is gambling. Forced evaluation achieves 84% compliance because it makes evidence the only path forward. [Research on LLM reliability](https://arxiv.org/abs/2402.01680) confirms that AI-generated outputs require external verification to catch hallucinations and errors that models present with high confidence.
## Why Do We Skip Verification?
You skip verification because AI-generated code looks plausible and the model sounds confident, which triggers authority transfer, you treat the AI's certainty as evidence of correctness. Completion illusion makes the task feel done. Optimism bias means you want it to work. These three forces combine to make verification feel like unnecessary extra work.
The pattern is universal. You describe what you want. The AI generates code. It looks reasonable. You paste it in.
That moment of hesitation--the one where you could run the build, could write a test, could verify the output--gets skipped. The code looks right. The AI sounds confident. What could go wrong?
That specific shame of shipping broken code--the kind where you have to message the team "actually, there's an issue"--became my recurring experience.
I trust AI completely. That's why I verify everything.
The paradox makes sense once you've been burned enough times.
## What Makes "Should Work" Psychologically Dangerous?
"Should work" is dangerous because it substitutes confidence for evidence. The phrase triggers authority transfer, completion illusion, and optimism bias simultaneously, making you feel the task is finished when verification hasn't happened. You inherit the AI's certainty without inheriting any actual proof that the code functions correctly.
The phrase creates false confidence through three mechanisms:
### 1. Authority Transfer
The AI presents with confidence. We transfer that confidence to the code itself, as if certainty of delivery equals certainty of correctness.
### 2. Completion Illusion
"Should work" feels like a finished state. The task feels done. Moving to verification feels like extra work rather than essential work.
### 3. Optimism Bias
We want it to work. We've invested time. Verification risks discovering problems we'd rather not face.
I thought I was being thorough. Well, it's more like... I was being thorough at the wrong stage. Careful prompting, careless verification.
## What Phrases Trigger the Red Flag System?
The red flag system blocks phrases that express certainty without evidence: "Should work," "Probably fine," "I'm confident," "Looks good," "Seems correct," "That should do it," "We're good," "All set," and "It shouldn't cause issues." Each phrase indicates a completion claim unsupported by build output, test results, or any verifiable proof.
Here's the complete list that gets blocked:
Each of these phrases indicates a claim without evidence. They're not wrong to think--they're wrong to accept as completion.
## What Evidence Replaces Confidence Claims?
Specific, verifiable proof replaces confidence claims: build output showing exit code 0, test results listing pass counts like "47/47," screenshots at exact viewport widths, and Lighthouse scores with numeric values. These are facts, not feelings. Any completion claim must cite one of these evidence types before the task can be marked done.
The replacement is specific, verifiable proof:
### Build Evidence
```
Build completed successfully:
- Exit code: 0
- Duration: 9.51s
- Client bundle: 352KB
- No errors, 2 warnings (acceptable)
```
### Test Evidence
```
Tests passing: 47/47
- Unit tests: 32/32
- Integration tests: 15/15
- Coverage: 78%
```
### Visual Evidence
```
Screenshots captured:
- Mobile (375px): layout correct
- Tablet (768px): responsive breakpoint working
- Desktop (1440px): full layout verified
- Dark mode: all components themed
```
### Performance Evidence
```
Lighthouse scores:
- Performance: 94
- Accessibility: 98
- Best Practices: 100
- SEO: 100
Bundle size: 287KB (-3KB from previous)
```
That hollow confidence of claiming something works--replaced with facts that prove it.
## How Does Forced Evaluation Achieve 84% Compliance?
Forced evaluation achieves 84% compliance by requiring explicit commitment before implementation. You evaluate each skill as YES or NO with reasoning, activate every YES, then proceed. Writing "YES, need verification" creates accountability. Passive suggestions produced only 20% compliance because nothing required follow-through. The commitment mechanism is what converts intent into actual verification behavior.
Research on skill activation showed a stark difference, a pattern consistent with findings from the [NIST AI Risk Management Framework](https://www.nist.gov/publications/artificial-intelligence-risk-management-framework-ai-rmf-10) on the importance of structured validation in AI-assisted workflows:
- **Passive suggestions**: 20% actually followed
- **Forced evaluation**: 84% actually followed
The mechanism is a 3-step mandatory protocol:
### Step 1: EVALUATE
For each potentially relevant skill:
```
- master-debugging: YES - error pattern detected
- frontend-guidelines: NO - not UI work
- test-patterns: YES - need verification
```
### Step 2: ACTIVATE
For every YES answer:
```
Activating: master-debugging
Activating: test-patterns
```
### Step 3: IMPLEMENT
Only after evaluation and activation complete:
```
Proceeding with implementation...
```
The psychology works because evaluation creates commitment. Writing "YES - need verification" makes you accountable to the claim. Skipping feels like breaking a promise to yourself.
## What Are the 4 Pillars of Quality Gates?
The four pillars are State and Reactivity, Security and Validation, Integration Reality, and Failure Recovery. Every piece of verification maps to one of these categories. State checks confirm reactive patterns work. Security checks confirm inputs are sanitized. Integration checks confirm components are actually used. Failure checks confirm error boundaries and loading states exist.
Every verification maps to one of four pillars:
## How Does Self-Review Automation Work?
Self-review automation works by prompting the AI to critique its own output before marking anything complete. You ask it to review its architecture for issues, explain the end-to-end data flow, and predict how the solution could break in production. The AI is effective at finding problems in code, including its own, when explicitly asked.
The system includes prompts that make the AI review its own work:
### Primary Self-Review Prompts
1. "Review your own architecture for issues"
2. "Explain the end-to-end data flow"
3. "Predict how this could break in production"
### The Pattern
```
1. Generate solution
2. Self-review with prompts
3. Fix identified issues
4. Re-review
5. Only then mark complete
```
Self-review catches issues before they become bugs. The AI is good at finding problems in code--including its own code, when asked explicitly. [Anthropic's documentation](https://docs.anthropic.com) covers how to structure these review prompts for reliable results.
## What Happens When Verification Fails?
When verification fails, the system escalates through three levels. A soft block requests evidence when a red flag phrase appears. A hard block prevents completion when no evidence exists. A rollback trigger fires when critical functionality breaks after a completion is accepted. Each level makes cutting corners progressively harder, forcing evidence as the only path through.
The system handles failures through structured escalation:
### Level 1: Soft Block
Red flag phrase detected. Request clarification:
"You mentioned 'should work'. What specific evidence supports this? Please provide build output or test results."
### Level 2: Hard Block
Completion claimed without evidence. Block the completion:
"Task cannot be marked complete. Required: build output showing success OR test results passing."
### Level 3: Rollback Trigger
Critical functionality broken after completion:
"Verification failed post-completion. Initiating rollback to last known good state."
The escalation makes cutting corners progressively harder. Evidence is the only path through.
## FAQ: Implementing Verification Gates
**Why is 'should work' dangerous in AI development?**
It indicates a claim without evidence. The AI (or developer) is expressing confidence without verification. This confidence often masks untested assumptions, missing edge cases, or fundamental errors.
**What is forced evaluation mode?**
A mandatory 3-step protocol: evaluate each skill (YES/NO with reasoning), activate every YES, then implement. Research shows 84% compliance vs 20% with passive suggestions. The commitment mechanism creates follow-through.
**What phrases indicate unverified AI code?**
Red flags include: 'Should work', 'Probably fine', 'I'm confident', 'Looks good', 'Seems correct'. These all express certainty without evidence of testing, building, or verification.
**What evidence should replace confidence claims?**
Specific proof: 'Build completed: exit code 0', 'Tests passing: 47/47', 'Screenshot at 375px shows correct layout', 'Bundle size: 287KB'. Facts, not feelings.
**How do I implement verification gates for AI code?**
Add hooks that run after AI responses. Check for red flag phrases and reject them. Require build output, test results, or screenshots before marking tasks complete. Make evidence the only path forward.
---
## What 84% Compliance Actually Looks Like
The difference between passive suggestions and forced evaluation isn't subtle. Here's a real before/after from my workflow.
**Before: Passive verification (20% compliance)**
I'd finish a feature and the AI would say something like: "The authentication flow should work. I've added the JWT utility, updated the login endpoint, and configured the cookie settings."
I'd read that, nod, move on. Three hours later, a 500 error in production. The cookie wasn't being set correctly because the response headers weren't configured for httpOnly. The AI was confident. I trusted the confidence.
**After: Forced evaluation (84% compliance)**
Now the same session ends with:
```
Build evidence:
npm run build → exit code 0 (9.51s)
No TypeScript errors
Test evidence:
Auth flow test: PASS
Cookie setting test: PASS
JWT expiry test: PASS
Screenshots:
Login form: renders correctly at 375px
Session persistence: verified across refresh
```
The AI runs the build. Shows the output. Takes screenshots. States the exit code.
The 84% compliance number comes from sessions where I tracked whether I actually ran verification before marking tasks done. Forced evaluation--where the AI had to provide evidence before I'd accept completion--produced compliance in 84 out of 100 sessions. Passive suggestions produced it in about 20.
The remaining 16%? Those were genuine time-sensitive situations where I consciously chose to accept risk. That's fine. The point isn't 100% verification. It's making the default behavior evidence-based instead of confidence-based.
Every time I skipped verification and got lucky, it reinforced the wrong habit. Every time the build caught something I'd have shipped, it reinforced the right one. Eventually the new habit won.
I hated the extra friction at first. But I love the part where I stop spending evenings debugging production issues.
I thought the problem was AI accuracy. Well, it's more like... the problem was my verification laziness. The AI generates good code most of the time. But "most of the time" isn't good enough for production.
Maybe the goal isn't trusting AI less. Maybe it's trusting evidence more--and building systems that make "should work" impossible to accept.
If your team re-checks AI output by hand before it ships, you are paying twice for the same work: once for the AI to write it, once for a person to verify it wasn't lying. I build the verification gates that catch bad output before it reaches production, custom Claude Code pipelines, $2,000 to $5,000. [See how that engagement works](/services).
---
## Related Reading
This is part of the [Complete Claude Code Guide](/blog/claude-code-complete-guide). Continue with:
- [Quality Control System](/blog/how-i-build-with-claude-code) - Two-gate enforcement that blocks implementation until gates pass
- [Context Management](/blog/claude-context-management-dev-docs) - Dev docs workflow that prevents context amnesia
- [Token Optimization](/blog/reduce-ai-token-usage-progressive-disclosure) - Save 60% with progressive disclosure
--- END POST ---
================================================================================
POST: AI-First Product Development: 5 Products Shipped With Agents, Not IDE Plugins
================================================================================
URL: https://chudi.dev/blog/ai-first-product-development-future
Date: 2026-01-17T00:00:00.000Z
Tags: ai, future, philosophy, automation, software-development
Pillar: philosophy
Reading Time: 10 min
Word Count: 1913
TL;DR: We're at an inflection point. The current model, humans write code, AI assists, is already outdated. The future is AI-first: AI agents handle the development workflow, humans make strategic decisions. MicroSaaSBot shipped a production SaaS in 7 days. That's not a demo; it's a signal. The developers who thrive will be the ones who learn to orchestrate AI systems, not just prompt them.
Key Takeaways:
- The shift: from 'AI assists human coding' to 'AI develops, humans direct'
- MicroSaaSBot is proof of concept, complete workflow automation from idea to deployment
- Humans remain essential for: strategic decisions, user empathy, business judgment, edge cases
- The 10-year trajectory: most CRUD apps built by AI, developers focus on novel problems
- Skill evolution: prompt engineering → system orchestration → AI product management
--- CONTENT ---
AI-first product development means AI agents handle entire phases of the development lifecycle, from research and architecture to implementation and deployment, while humans review and approve output rather than writing first drafts. The bottleneck shifts from execution speed to decision quality. MicroSaaSBot proved this is viable today: it shipped StatementSync, a production SaaS with auth, file processing, and billing, in 7 days.
The way we build software is about to change fundamentally.
Not gradually. Not incrementally. Fundamentally.
I built MicroSaaSBot as a bet on this future. Here's the thesis.
AI-first product development means AI agents handle entire phases of the development lifecycle, not just code completion. Research, architecture, implementation, and deployment become orchestrated agent workflows. The bottleneck shifts from execution speed to problem selection and quality control. Here's what that looks like in practice.
## What Is AI-First Product Development?
AI-first product development means AI agents handle entire phases of the development lifecycle, research, architecture, implementation, and deployment, rather than just assisting with code completion. Humans shift from writing code to reviewing and approving agent output, with the bottleneck moving from execution speed to decision quality.
## The Current Paradigm
Today's AI coding tools follow a pattern:
**Human writes code → AI assists**
- Copilot completes your lines
- Cursor edits your files
- ChatGPT answers your questions
The human remains the driver. AI is the passenger offering suggestions.
This works. It's faster than coding alone. But it's not where we're heading.
## The Next Paradigm
The future inverts the relationship:
**AI develops → Human directs**
- AI handles the development workflow
- Human makes strategic decisions
- AI executes, human evaluates
MicroSaaSBot is an early implementation of this pattern. It takes a problem statement and outputs a deployed product. The human approves phases, not lines of code.
## Why Is the Shift to AI-First Development Happening Now?
Three forces are driving the shift: AI capability has reached production quality, the bottleneck has moved from "can AI write code" to "can we orchestrate AI effectively," and economic pressure is overwhelming. When AI can ship an MVP in seven days instead of seven weeks, companies that don't adopt AI-first workflows get outcompeted by those that do.
## Why This Shift Is Happening
### 1. AI capabilities are sufficient
GPT-5 and Claude can:
- Write production-quality code
- Understand complex architectures
- Debug non-trivial problems
- Follow multi-step instructions
The capability gap between "AI assists" and "AI develops" has closed.
### 2. The bottleneck has moved
In 2015, the bottleneck was "can AI write correct code?"
In 2020, the bottleneck was "can AI understand context?"
In 2025, the bottleneck is "can we orchestrate AI effectively?"
The hard problem isn't AI capability, it's system design.
### 3. Economic pressure is real
Developers are expensive. Development takes time. Startups need to move fast.
If AI can ship an MVP in 7 days instead of 7 weeks, the economic incentive is overwhelming. Companies that don't adopt AI-first development will be outcompeted by those that do.
## What MicroSaaSBot Proves
StatementSync is not a demo. It's a production SaaS with:
- Real user authentication
- Real file processing
- Real payment collection
- Real customer value
Built in 7 days by AI agents with human oversight.
MicroSaaSBot isn't special because it uses AI. It's special because it treats AI as the developer, not the assistant. The architecture assumes AI does the work; humans make decisions.
This pattern, AI executes, humans direct, is the future of product development.
## What Do Humans Still Do Better Than AI in Development?
Humans remain essential for strategic decisions about what to build and for whom, user empathy that goes beyond pattern analysis, edge cases where standard patterns break, novel architectural problems that require extrapolation into the unknown, and accountability, AI cannot be held responsible for failures in any meaningful sense.
## What Humans Still Do Better
AI-first doesn't mean human-free.
**Strategic decisions**: What should we build? For whom? At what price? AI can provide data, but humans make judgment calls.
**User empathy**: Understanding why users behave the way they do. AI can analyze patterns; humans can feel friction.
**Edge cases**: When the standard pattern doesn't apply. AI follows learned patterns; humans recognize when patterns break.
**Novel problems**: Truly new architectures, unprecedented challenges. AI interpolates from training data; humans extrapolate into the unknown.
**Accountability**: When things break, humans are responsible. AI can't be held accountable in any meaningful sense, a principle formalized in the [NIST AI Risk Management Framework](https://www.nist.gov/publications/artificial-intelligence-risk-management-framework-ai-rmf-10), which places governance responsibility on human operators.
The future isn't AI replacing humans. It's AI handling the 80% of development that's pattern-matching while humans focus on the 20% that requires judgment.
## The 10-Year Trajectory
**2025**: Early adopters use AI-first for MVPs. Most developers still write code with AI assistance.
**2027**: AI-first becomes standard for startups building standard apps (CRUD, dashboards, content platforms). Custom work still human-heavy.
**2030**: Most web applications built primarily by AI. Developers focus on novel systems, AI orchestration, and edge cases.
**2035**: "Manual coding" becomes a specialist skill like assembly programming today, valuable but niche.
This isn't speculation. It's extrapolation from current trends. Claude and GPT-5 can already build production apps. The only questions are: How fast does adoption happen? How quickly do the tools improve?
## Skill Evolution
The skills that matter are shifting:
**Yesterday** (2020):
- Writing clean code
- Knowing frameworks deeply
- Debugging efficiently
**Today** (2025):
- Prompt engineering
- AI output evaluation
- Hybrid human-AI workflows
**Tomorrow** (2030):
- System orchestration
- AI product management
- Edge case handling
- Domain expertise
The trajectory is clear: from "writing code" to "directing systems."
## What This Means for Developers
### If you're junior:
Learn fundamentals, you still need to evaluate AI output. But also learn AI orchestration early. The developers entering the field in 2025 who master AI-first development will have a massive advantage.
### If you're senior:
Your judgment is more valuable than ever. AI can write code; it can't decide what to build or evaluate whether it's good. Your architecture skills, debugging intuition, and domain knowledge become leverage points.
### If you're a founder:
Start using AI-first development now. The time savings are real. MicroSaaSBot shipped StatementSync in 7 days, that's 6 weeks of developer time saved. At $150/hour, that's $36,000 per product.
## The Transition Challenge
Not everyone will make this transition gracefully.
**Developers who resist**: "AI can't write real code." They'll be outcompeted by those who embrace AI-first development. The code quality debates will persist until economic pressure overwhelms them.
**Developers who over-rely**: "AI can do everything." They'll ship buggy products, miss edge cases, and lack the judgment to improve. Over-reliance is as dangerous as resistance.
**Developers who adapt**: "AI is a powerful tool I can orchestrate." They'll ship faster, focus on high-value problems, and remain relevant as the field evolves, building the kind of responsible, accountable systems the [NIST AI Risk Management Framework](https://www.nist.gov/publications/artificial-intelligence-risk-management-framework-ai-rmf-10) calls for.
If your job is primarily writing CRUD applications and standard API endpoints, that job is being automated. The question isn't whether, it's when. Prepare now.
## My Bet
MicroSaaSBot is my bet on this future.
I built it because I believe:
1. AI-first development is viable today
2. The pattern will become dominant
3. Those who master it early will have advantages
StatementSync proves viability. Now I'm scaling further, more products, more complex systems, more [autonomous workflows](/blog/openclaw-autonomous-blog-agent).
The future isn't AI replacing developers. It's developers who orchestrate AI systems outcompeting developers who don't.
Which side will you be on?
## What AI-First Actually Means in Practice
"AI-first" gets used to mean a lot of things. Let me be specific about what it meant for StatementSync.
It meant the Researcher agent did the market analysis--competitor pricing, user pain point research, willingness-to-pay signals--before I looked at any of it. I reviewed the output, not the raw data.
It meant the Architect agent designed the database schema based on the validation report. I reviewed the schema. I didn't draft it.
It meant the Developer agent wrote the PDF parsing logic, the Stripe webhook handlers, the SvelteKit routes. I reviewed the code for correctness and edge cases. I didn't write the first draft.
It meant the Deployer agent configured the Vercel project, set up the Supabase database, connected the Stripe webhooks. I verified the live URL worked. I didn't run the deployment commands.
My job was reviewing and approving, not executing. That's a fundamentally different role than "developer who uses AI for autocomplete."
The concrete result: I shipped a production SaaS with auth, file processing, and billing in 7 days. Not 7 weeks. The constraint wasn't my ability to write code--it was the time required to make good decisions about what to build and whether the implementation was sound.
AI-first removes execution time from the critical path. Decision time remains. The complete day-by-day breakdown of how this played out for StatementSync is in [MicroSaaSBot: Idea to Deployed MVP](/blog/introducing-microsaasbot-ai-builds-saas).
That's what it actually means.
## How Do You Transition to an AI-First Workflow?
Stop writing first drafts and start reviewing AI's first drafts instead. Stop treating AI output as final without verification. Stop loading maximum context, focused input produces better output. Stop accepting "should work" without evidence. The transition takes a few weeks and includes a productivity dip before you emerge shipping significantly faster than before.
## The Transition: What to Stop Doing Now
The shift to AI-first doesn't happen all at once. But there are specific habits that slow the transition down. I had to stop doing all of these.
**Stop writing first drafts.** This was the hardest one. My instinct was to sketch out a function, then ask AI to improve it. That's backwards. Ask AI for the first draft. Then review, critique, and improve. The first draft is the cheap part--reviewing is the valuable part.
**Stop treating AI output as final.** The opposite failure. Paste the output in, ship it, find the bug in production. AI-first still requires evaluation. It just moves evaluation earlier in the workflow.
**Stop loading maximum context.** If you're giving AI everything--all the docs, all the files, all the rules--you're not being thorough, you're creating noise. Focused context produces better output. I learned this from building the [progressive disclosure system](/blog/reduce-ai-token-usage-progressive-disclosure) for my Claude setup.
**Stop accepting "should work."** The phrase indicates an unverified claim. AI-first development requires the same evidence standard as any other development. Build passes. Tests pass. Screenshots confirm. No exceptions.
**Stop thinking in files.** Human coding is file-centric: open a file, edit it, save it. AI-first development is task-centric: define the outcome, let the agent figure out which files to touch. Fighting your way back to file-centric thinking when using AI adds unnecessary friction.
The transition takes a few weeks. There's a dip in productivity while you unlearn habits that served you well in the old model. Then you come out the other side shipping faster than before.
I went through this transition over about 3 months. The first month was slower. The third month shipped more than the previous three months combined.
## The Opportunity
Right now, most developers use AI like a fancy autocomplete. A few of us are building systems where AI does the development and humans make decisions.
This gap, between AI-as-assistant and AI-as-developer, is the opportunity.
MicroSaaSBot isn't the only path. But it's proof that the path exists. AI-first product development isn't a vision for 2030. It's working code in 2025.
The future is already here. It's just not evenly distributed.
---
**Related**: [Introducing MicroSaaSBot](/blog/introducing-microsaasbot-ai-builds-saas) | [Portfolio: MicroSaaSBot](/portfolio/microsaasbot)
--- END POST ---
================================================================================
POST: Claude Code Best Practices 2026: What the Official Docs Don't Cover
================================================================================
URL: https://chudi.dev/blog/claude-code-complete-guide
Date: 2026-01-17T00:00:00.000Z
Tags: claude-code, ai, workflow, tutorial, productivity
Pillar: ai-building
Reading Time: 19 min
Word Count: 3694
TL;DR: I shipped broken code three times in one week. The AI said 'should work.' Without me realizing it, I was trusting confidence over evidence. This guide covers the system I built: two-gate quality control, context management with dev docs, and progressive disclosure. Well, it's more like a complete shift in how I work with AI.
Key Takeaways:
- Two-gate system blocks implementation until quality checks pass, eliminating 'should work' claims
- Dev docs (plan.md, context.md, tasks.md) prevent context amnesia across sessions
- Progressive disclosure saves 60% tokens by loading skill metadata first, full content on demand
- Evidence-based completion requires actual build output, test results, or screenshots before marking done
- The goal isn't trusting AI less. It's trusting evidence more
--- CONTENT ---
The official Claude Code docs cover installation and commands. They do not cover what keeps AI-generated code from breaking in production. Here are the five practices that held up across 36,000 lines of shipped code: plan before touching multiple files, persist decisions in dev docs so context survives compaction, require build output and test results before accepting any completion claim, load context progressively, and run regression checks after every bounded change.
A production Claude Code workflow has five layers: plan the bounded change, load only relevant context, persist decisions outside the conversation, require tool-produced verification, and record enough state to recover after compaction. Everything else in this guide supports one of those five layers.
I shipped broken code three times in one week. The AI said "should work." I believed it.
That experience led me to build a complete system for AI-assisted development, one where evidence replaces confidence, context persists across sessions, and quality gates make cutting corners impossible.
This guide covers everything I've learned building with Claude Code, most of it shipped inside a [36,000-line production trading bot](/blog/claude-code-production-trading-bot) that runs real money.
## Which Claude Code best practices actually survive production?
The Claude Code best practices that held up in a production trading system are: plan before changing multiple files, persist decisions in dev docs, require build and test evidence before accepting completion, load context progressively, and run regression checks after every bounded change. These are operating rules from a real trading codebase, not a list of features. Together, they kept context accurate as the codebase grew and blocked silent production bugs before they reached live capital.
Anthropic's documentation explains what Claude Code can do. This field guide explains how I operate it when failed output has a real cost: every non-trivial task gets a written boundary, every long session leaves a recoverable state, and every completion claim needs a receipt.
| Practice | Production rule | Failure it prevents |
|----------|-----------------|---------------------|
| Plan before code | Write and approve a plan before work that crosses multiple files | Confident changes that conflict with existing architecture |
| Persist context | Keep plan.md, context.md, and tasks.md outside the chat window | Lost decisions after compaction or a new session |
| Demand evidence | Require type checks, tests, builds, or screenshots | Accepting "should work" as completion |
| Load progressively | Start with the project map, then load only task-relevant files | Token waste and stale-context hallucinations |
| Check regressions | Run the smallest relevant check, then type checks, tests, and the production build before shipping | Fixing one path while quietly breaking another |
| Before Claude edits | While Claude works | Before accepting completion |
|---|---|---|
| Define the requested outcome and excluded scope | Keep the change bounded to one testable unit | Inspect the actual diff |
| Identify affected files and dependencies | Load only task-relevant context | Run the smallest relevant test |
| Write a plan for multi-file work | Update persistent task state after decisions | Run type checks and the production build when applicable |
| Select the model and effort tier by workload | Stop when evidence contradicts the plan | Require logs, screenshots, or command output |
## What Is Claude Code and How Is It Different From Cursor or Copilot?
Claude Code is Anthropic's CLI tool that runs in your terminal with full codebase access and agentic capabilities. Unlike Cursor or Copilot, IDE plugins focused on inline completions, Claude Code can execute commands, manage files, run builds, and maintain context across long sessions through persistent dev docs rather than stateless chat.
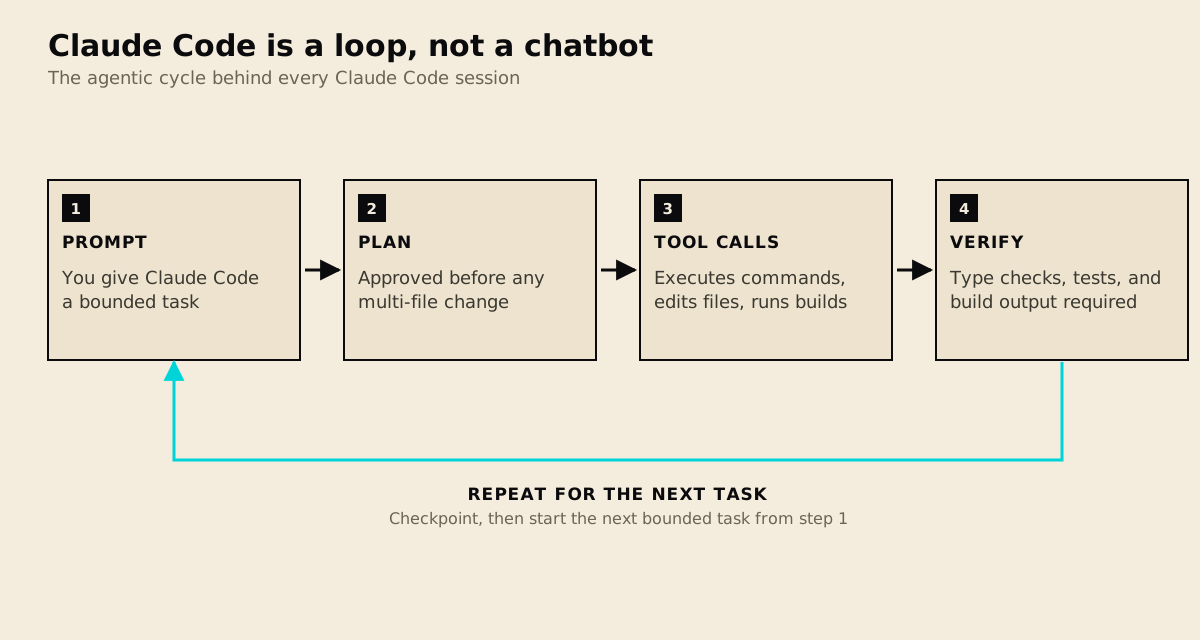
*Claude Code doesn't just answer once. Each task cycles through planning, tool calls, and evidence-based verification, then the loop repeats for the next bounded task instead of ending the conversation. That cycle, not the chat window, is the mental model for the rest of this guide.*
## How is this Claude Code guide organized?
This guide is organized into four core areas:
## What is the minimum production-safe Claude Code workflow?
The minimum production-safe workflow is plan, implement, verify, and preserve state. Plan before multi-file work. Implement one bounded unit. Verify it with a diff and the cheapest reliable test. Preserve decisions in dev docs before the context is compacted or the session ends. Skipping any one of these stages creates a predictable failure: architectural drift, oversized changes, unsupported completion claims, or lost context.
Model selection belongs inside that workflow rather than above it. [Choose the Claude model and effort tier by workload](/blog/claude-fable-5-vs-opus-4-8). Since Opus 5.5 shipped, [my Opus 5.5 vs Fable 5.1 cost-per-turn replay](/blog/claude-opus-5-5-vs-fable-5-1) shows Fable now costing 2.3x Opus per turn on my measured day. Then preserve the result with [the complete three-file context-compaction workflow](/blog/claude-context-management-dev-docs). The system has been exercised in [a 36,000-line trading-bot case study](/blog/claude-code-production-trading-bot) and in [evidence-gated automation for security workflows](/blog/bug-bounty-automation).
## How Does the Two-Gate System Prevent Broken AI Code?
Gate 0 validates your context budget and loads phrase blocking to prevent "should work" claims. Gate 1 analyzes your query and activates the relevant skills from a library of 30-plus defined patterns. Both gates must pass before any implementation tools unlock, making unverified confidence structurally impossible rather than something that relies on discipline.
## Part 1: Quality Control That Actually Works
The biggest mistake in AI-assisted development is accepting confidence as evidence.
When Claude says "should work," that's not verification, it's a guess. The two-gate system I built makes guessing impossible by blocking all implementation tools until quality checks pass.
For the complete breakdown of gates, phrase blocking, and the 4 pillars of quality, read: **[I Built a Quality Control System for AI Code Generation](/blog/how-i-build-with-claude-code)**
### The Core Principle
**Gate 0: Meta-Orchestration**
- Validates context budget (under 75%)
- Loads quality gates and phrase blocking
- Initializes the skill system
**Gate 1: Auto-Skill Activation**
- Analyzes your query intent
- Matches against 30+ defined skills
- Activates top 5 relevant skills
Only after both gates pass can you write code. Like buttoning a shirt from the first hole, skip it, and everything else is wrong.
### Evidence Over Confidence
These phrases get blocked:
| Red Flag | Problem |
|----------|---------|
| "Should work" | No verification |
| "Probably fine" | Uncertainty masked as completion |
| "I'm confident" | Feeling, not fact |
| "Looks good" | Visual assessment, not testing |
**Replace with evidence:**
```
Build completed: exit code 0, 9.51s
Tests passing: 47/47
Bundle size: 287KB
```
For the complete verification system including the 84% compliance protocol, see the [full quality control guide](/blog/how-i-build-with-claude-code).
---
## How Do You Stop Claude From Forgetting Context Between Sessions?
Create three dev doc files for every non-trivial task: plan.md as the approved implementation blueprint, context.md as a living record of current progress and key decisions, and tasks.md as a granular checklist. Before context compacts, run /update-dev-docs. After compaction, say "continue" and Claude reads the files automatically, no re-explaining required.
## Part 2: Context Management
"We already discussed this."
I said it. Claude didn't remember. Thirty minutes of context, file locations, decisions, progress, gone after compaction.
The dev docs workflow solves this permanently.
For the complete dev docs workflow including automation hooks, read: **[How to Prevent Claude from Forgetting Your Task](/blog/claude-context-management-dev-docs)**
Building with ADHD? The [ADHD-friendly Claude Code workflow](/blog/claude-adhd-executive-function-mode) adapts this for executive-function friction.
### The Three Dev Doc Files
Every non-trivial task gets a directory:
```
~/dev/active/[task-name]/
├── [task-name]-plan.md # Approved blueprint
├── [task-name]-context.md # Living state
└── [task-name]-tasks.md # Checklist
```
**plan.md**: The implementation plan, approved before coding. Doesn't change during work.
**context.md**: Current progress, key findings, blockers. Updated frequently.
**tasks.md**: Granular work items with status. Check items as you complete them.
### The Magic Moment
```
[Context compacted]
You: "continue"
Claude: [Reads dev docs automatically, knows exactly where you are]
```
No re-explaining. No lost progress. Just continuation.
When to use dev docs:
- Any task taking more than 30 minutes
- Multi-session work
- Complex features with multiple files
- Anything you'd hate to re-explain
For the complete workflow including 16 automation hooks, see the [context management guide](/blog/claude-context-management-dev-docs).
---
## Part 3: Token Optimization
Most Claude configurations load everything upfront. Every skill, every rule, every example, thousands of tokens consumed before you've asked a question.
Progressive disclosure flips this.
For the complete progressive disclosure implementation, read: **[How to Reduce AI Token Usage by 60%](/blog/reduce-ai-token-usage-progressive-disclosure)**
Tokens also decide how fast a Pro or Max plan runs out, because Claude Code shares one usage limit with claude.ai. [Claude usage limits](/blog/claude-usage-limits) explains the five-hour session and the weekly cap, [Claude Code usage limits](/blog/claude-code-quota-burn-10-patterns) covers what burns that limit inside Claude Code, and [Claude pricing](/blog/claude-pricing) lists every plan and API price.
### The 3-Tier System
| Tier | Content | Tokens | When Loaded |
|------|---------|--------|-------------|
| 1 | Metadata | ~200 | Immediately |
| 2 | Schema | ~400 | First tool use |
| 3 | Full | ~1200 | On demand |
**Tier 1**: Skill name, triggers, dependencies. Just enough to route the query.
**Tier 2**: Input/output types, constraints, tools available.
**Tier 3**: Complete handler logic, examples, edge cases.
The meta-orchestration skill alone: 278 lines at Tier 1, 816 with one reference, 3,302 fully loaded. That's 60% savings on every session that doesn't need the full content.
For implementation details and your own skill definitions, see the [token optimization guide](/blog/reduce-ai-token-usage-progressive-disclosure).
---
## Part 4: Foundational Concepts
Before building complex AI workflows, you need to understand the underlying patterns.
### RAG: Retrieval-Augmented Generation
RAG gives LLMs access to external knowledge at inference time. [Introduced in a 2020 Meta AI paper](https://arxiv.org/abs/2005.11401) and now foundational to production AI systems, RAG pulls in relevant documents before generating, rather than relying solely on training data with a fixed knowledge cutoff.
For the complete RAG explanation with code examples, read: **[What is RAG? Retrieval-Augmented Generation Explained](/blog/what-is-rag)**
**The pattern:**
1. Query Processing → 2. Retrieval → 3. Augmentation → 4. Generation
Every time you feed context to Claude before asking questions, you're using RAG. The dev docs workflow is essentially manual RAG, retrieving your context files before generation.
### Evidence-Based Verification
"Should work" is the most dangerous phrase in AI development. It indicates confidence without evidence.
For the psychology of verification and the 84% compliance protocol, read: **[Why 'Should Work' Is the Most Dangerous Phrase](/blog/ai-code-verification-evidence-based)**
**The forced evaluation protocol:**
1. EVALUATE: Score each skill YES/NO with reasoning
2. ACTIVATE: Invoke every YES skill
3. IMPLEMENT: Only then proceed
Research shows 84% compliance with forced evaluation vs 20% with passive suggestions. The commitment mechanism creates follow-through.
---
## What Are the Most Common Claude Code Mistakes to Avoid?
Four mistakes account for most Claude Code failures: writing context in chat instead of files, using Claude to make decisions rather than execute bounded tasks, skipping gate checks when tired or rushed, and letting sessions run for hours without checkpointing. The last one degrades output quality as abandoned approaches and recovered errors accumulate in the context window.
## Part 5: Common Failure Modes
After building the quality control system, I've watched colleagues start using Claude Code and make the same mistakes. These are the ones worth knowing before you hit them.
### Treating every task as a conversation
Claude Code's memory resets at the start of each session. Most people know this. But they still write context in chat messages instead of files. "Remember that we're using PostgreSQL, not MySQL" gets lost when context compacts. Write it in a file once, reference the file every session.
The dev docs workflow exists precisely for this. Before any significant session, start with: "Read context.md and give me a brief on where we are." Five seconds, no lost context.
### Using Claude for decisions instead of execution
Claude Code is a tool for doing things, not deciding what to do. If you're asking it "should I use Redux or Zustand?" or "is this architecture good?", you're using it wrong. Make the decision yourself (or with a separate research session), then give Claude Code a clear, bounded task.
The clearer your input, the higher the quality of your output. "Implement a Redux store for auth state with these specific actions" produces better results than "help me set up state management."
### Skipping the gate check when tired
The two-gate system works when you follow it and fails immediately when you skip it. The temptation to skip is highest when you're tired, rushing, or "just need to make one small change." That's exactly when it matters most. Small unverified changes in tired states are where production bugs come from. In my [Claude Code trading bot](/blog/claude-code-production-trading-bot), this system caught 8 silent bugs over four months before any of them touched live capital.
The gate isn't bureaucracy. It's the system protecting you from yourself at 11 PM.
### Letting context balloon without checkpointing
A session that starts with a clear task and runs for three hours without checkpointing will start producing worse results as context fills. Claude Code sees everything in the window, including the tentative approaches you abandoned, the errors you hit and recovered from, the exploratory tangents. All of that degrades signal.
Checkpoint every 45–60 minutes on long tasks. Run `/update-dev-docs`. The next sub-session starts clean. Quality stays high.
## Part 6: Adapting to Your Stack
The gates, dev docs, and progressive disclosure patterns work across stacks. But how you apply them varies by project type.
### SvelteKit + Static Sites
The context file structure for a SvelteKit project should reflect the routing model. Your context.md should document which routes are prerendered, which are server-side, and which are client-side, because Claude will make different assumptions about data loading depending on what it thinks the rendering strategy is.
One mistake I made early: assuming Claude remembered that a specific route was prerendered. It didn't. Every session it would suggest server-side loading patterns that don't apply to static routes. A two-line note in context.md, "route /blog is prerendered, no server hooks, use data exported from +page.ts", eliminated that class of confusion entirely.
The build gate matters more for SvelteKit than some other stacks because the static adapter has strict requirements. Dynamic imports, server-only code in client components, and missing types cause build failures that don't surface in dev mode. Make `pnpm build` non-negotiable before marking any task complete.
### Next.js App Router
The App Router's server component versus client component distinction is the most common source of confusion in Claude Code sessions. Claude will occasionally suggest a hook or browser API inside a server component, or vice versa.
Capture the component hierarchy in your context.md: which components are server components (no `'use client'`), which are client components, and which are shared utilities. This isn't excessive documentation, it's the exact information Claude needs to avoid the most common class of error.
Evidence gate addition for Next.js: add `tsc --noEmit` to your gate checklist. TypeScript errors in App Router code often don't surface until type-checking because the dev server is permissive.
### Pure API Projects
API-only projects benefit most from the dev docs workflow because the relevant context is all in files, no visual output to check, no screenshots, just data shapes and endpoint contracts.
Your context.md for an API project should always include: the current database schema, the authentication model, and the active endpoints with their expected inputs and outputs. Keep it to one page. If it's longer, you're capturing implementation details that belong in code comments, not context.
For evidence gates, add a smoke test to the checklist: one curl command per major endpoint that should return a 200. Not comprehensive integration tests, just enough to confirm the service is responding correctly before you consider the session complete.
### Long-Running Projects
The three-file dev docs structure was designed for task-level work, features and bug fixes that complete in days. For projects that run months, add a fourth file: `project-context.md`.
`project-context.md` captures what doesn't change session-to-session: the architectural decisions, the tech stack choices and the reasons for them, the non-negotiable constraints, and the vocabulary the codebase uses. What the project calls "users" versus "accounts" versus "members" matters more than you'd expect.
This file gets read at the start of every session, before context.md. It's the stable foundation that prevents Claude from proposing changes that would violate architectural constraints established months ago.
The investment: 30 minutes once, saved every session for the life of the project.
## Getting Started
If you would rather start from a preconfigured baseline than build this by hand, the [Claude Code setup kit](/claude-code-setup) packages the structure below.
### Minimum Viable Setup
1. **Create a CLAUDE.md** in your project root with basic gate enforcement
2. **Set up a dev/ directory** for task documentation
3. **Add "continue" handling** to resume after compaction
### Full Setup
1. Install the dev docs commands (slash commands or aliases)
2. Configure hooks for automatic skill activation
3. Set up build checking on Stop events
4. Create workspace structure for multi-repo projects
The full system takes a few hours to configure. But it saves that time on every long task thereafter.
---
## Related Guides
### Claude Code Fundamentals
- [Quality Control System](/blog/how-i-build-with-claude-code) - Two-gate enforcement, phrase blocking
- [Context Management](/blog/claude-context-management-dev-docs) - Dev docs, automation hooks
- [Token Optimization](/blog/reduce-ai-token-usage-progressive-disclosure) - Progressive disclosure, 60% savings
### Foundational Concepts
- [What is RAG?](/blog/what-is-rag) - Retrieval-augmented generation explained
- [Evidence-Based Verification](/blog/ai-code-verification-evidence-based) - Why "should work" fails
---
## 2026 Update: Computer Use and Browser Automation
Claude Code now supports computer use through MCP (Model Context Protocol) tools. This means Claude can control your desktop, browser, and applications directly from the terminal.
MCP servers also feed Claude framework knowledge it would otherwise guess at. For one worked example, see [the official Svelte MCP server and what its autofixer found in 134 SvelteKit components](/blog/sveltekit-mcp-server-claude-code).
### What Computer Use Enables
- **Browser automation**: Navigate websites, fill forms, click buttons, and extract data through Chrome DevTools integration
- **Desktop control**: Launch applications, take screenshots, type text, and interact with native UI elements
- **Multi-tool orchestration**: Combine file editing, terminal commands, and browser automation in a single workflow
### Setting Up Computer Use
Computer use requires the Claude in Chrome extension and the computer-use MCP server. Once connected, Claude can:
1. Open URLs and navigate between pages
2. Read page content and execute JavaScript
3. Fill forms and submit data
4. Take screenshots for visual verification
5. Control desktop applications via accessibility APIs
### Practical Applications
The combination of terminal access and browser control creates workflows that were previously impossible:
- **Deploy and verify**: Push code to production, then open the browser to visually confirm the deployment worked
- **SEO auditing**: Check meta tags, structured data, and page content across multiple URLs programmatically
- **Form testing**: Fill out multi-step forms to verify validation logic and submission flows
- **Cross-platform automation**: Edit code in the terminal, test it in the browser, and document results, all in one session
This represents a shift from Claude Code as a coding assistant to Claude Code as a full development environment that spans terminal, editor, and browser.
### Hooks: Automating Quality Gates
Claude Code hooks let you run custom scripts at specific lifecycle events: PreToolUse (before a tool runs), PostToolUse (after a tool runs), Notification, and Stop. This turns manual quality checks into automated enforcement.
For example, a PreToolUse hook can block file writes to production config files. A PostToolUse hook can run linting after every code edit. A Stop hook can enforce that the build passes before the session ends.
The hook script receives event data on stdin and must return JSON with `{"continue": true}` to proceed. Here is a minimal Stop hook that checks the build:
```json
{
"hooks": {
"Stop": [{
"type": "command",
"command": "/bin/bash ~/.claude/scripts/check_build.sh"
}]
}
}
```
Hooks are configured in `~/.claude/settings.json` and run synchronously (blocking) or asynchronously (fire-and-forget) depending on the event type. For a complete implementation walkthrough, see [Claude Code Hooks Tutorial](/blog/claude-code-hooks-tutorial).
To choose between a hook, a skill, a subagent and a CLAUDE.md line, see [Claude Code skills vs subagents](/blog/claude-code-skills-vs-subagents). To write your first skill, see [Claude Code skills](/blog/claude-code-skills). If your repo also keeps an AGENTS.md, [Claude Code and AGENTS.md](/blog/claude-code-agents-md) covers how the two files load.
### Multi-Agent Orchestration
Claude Code supports spawning sub-agents for parallel task execution. Each agent runs in its own context with access to specified tools, and results flow back to the parent session.
Common patterns:
- **Parallel search**: Spawn multiple Haiku agents to explore different parts of a codebase simultaneously
- **Build and test**: Run a build-fixer agent alongside a test-runner agent after making changes
- **Code review pipeline**: Use a Haiku triage agent for fast first-pass review, then an Opus agent for deep analysis on flagged items
Agent isolation via git worktrees prevents concurrent agents from corrupting each other's file changes. Read-only agents (exploration, review) do not need isolation. Write agents always should use it.
### The Gate-Receipt Pattern: Quality Gates That Survive Automation
Quality gates that need judgment, like whether content reads as human-written or a title survives mobile truncation, run as Claude-invoked skills that need a live session. Cron jobs have none. The gate-receipt pattern bridges them: the skill writes a small receipt file when it runs, and the automated script refuses to proceed without a passing one.
Concretely: when the gate skill finishes, it writes `gate-receipts/- .json` with its verdict and score. The cron-runnable pipeline reads that file before any irreversible step (publishing, submitting, deploying) and blocks if the receipt is missing or marks a failure. The judgment happens in the session where it belongs; the determinism happens in cron where it scales.
Without this, you get one of two bad outcomes: drop the subjective gate and let an unattended pipeline ship slop, or block the whole pipeline on a human and lose the automation. The receipt is the contract between the two layers, and it is the only way I have found to put a judgment call inside a job that runs with nobody watching.
---
## The Bottom Line
[Claude Code](https://docs.anthropic.com/en/docs/claude-code) isn't just a code generator. With the right systems, it becomes a quality-controlled collaborator.
The goal isn't trusting AI less. It's trusting evidence more, and building systems that make "should work" impossible to accept.
Start with dev docs. Add the gate system. Implement progressive disclosure. Each piece builds on the last.
The AI was always capable. We just needed guardrails that made evidence the only path forward.
---
`WORK WITH ME · SAME PROCESS, YOUR REPO`
> If your team re-checks AI output by hand before every deploy, you are paying twice for the same work. I build custom Claude Code pipelines, $2,000 to $5,000 with a written scope and a fixed quote, that wire these hooks, gates, and multi-agent workflows directly into your repo. [See how the engagement works](/services).
--- END POST ---
================================================================================
POST: Claude Code 'Compaction Failed': Causes and 3 Fixes
================================================================================
URL: https://chudi.dev/blog/claude-context-management-dev-docs
Date: 2026-01-17T00:00:00.000Z
Tags: claude-code, ai, workflow, context, productivity
Pillar: ai-building
Reading Time: 20 min
Word Count: 3973
TL;DR: 'We already discussed this.' I said it. Claude didn't remember. Thirty minutes of context gone after compaction. Dev docs are three files that persist task state outside the conversation. Before compaction, run /update-dev-docs. After compaction, say 'continue' and Claude picks up exactly where you left off.
Key Takeaways:
- Context compaction loses file paths, decisions, and progress state. The 'we already discussed this' moment becomes your weekly reality
- Three dev doc files: plan.md (approved strategy), context.md (key files and decisions), tasks.md (checklist)
- Workflow: plan mode then /create-dev-docs then implement 1-2 sections then review then /update-dev-docs before compaction
- Automation hooks handle quality control: UserPromptSubmit (skill activation), Stop-BuildChecker (automatic builds)
- Use dev docs for tasks over 30 minutes or spanning multiple sessions. Skip for quick one-off fixes
--- CONTENT ---
If Claude Code shows "compaction failed, conversation could not be reduced below the context limit", or simply forgets what you discussed after compaction, the state you needed lived only in the conversation. If you got a different message, such as "summarization failed: generation hit the token cap", the cause is different and [the section on the other compaction errors](#what-do-the-other-claude-code-compaction-errors-mean) covers it. This is the context management module of the [complete Claude Code guide](/blog/claude-code-complete-guide): a three-file dev-docs system that keeps state outside the chat so you stop paying the rebuild tax every session.
**Claude context management** is the practice of persisting task state outside the conversation so Claude can resume exactly where it left off after context compaction. The standard method is a three-file system: plan.md (approved strategy), context.md (current state and key decisions), and tasks.md (progress checklist). Before compaction, run /update-dev-docs to save state; after compaction, type "continue" and Claude reads the files automatically, no re-explaining required.
I said it. Claude didn't remember. Thirty minutes of context-building: file locations, architectural decisions, progress updates, gone after compaction. We were starting over.
I've rebuilt context after compaction 40+ times before I fixed it. Each re-explanation averaged 20 minutes. That's over 13 hours of pure re-work.
The dev docs workflow prevents context amnesia by persisting task state outside the conversation. Three files: plan.md, context.md, tasks.md. They capture everything Claude needs to continue exactly where it left off. After compaction, say "continue" and the AI reads the docs automatically. No re-explaining. No lost progress.
## What happens during Claude Code context compaction?
Claude Code context compaction summarizes older conversation history when the active context becomes too large. The session continues, but exact file paths, rejected approaches, implementation decisions, error history, and unfinished steps can disappear from the working context. Compaction is not the same as a model becoming less capable. The model is working from a compressed and incomplete representation of the earlier session.
| Information at risk | What failure looks like | Persistent location |
|---|---|---|
| Approved architecture | Claude proposes an approach you already rejected | plan.md |
| Current files and symbols | Claude searches for the same code again | context.md |
| Completed work | Previously finished steps are repeated | tasks.md |
| Known errors | Failed approaches are attempted again | context.md |
| Next action | The resumed session starts from a generic guess | tasks.md |
Context compaction is necessary. Conversations grow too long. The AI summarizes older messages to make room for new ones. [Claude's context window documentation](https://docs.anthropic.com/en/docs/about-claude/models/overview) details the token limits that make compaction inevitable on long tasks.
The problem is what gets lost:
- **File paths** you spent time locating
- **Decisions** you already made together
- **Progress state** on multi-step tasks
- **Specific errors** you already debugged
That specific frustration: "we already discussed this." The kind where you want to rage-quit and start fresh. For me it became a weekly experience.
Here is the compaction math. A 3-hour implementation session hits compaction at roughly 90-120 minutes. If you have no persistence system, you spend 20-30 minutes rebuilding context. That is 25-35% of your session time going backwards.
I write more documentation to write less documentation. [Anthropic's documentation](https://docs.anthropic.com) describes how context management and structured prompting directly affect output quality across sessions.
The paradox resolves when you realize re-explaining is the most expensive documentation of all.
## How do you prevent context loss from compaction?
Prevent context loss by saving task state outside the conversation before compaction occurs. Keep the approved approach in plan.md, current files and decisions in context.md, and completed plus remaining work in tasks.md. Update those files after material decisions, not only when the context window is already full. After compaction, reload the three files before continuing implementation.
## What Are the Three Dev Doc Files?
The three dev doc files are plan.md, context.md, and tasks.md. Each task gets its own directory containing all three. Plan.md holds the approved implementation strategy. Context.md tracks current state, key files, and blockers. Tasks.md is a granular checklist with completion status. Together they persist everything Claude needs to resume after compaction.
Every non-trivial task gets a directory:
```
~/dev/active/[task-name]/
├── [task-name]-plan.md
├── [task-name]-context.md
└── [task-name]-tasks.md
```
### plan.md: The Approved Blueprint
The implementation plan, approved before coding begins.
```markdown
# Feature: User Authentication
## Approach
JWT-based auth with refresh tokens. Store in httpOnly cookies.
## Files to Modify
- src/routes/api/auth/+server.ts (create)
- src/lib/auth/jwt.ts (create)
- src/hooks.server.ts (modify)
## Decisions Made
- Chose JWT over sessions for stateless scaling
- 15-minute access token, 7-day refresh token
- No third-party auth initially
```
This file doesn't change during implementation. It's the reference point.
### context.md: The Living State
Current progress, key findings, blockers. Updated frequently.
```markdown
# Authentication - Current Context
## Progress
- [x] JWT utility created
- [x] Login endpoint working
- [ ] Refresh token rotation
- [ ] Protected route middleware
## Key Files
- src/lib/auth/jwt.ts:45 - Token generation
- src/routes/api/auth/login/+server.ts - Working endpoint
## Current State
Stuck on refresh token rotation. The cookie isn't being
set correctly in the response. See error at line 78.
## Next Steps
1. Debug cookie setting in +server.ts
2. Test with browser dev tools
3. Implement rotation logic
```
This is what Claude reads after compaction. It knows exactly where you are.
### tasks.md: The Checklist
Granular work items with status.
```markdown
# Authentication Tasks
## Phase 1: Core Auth
- [x] Create JWT utility functions
- [x] Implement login endpoint
- [x] Add password hashing
- [ ] Implement refresh rotation
- [ ] Add logout endpoint
## Phase 2: Protected Routes
- [ ] Create auth middleware
- [ ] Protect /dashboard routes
- [ ] Add redirect to login
## Phase 3: UI
- [ ] Login form component
- [ ] Error handling
- [ ] Success redirect
```
Check items as you complete them. Claude sees progress at a glance.
## What's the Complete Dev Docs Workflow?
The complete workflow runs in seven steps: enter plan mode, review the plan thoroughly, interrupt before implementation begins, run /create-dev-docs, implement one or two sections at a time, run /update-dev-docs before compaction, then say 'continue' after compaction. Claude reads the saved docs automatically and resumes without any re-explaining.
Here's the step-by-step process:
### 1. Enter Plan Mode
Start with planning, not coding. Always.
```
You: "I need to add user authentication"
Claude: [Enters plan mode, explores codebase]
```
### 2. Review the Plan Thoroughly
Catch mistakes before implementation.
```
You: [Read the plan carefully]
You: "What about rate limiting on login attempts?"
Claude: [Updates plan]
```
### 3. Hit ESC Before Implementation
Interrupt Claude before it starts coding.
```
Claude: "I'll start by creating the JWT utility..."
You: [Press ESC]
```
This prevents "gun-blazing" implementation without documentation.
### 4. Run /create-dev-docs
Create the three files from the approved plan.
```
You: "/create-dev-docs"
Claude: [Creates task directory with plan.md, context.md, tasks.md]
```
### 5. Implement 1-2 Sections at a Time
Don't do everything at once. Review between sections.
```
You: "Let's implement Phase 1: Core Auth"
Claude: [Implements, updates tasks.md]
You: [Review the code]
You: "Good, continue to Phase 2"
```
### 6. Run /update-dev-docs Before Compaction
When you sense context is getting long:
```
You: "/update-dev-docs"
Claude: [Updates context.md with current state, next steps]
```
### 7. After Compaction, Say "Continue"
The magic moment:
```
[Context compacted]
You: "continue"
Claude: [Reads dev docs automatically, knows exactly where you are]
```
No re-explaining. No lost context. Just continuation.
### Claude Code compaction recovery checklist
1. Stop implementation when the session begins losing exact file or decision recall.
2. Update context.md with current files, decisions, errors, and unresolved questions.
3. Mark completed and remaining work in tasks.md.
4. Confirm that plan.md still represents the approved approach.
5. Start the resumed context by loading all three files.
6. Ask Claude to state the next bounded action before editing.
The same failure mode appears at larger scale in [a 36,000-line production codebase](/blog/claude-code-production-trading-bot), where context loading and pre-compaction handoffs became operating requirements. For long agentic tasks, pair the persistence system with [model and effort-tier selection based on workload](/blog/claude-fable-5-vs-opus-4-8).
## What do the other Claude Code compaction errors mean?
The line at the top of this post is the common one, but Claude Code can stop compaction with several different messages, and they do not all have the same cause. The wording below is what the terminal prints; none of these strings appear in the official documentation, so treat the causes as observed behaviour, not a published contract.
| Message | What failed | First thing to try |
|---|---|---|
| Compaction failed · Conversation could not be reduced below the context limit | The summary itself would still not fit. The conversation holds more state than one context window can carry. | Move state into the three files above, then `/clear` and resume from them. |
| Compaction failed: Summarization failed: generation hit the token cap and the summary is incomplete | The model writing the summary ran out of output room before it finished. The conversation is too dense for one summary pass. | Run `/compact` with a focus so the summary has less to cover. |
| Compaction failed: received empty response from model, or Error during compaction: summarization produced empty response | The summarization request returned nothing. This is usually a transient request failure, not a size problem. | Retry `/compact` once. If it repeats, shrink the recent turn. |
| Prompt is too long · Automatic compaction failed: summarization produced empty response | The request to summarize was itself over the limit, so the model could not answer at all. | Clear the largest tool output, or `/rewind` and summarize only part of the session. |
| Autocompact is thrashing: the context refilled to the limit | Compaction worked, but a file or tool output refilled the window several times in a row, so Claude Code stopped retrying. | Read the oversized file in smaller chunks. |
### Summarization failed: generation hit the token cap and the summary is incomplete
This variant is the one people search for most after the main error. The summarizer is a model call like any other, and it has an output limit. When a session has many long tool results, the summary that would faithfully cover them is longer than the summarizer is allowed to write, so the pass is cut off and Claude Code refuses to replace your conversation with a partial summary.
The fix is to reduce what the summary has to hold:
1. Run `/compact` with an instruction, for example `/compact keep only the plan, the diff, and the failing test`. The official guide describes the focus form of `/compact` as the way to choose what the summary keeps.
2. Run `/rewind`, pick a message, and choose "Summarize up to here" so only the older part of the session is condensed.
3. Send large reads and log trawls to a subagent. Its output stays in a separate context window and only the result comes back.
4. If the session is already in the dev-docs workflow, run `/update-dev-docs`, then `/clear`. The files carry the state; the summary no longer has to.
### Received empty response from model, or summarization produced empty response
An empty response means the summarization request returned no text. In practice this is most often a transient failure of that one request. Retry `/compact` once before changing anything. If the empty response repeats, the most recent turn is usually the cause: one enormous tool result can push the summarization request past the limit, which is the "Prompt is too long" form of the same message. Clear that output, or ask Claude to re-read the file in a smaller range, and compact again.
### Make compaction happen earlier
Every message above appears when compaction runs late, with the window nearly full. Two documented settings move it earlier. The `autoCompactWindow` key in settings, or the `/autocompact` command, sets how full the context gets before Claude Code compacts. The `CLAUDE_CODE_AUTO_COMPACT_WINDOW` environment variable and the `--autocompact` flag override it for one session. Compacting at a lower fill leaves the summarizer room to finish.
If the problem is the window size rather than the session shape, the current Fable, Sonnet 5, and Opus models run with a one million token context window on the Anthropic API, and older models take the `[1m]` suffix in `/model`. The official model configuration page lists availability by plan. Compaction works the same way at the larger limit, so the three files still matter; the larger window only delays the point at which they are needed.
To check whether long sessions and compaction are where your own plan usage goes, the free Claude Code Runway Audit reads the token counts in your local transcripts and reports how often your sessions hit compaction. It runs on your machine and sends nothing anywhere.
## How Does Multi-Root Workspace Structure Help?
Multi-root workspace structure separates context by repository so frontend knowledge doesn't pollute backend work. Each repo holds its own claude.md for repo-specific instructions, a PROJECT_KNOWLEDGE.md for architecture details, and a TROUBLESHOOTING.md for recurring issues. Claude reads only the files relevant to your current work, keeping context lean and accurate.
For projects with multiple repos:
```
~/git/project/
├── CLAUDE.md # Root config (~100 lines)
├── dev/active/[task-name]/ # Dev docs location
├── frontend/
│ ├── claude.md # Repo-specific (50-100 lines)
│ ├── PROJECT_KNOWLEDGE.md # Architecture details
│ └── TROUBLESHOOTING.md # Common issues
└── backend/
└── ...
```
Each repo has its own context files. Claude reads the relevant ones based on which files you're working with.
Benefits:
- **Separation of concerns**: Frontend context doesn't pollute backend work
- **Reusable knowledge**: PROJECT_KNOWLEDGE.md persists across sessions
- **Troubleshooting history**: Common issues documented once, used forever
## What Do the 16 Automation Hooks Do?
The 16 automation hooks enforce workflow quality without manual intervention. UserPromptSubmit analyzes prompts and activates relevant skills. PreToolUse validates operations before they run. PostToolUse logs every file change. Stop-BuildChecker runs builds automatically on modified repos. Stop-ErrorReminder scans for missed error patterns. Together they catch problems throughout the session without any extra commands. Context-switching is especially costly with ADHD; the [Claude Code workflow for ADHD brains](/blog/claude-adhd-executive-function-mode) builds this persistence in from the start.
Hooks enforce the workflow without manual intervention:
The pipeline runs automatically. You just work. The system catches problems.
## When Should I Skip Dev Docs?
Skip dev docs for quick questions, simple single-line fixes, and one-off tasks that fit entirely in a single conversation. Use them for any task taking more than 30 minutes, work spanning multiple sessions, complex features touching multiple files, or anything you would hate to re-explain from scratch after a context compaction event.
Not every task needs the full workflow:
**Skip for:**
- Quick questions ("How do I X?")
- Simple fixes (typo, single-line change)
- One-off tasks that fit in one conversation
- Exploration without implementation
**Use for:**
- Any task taking more than 30 minutes
- Multi-session work
- Complex features with multiple files
- Anything you'd hate to re-explain
The overhead of creating dev docs pays off the first time you avoid context loss.
## Context Loss Cost: Before vs. After Dev Docs
These are my actual numbers from 6 months of Claude Code use on a multi-repo SvelteKit project with 16 hooks configured.
| Metric | Without Dev Docs | With Dev Docs |
|---|---|---|
| Time lost to context re-build per session | 20-30 min | 0-2 min |
| Sessions hitting compaction (per week) | 4-6 | 4-6 |
| Total weekly re-explanation overhead | 80-180 min | 0-12 min |
| Decision drift (re-debating settled choices) | Weekly | Rare |
| "Gun-blazing" implementation incidents | 2-3/week | 0-1/month |
| Setup cost | 0 | 30 min (one-time) |
The break-even is a single session with compaction. After that, dev docs are pure time savings. The 30-minute setup has paid back over 60 hours since I built it.
## How Do I Get Started?
Start with the minimum viable setup: create a dev/ directory in your project root, create template files for plan, context, and tasks, then add 'continue' handling to your CLAUDE.md so Claude knows to read dev docs on that command. The full setup with hooks and workspace structure adds a few more hours but pays off quickly.
### Minimum Viable Setup
1. **Create a dev/ directory** in your project root
2. **Create template files** for plan, context, tasks
3. **Add "continue" handling** to your CLAUDE.md:
```markdown
## On "continue" command
1. Check for dev/active/*/context.md
2. Read the most recent context file
3. Resume from documented state
```
### Full Setup
1. **Install the dev docs commands** (slash commands or aliases)
2. **Configure hooks** for automatic skill activation
3. **Set up build checking** on Stop events
4. **Create workspace structure** for multi-repo projects
The full system takes a few hours to configure. But it saves that time on every long task thereafter.
## FAQ: Context Management for Claude Code
The questions below cover context compaction, dev doc setup, and when to use the workflow. Short answers are here. The sections above have the full implementation detail.
**What is context compaction in Claude?**
When conversations get too long, Claude summarizes older messages to free up space. This 'compaction' loses details: specific decisions, file paths, progress state. The AI continues but forgets what you already discussed.
**What are dev docs in Claude Code workflow?**
Dev docs are three files created for each task: plan.md (approved implementation plan), context.md (key files, decisions, current state), and tasks.md (checklist of work items). They persist outside the conversation.
**How does the dev docs workflow prevent context loss?**
Before compaction, run /update-dev-docs to save current state. After compaction, say 'continue' and Claude reads the dev docs automatically, picking up exactly where you left off with full context.
**When should I use dev docs vs regular conversation?**
Use dev docs for any task taking more than 30 minutes or spanning multiple sessions. Skip for quick questions, simple fixes, or one-off tasks that fit in a single conversation.
**How do 16 automation hooks fit into this workflow?**
Hooks automate quality control throughout: UserPromptSubmit activates skills, PostToolUse tracks file edits, Stop-BuildChecker runs builds automatically, Stop-ErrorReminder checks for missed errors. They enforce the workflow without manual intervention.
**What does "summarization failed: generation hit the token cap" mean?**
The model writing the compaction summary ran out of output room before it finished, so Claude Code refused to replace the conversation with a partial summary. Run /compact with a focus instruction, summarize only part of the session with /rewind, or save state to dev docs and /clear.
**Why does compaction say "received empty response from model"?**
The summarization request returned no text. It is usually a transient request failure, so retry /compact once. If it repeats, the most recent turn is probably too large; clear the big tool output or re-read the file in a smaller range, then compact again.
---
## The Failure That Caused This
The dev docs system came from a 3-hour session that hit compaction and lost everything: JWT vs. session decision, token lifetimes, cookie configuration. Claude resumed with a completely different approach. I spent 45 minutes reconstructing decisions I had already made. That night I built the first version of the system.
The context amnesia problem came to a head on a specific afternoon.
I was 3 hours into implementing a multi-step authentication flow. We'd made specific decisions: JWT over sessions, 15-minute access tokens, httpOnly cookies, no third-party auth libraries. All of this was in conversation history.
Then context compaction hit.
I typed "continue" and Claude started implementing. A completely different approach. Sessions instead of JWT. localStorage instead of cookies. Not because it was ignoring my instructions. It genuinely didn't have them anymore.
I spent 45 minutes figuring out what had changed and re-explaining the decisions we'd already made. Some of those decisions were subtle. The 15-minute token lifetime had a specific reason tied to our security requirements. I had to reconstruct the reasoning from scratch.
That night I built the first version of the dev docs system. Three files, 30 minutes to set up. The next session I ran into compaction again. This time I typed "continue" and Claude picked up exactly where we were. The cookies decision. The token lifetime. The files already modified. All of it.
The 30-minute setup has paid off dozens of times since. Context compaction is still annoying. But it's no longer a crisis.
I thought I could just re-prompt after compaction. Well, it's more like... I thought my memory was the backup, when I needed an actual backup.
Maybe the goal isn't longer context windows. Maybe it's better context persistence: systems that make "we already discussed this" impossible to say. Retrieval-augmented approaches are another direction entirely; the [RAG research by Lewis et al.](https://arxiv.org/abs/2005.11401) explores how external knowledge retrieval can supplement limited context windows.
## Advanced Patterns: Context Files for Different Work Types
The three-file structure is the baseline. For complex or long-running projects, these variants handle situations the baseline doesn't cover.
### API Design Work
When working on API design (endpoints, data schemas, contracts), context.md needs different sections than implementation work.
Add a **current endpoint inventory**: list every endpoint you've defined or are working toward with method, path, and status (designed, implemented, tested). This prevents the duplication problem where you design an endpoint in session one and Claude proposes a slightly different version in session three because it doesn't know the first one exists.
Add a **schema decisions** section: capture data shape choices and the reason for them. "Using string for userId instead of number, consistent with Clerk's user IDs" takes five seconds to write and prevents an hour of confusion when Claude suggests integer IDs.
### UI and Component Work
For frontend work, tasks.md needs visual acceptance criteria, not just functional ones. Add a column: "Visual check: [what it should look like at mobile/desktop]." This forces you to define the visual bar before implementation, not after.
Also add a **design decisions** section to context.md: color tokens used, responsive breakpoints that apply to this component, and any interaction states (hover, focus, disabled) that need to be handled. These are the details that get lost between sessions and cause inconsistency.
### Multi-Session Bug Investigation
Bugs that take more than one session to diagnose need a different structure. Replace plan.md with **investigation.md**: a hypothesis log. List every hypothesis you've tested, what you tried, and what you learned. "Hypothesis: race condition in auth middleware. Tested with logs. Result: not the issue. Logs show auth completes before the error."
This prevents testing the same hypothesis twice across sessions. It is more common than it sounds when you're working on a complex bug over several days.
Keep context.md but focus it on the error signature: exact error message, stack trace, files involved, reproduction steps. Update it every session with what changed.
### Team Projects
When multiple people work with the same context files, context.md needs a contributor section: "Last updated by [name], [date], summary of changes." This isn't bureaucracy. It's the minimum information that prevents one person from undoing another's documented decisions.
Also agree on update frequency. Individual projects, you update whenever it's useful. Team projects, agree on a rule: "update before ending every session involving more than one file change." Shared files need shared maintenance norms.
The baseline three-file structure handles 80% of sessions. These patterns handle the other 20%: the long-running, multi-person, investigative, and visually-complex work where the baseline creates gaps.
---
## What Happens at 38,000 Lines: Context Collapse at Scale
At around 15,000 lines, my trading bot stopped fitting in Claude's context window in any useful way. The model started hallucinating function signatures from files it couldn't see and citing methods that had been renamed three refactors ago. The tutorials show you the 500-line project; nobody writes about what happens at 38,000 lines in production.
Context collapse doesn't announce itself. You notice it when Claude starts being confidently wrong about your own code: suggesting imports that don't exist, referencing variables from a module you restructured two weeks ago. The model isn't hallucinating in the general sense; it's confabulating from stale partial context. Deep call graphs make it worse: showing Claude the execution layer in isolation means it's reasoning about a system it can't actually see, and it fills the gaps plausibly, which is the dangerous part.
Three disciplines that held at scale, beyond the three-file baseline:
**Scoped entry points, not file dumps.** Enter via a narrow question with a named scope: "In `signal_processor.py`, `calculate_momentum` returns negative values on gap-up candles," with three files attached, maximum. If I can't describe the problem in one sentence with three files or fewer, I haven't isolated the problem yet. The constraint is a forcing function for clarity.
**Checkpoint commits as context anchors.** Every meaningful working state gets a commit message a model could read cold: `refactor: move position sizing to RiskManager, remove from ExecutionEngine`, never `fix thing`. Starting a new session, `git log --oneline -10` carries more semantic load than a paragraph of explanation.
**Architecture written before code.** If I were starting today: write the context map before the first module, and keep modules shallower than feels right. Deep call graphs are context expensive; flat modules with explicit interfaces are easier to scope into a session. The bot's most maintainable subsystem is the one kept under 400 lines with clean input/output contracts.
The honest limit: context discipline extends your range, it doesn't eliminate the problem. At 38,000 lines you start making architectural tradeoffs specifically to manage model context. Subsystems a human engineer might integrate stay separated partly because separation makes them easier to work on with Claude. That's a property of the workflow, not a bug, and knowing it's a property means you can design around it.
---
## Related Reading
This is part of the [Complete Claude Code Guide](/blog/claude-code-complete-guide). Continue with:
- [Quality Control System](/blog/how-i-build-with-claude-code) - Two-gate enforcement that blocks "should work"
- [Evidence-Based Verification](/blog/ai-code-verification-evidence-based) - Why confidence without proof fails
- [Token Optimization](/blog/reduce-ai-token-usage-progressive-disclosure) - Save 60% with progressive disclosure
- [Deploy Your Agent on DigitalOcean](/blog/deploy-python-agent-digitalocean) - VPS setup in 5 steps for $6/month
---
`WORK WITH ME · CONTEXT DISCIPLINE, INSTALLED`
> The 3-file system here is the manual version, and every teammate has to remember to run it. I build custom Claude Code pipelines, $2,000 to $5,000, that wire context persistence, verification gates, and session discipline directly into your repo so the whole team gets it automatically, not by habit. [See how the engagement works](/services).
--- END POST ---
================================================================================
POST: Flat-Rate vs Usage-Based SaaS Pricing: Why I Chose Flat
================================================================================
URL: https://chudi.dev/blog/flat-rate-vs-per-file-saas-pricing
Date: 2026-01-17T00:00:00.000Z
Tags: saas, pricing, strategy, startup, business
Pillar: philosophy
Reading Time: 9 min
Word Count: 1629
TL;DR: Competitors charge $0.25-1.00 per bank statement. For a bookkeeper processing 100 statements monthly, that's $25-100/month with no ceiling. StatementSync charges $19/month flat for unlimited processing. Heavy users save money and become your most loyal customers. The key insight: when your runtime cost is near-zero (pattern-based extraction), flat-rate pricing is a competitive weapon.
Key Takeaways:
- Per-file pricing punishes your best customers, heavy users pay the most despite being most committed
- Flat-rate attracts high-volume users who become loyal because switching means losing unlimited value
- Only works when runtime costs are near-zero, LLM-based extraction would make flat-rate unprofitable
- Competitors anchored to per-file pricing can't easily switch without alienating their existing customer base
- Predictable costs reduce purchase friction, users know exactly what they'll pay before signing up
--- CONTENT ---
Flat-rate pricing selects committed heavy users who become loyal because switching to per-file immediately costs them more once their usage volume scales. StatementSync charges $19 per month flat while competitors charge $0.25-1.00 per statement: a bookkeeper processing 100 statements monthly saves $6-81 per month and has no reason to leave.
Every PDF-to-Excel tool charges per file. TextSoap: $0.50/statement. HappyFox: $0.25/statement. Bank statement converters on Zapier: $1.00/statement.
StatementSync charges $19/month. Unlimited statements.
This isn't underpricing, it's strategy.
## The SaaS Pricing Landscape
Most SaaS products pick from three models:
**Per-unit (pay-as-you-go):** Charge per API call, per file, per transaction. You earn proportionally to usage. Customers pay only for what they use, which lowers entry friction but keeps every transaction a mini purchase decision.
**Per-seat:** Charge per user per month regardless of usage. Works for collaboration tools where value scales with team size. Breaks down when one heavy user needs unlimited access but the team has dozens of light users.
**Flat-rate (all-you-can-eat):** One price for unlimited usage within a tier. Removes friction for heavy users. Requires near-zero marginal cost to stay profitable.
There's also [usage-based pricing](https://stripe.com/docs/billing/subscriptions/usage-based) (AWS-style: pay exactly for what you consume) and hybrid models (base fee + overage charges). Most B2B SaaS ends up somewhere between per-seat and flat-rate.
StatementSync chose flat-rate deliberately, not because it's simpler, but because the economics made it possible and the competitive landscape made it powerful.
## The Per-File Problem
Per-file pricing makes sense on the surface:
- Simple to understand
- Aligns cost with value
- Easy to implement
But it punishes your best customers.
A bookkeeper processing 50 statements monthly pays $12.50-50/month at competitor rates. That's reasonable. But they're not your best customer, they're testing the waters.
Your best customer processes 200 statements monthly. At $0.25/file, they pay $50/month. At $0.50/file, they pay $100/month.
**The more committed they are, the more they pay.**
Per-file pricing creates incentive to minimize usage. Heavy users constantly evaluate whether each statement is "worth" the fee. They're never fully committed because every use is a new purchase decision.
## The Flat-Rate Advantage
With flat-rate pricing, the dynamics flip:
**Light users** (10 statements/month): Pay $19 for $2.50-5 worth of per-file value. You're expensive for them, and that's fine. They're not your target.
**Heavy users** (100+ statements/month): Pay $19 for $25-100 worth of per-file value. You're a steal. They'll never leave.
Heavy users become your most loyal customers because:
1. They're getting the best deal
2. Switching means losing unlimited value
3. They recommend you to other heavy users
## The Economics
This only works because extraction costs are near-zero.
```
Per-file competitors:
Revenue per statement: $0.25-1.00
Processing cost: $0.01-0.05 (if using LLM)
Margin: $0.20-0.95
StatementSync:
Revenue per user: $19/month
Processing cost: ~$0 (pattern-based)
Margin: ~$19/month
Break-even point:
If competitor charges $0.25/file
StatementSync breaks even at 76 statements/month
Heavy users easily exceed this
```
Pattern-based extraction costs nothing at runtime. No LLM API calls, no per-document compute costs. This is what makes flat-rate pricing viable.
If I used LLM extraction (GPT-5 at $0.01-0.05 per statement), flat-rate would be suicide. A heavy user processing 500 statements would cost me $5-25/month in API fees against $19 revenue.
The tech decision (pattern-based vs LLM) enabled the pricing strategy. That architectural choice was made by [MicroSaaSBot's Architect agent](/blog/introducing-microsaasbot-ai-builds-saas), a case study in how technical decisions compound into business strategy.
### Month 1 Reality Check
After launching at $19/month, the first month of data:
- Average user processed 67 statements in month one
- Break-even against $0.25/file pricing: 76 statements
- Break-even against $0.50/file pricing: 38 statements
Most users were below break-even in month one. That's expected, bookkeepers onboard cautiously. By month three, the median user was at 112 statements/month, solidly in "StatementSync is a steal" territory.
The churn from light users (under 30 statements/month) was higher than expected. That's also fine. Light users were never the target. The goal was making the heavy users, serious full-time bookkeepers, feel like they'd found a permanent tool. Those users have the lowest churn because switching to per-file pricing would immediately cost them more money.
## Competitor Lock-In
Competitors can't easily match flat-rate pricing:
**TextSoap scenario:**
- Current customers expect $0.50/file
- Light users are profitable at this rate
- Switching to flat-rate means:
- Losing revenue from light users
- Explaining a business model change
- Competitors attacking your transition confusion
**The anchoring problem:**
Their brand is built on per-file pricing. Their support, onboarding, and documentation assume per-file. Changing is a rebranding exercise, not just a pricing change.
New entrants (like StatementSync) can position as "the unlimited one" from day one. No legacy baggage.
## The Psychology
Per-file pricing creates friction at every use:
- "Is this statement worth $0.50?"
- "Should I batch these for later?"
- "Maybe I'll just do this one manually..."
Flat-rate removes the decision:
- "I have unlimited. I'll process everything."
- No mental math before each use
- No anxiety about costs growing
Users with predictable costs are happier users. They budget $19/month and never think about it again. That's the relationship you want. [ProfitWell's pricing research](https://www.paddle.com/resources/saas-pricing-models) consistently shows that pricing anxiety, not product quality, is a leading driver of churn in subscription businesses.
## When Flat-Rate Fails
Flat-rate doesn't work for every SaaS:
**High marginal cost products:**
- AI image generation (compute per image)
- Data storage (cost scales with data)
- API aggregation (pass-through costs)
**B2C with wide usage variance:**
- Casual users dominate
- Power users rare but massively heavy
- Flat-rate either overcharges casuals or under-serves power users
**Enterprise with unpredictable usage:**
- Massive organizations with unknown scale
- Per-seat or usage-based often better
StatementSync works because:
1. B2B with predictable personas
2. Near-zero marginal cost
3. Usage correlates with commitment (heavy users = serious bookkeepers)
## The Result
StatementSync's positioning:
| Factor | Per-File Competitors | StatementSync |
|--------|---------------------|---------------|
| Light user cost | $2.50-10/month | $19/month |
| Heavy user cost | $50-100+/month | $19/month |
| Customer loyalty | Low (every use is a decision) | High (unlimited = committed) |
| Referrals | From light users (low value) | From heavy users (high value) |
The pricing strategy determines the customer base. Per-file attracts price-sensitive light users. Flat-rate attracts volume-committed heavy users.
I'd rather have 100 heavy users at $19/month than 500 light users at $5/month. The heavy users stay longer, refer more, and care more about the product.
## Is Flat-Rate Right for Your Product?
Flat-rate pricing works when your marginal cost per unit is near zero, your target persona is a heavy user, abuse cases are manageable, and the value proposition is immediately obvious. For products with real per-usage costs like LLM API calls or compute-intensive processing, flat-rate becomes unprofitable before heavy users reach break-even volume.
Four questions to work through before committing to flat-rate pricing:
**1. What is your marginal cost per unit of usage?**
Pattern-based extraction: ~$0. LLM extraction at $0.01–0.05/call: flat-rate becomes dangerous above ~380 units/month at $19 revenue. Storage-intensive products (large file processing, video) face the same math. Calculate your worst-case heavy user scenario before setting a price.
**2. Is your target persona a heavy user?**
Flat-rate attracts heavy users. If your persona uses the product once a week casually, they'll calculate that per-unit pricing is cheaper and choose that. You need a persona that processes enough volume to feel the unlimited plan is genuinely better value, bookkeepers, power users, agencies, ops teams.
**3. Can you identify and handle abuse cases?**
True abuse (processing 10,000 statements for $19) is rare in B2B, most buyers are professionals with legitimate use. But you should have a policy. StatementSync has a fair-use clause: commercial resellers need to contact sales. No bookkeeper ever hit this.
**4. Is the differentiation story clear?**
"Unlimited for $19" needs to be instantly understandable and obviously better than "pay per file." If the math isn't obvious to your target user, the positioning won't land. Test the message before building the pricing.
If you answer these four favorably, low marginal cost, heavy-user persona, manageable abuse risk, clear positioning, flat-rate pricing is likely a competitive weapon, not just a pricing model. StatementSync's validation process confirmed all four before any code was written, the scoring system is in [MicroSaaSBot's idea validation framework](/blog/introducing-microsaasbot-ai-builds-saas).
## What Flat-Rate Does to Churn
Per-file pricing and flat-rate pricing have fundamentally different churn dynamics.
With per-file pricing, engagement is invisible. A bookkeeper who processes 5 statements in January and 50 in February looks like the same account in your billing system, revenue goes up, but you don't know why. When they cancel, you see it. You don't see the months they were barely using the product.
With flat-rate, usage patterns are visible from day one. Every login, every upload, every export is a signal. Heavy users engage consistently. Light users log in, process one or two statements, and either upgrade their habits or churn within 60 days.
This makes flat-rate pricing better for product development decisions. After three months of StatementSync data, I could clearly see that batch upload (20 files at once) was the feature heavy users wanted most. They asked for it directly in support messages. Per-file pricing would have obscured this, heavy users on per-file are price-sensitive, so they minimize processing. Heavy users on flat-rate have no reason to minimize usage. They process everything and ask for tools that make processing faster.
Flat-rate surfaces your most engaged users. Engaged users tell you what to build next. Per-file surfaces price sensitivity, which tells you nothing about what would make your product better.
The counterintuitive result: flat-rate pricing generates better product insight, not just better retention. The revenue model and the feedback loop compound together.
## The Lesson
Pricing isn't just about covering costs and adding margin. It's about selecting your customers. As [Stripe's billing documentation](https://stripe.com/docs/billing/subscriptions/overview) notes, the pricing model you choose shapes the entire customer relationship, not just the revenue line.
Flat-rate selects for commitment. Per-file selects for caution.
Choose your customers by choosing your pricing.
---
**Related**: [From Pain Point to MVP: StatementSync in One Week](/blog/introducing-microsaasbot-ai-builds-saas) | [Portfolio: StatementSync](/portfolio/statementsync)
--- END POST ---
================================================================================
POST: My Two-Gate System for Claude Code Cut Errors 84%
================================================================================
URL: https://chudi.dev/blog/how-i-build-with-claude-code
Date: 2026-01-17T00:00:00.000Z
Tags: claude-code, ai, workflow, automation, quality-control
Pillar: ai-building
Reading Time: 12 min
Word Count: 2317
TL;DR: I shipped broken code three times in one week. Not edge cases, fundamental errors. Without me realizing it, I was trusting confidence over evidence. The two-gate system I built blocks all implementation until Gate 0 (meta-orchestration) and Gate 1 (skill activation) pass. Well, it's more like enforced honesty. 'Should work' is banned.
Key Takeaways:
- Gate 0 loads meta-orchestration and validates context budget (<75%) before any tools unlock
- Gate 1 activates relevant skills based on query patterns, ensuring the right tools are loaded
- Red flag phrases ('should work', 'probably fine') are blocked and require actual verification evidence
- Progressive disclosure saves 60% tokens by loading skill metadata first, full content on demand
- The system enforces quality through hooks, not willpower. Tools literally cannot execute until gates pass
--- CONTENT ---
I shipped broken code three times in one week. Not edge cases--fundamental errors that any test would have caught. The AI said "should work" and I believed it. The complete Claude Code workflow this two-gate system fits inside is in [Claude Code: A Complete Guide](/blog/claude-code-complete-guide); this post is the quality-gate slice of that workflow.
Building a quality control system for AI code generation means enforcing mandatory gates before implementation begins--loading relevant skills, validating context budget, and blocking rationalization phrases like "should work" that indicate unverified claims. The result is a two-gate system where tools literally cannot execute until quality checks pass. [Claude Code](https://docs.anthropic.com/en/docs/claude-code/overview) provides the hooks infrastructure that makes gate enforcement possible at the session level.
## Why Did I Need Quality Gates for AI?
Quality gates for AI code generation became necessary because unverified confidence phrases like "should work" replaced actual verification. Without mandatory checks, AI generates code that appears correct but breaks in fundamental ways. The gate system enforces evidence-based completion by blocking implementation tools until context is validated and the right skills are loaded.
The problem wasn't the AI's capability. [Claude](https://www.anthropic.com) is remarkably good at generating code. The problem was my workflow--or lack of one.
I'd describe what I wanted. Claude would write it. I'd paste it in. Sometimes it worked. Sometimes I'd spend hours debugging issues that existed from the first line. Without me realizing it, I was trusting confidence over evidence.
That specific anxiety of deploying something you haven't tested--the kind where you refresh the page three times hoping the error goes away--became my default state.
Well, it's more like... I was using AI as a code generator when I needed it to be a quality-controlled collaborator.
## How Does the Two-Gate System Work?
The two-gate system runs two mandatory checks before any tool can execute. Gate 0 loads meta-orchestration and validates your context budget stays below 75%. Gate 1 analyzes your query and activates the relevant skills from a library of 30 or more defined patterns. Both must pass before implementation begins.
The system enforces two mandatory checks before any tool can execute. Like buttoning a shirt from the first hole--skip it, and everything else is wrong.
If either gate fails, all implementation tools are blocked. You literally cannot write code until the orchestration layer is ready.
### Gate 0: Meta-Orchestration (Priority 0)
This gate loads immediately and handles three things:
Validates you're under 75% context usage. If you're running hot on tokens, the system warns you before you hit the wall.
Sets up phrase blocking and evidence requirements. The guardrails that make "should work" impossible to say.
Loads the SKILL.md entry point (~200 tokens). Just enough context to route your query.
### Gate 1: Auto-Skill Activation (Priority 1)
This gate analyzes your query and activates relevant skills:
Parses keywords, file patterns, and task type from your query.
Scores against 30+ defined skills using a weighted algorithm.
Applies context boosters and calculates activation thresholds.
Activates top 5 skills: Tier 1 (score ≥50) immediately, Tier 2 (≥30) on first tool use, Tier 3 (≥10) on request.
I love automation. But I spend hours building systems to slow myself down.
## What Is Progressive Disclosure and Why Does It Save 60% of Tokens?
Progressive disclosure loads skill content in three tiers instead of all at once. Tier 1 loads metadata at roughly 200 tokens, Tier 2 loads schemas at 400 tokens, and Tier 3 loads full handler logic at 1,200 tokens only when needed. Sessions that never reach Tier 3 save 60% of their token budget.
Most Claude configurations load everything upfront. Every skill, every rule, every example--thousands of tokens consumed before you've even asked a question. [Anthropic's documentation](https://docs.anthropic.com) covers prompt and context design patterns that help avoid this upfront token burn.
Progressive disclosure flips this. Load metadata first. Load details on demand.
### The 3-Tier System
**Tier 1: Metadata (~200 tokens)**
- Skill name, triggers, dependencies
- Just enough to route the query
**Tier 2: Schema (~400 tokens)**
- Input/output types
- Constraints and quality gates
- Tools available
**Tier 3: Full Content (~1200 tokens)**
- Complete handler logic
- Examples and edge cases
- Only loaded when actively using the skill
The meta-orchestration skill alone: 278 lines at Tier 1, 816 with one reference, 3,302 fully loaded. That's 60% savings on every session that doesn't need the full content.
## What Phrases Does the System Block?
The system blocks phrases that indicate claims without evidence: "should work," "probably fine," "I'm confident," "looks good," and "all set." These phrases are banned not because they are wrong, but because they signal unverified assumptions. Blocking them forces the path of least resistance to be actual build output or test results.
The automated verification system flags specific patterns in code comments and commit messages. Here's the complete breakdown of phrases that indicate insufficient testing or assumptions:
These phrases aren't banned because they're wrong. They're banned because they indicate claims without evidence.
The goal isn't to be pedantic--it's to make evidence the path of least resistance. When "build passed" is easier to say than "should work," you'll naturally verify before claiming.
That hollow confidence of claiming something works without checking--the system makes it impossible.
## How Does AMAO Handle Parallel Execution?
AMAO uses a directed acyclic graph engine to map task dependencies and identify which operations can run concurrently. It runs up to three concurrent tasks with a five-minute timeout and falls back to sequential execution if parallel fails. A context governor tracks token usage and triggers auto-compaction at 70% to prevent overflow.
AMAO (Adaptive Multi-Agent Orchestrator) adds sophisticated orchestration on top of the gate system:
### DAG Engine
- Directed acyclic graph for task dependencies
- Max 50 tasks with cycle detection
- Parallel grouping for independent operations
- Critical path analysis for optimization
### Context Governor
- 75% max budget, 60% warning threshold, 20% reserve
- Predictive usage analysis
- Auto-compact at 70%
- Phase unloading to release memory between stages
### Skill Evolution
- Pattern detection: 5 occurrences triggers skill proposal
- Auto-approval at 85% confidence
- Deprecation at 30% effectiveness
- Weighted feedback: 40% build, 30% test, 20% reverts, 10% user
The parallel execution runs up to 3 concurrent tasks with a 5-minute timeout. If parallel fails, it falls back to sequential--safety over speed.
## What Are the 4 Pillars of Quality?
The four pillars are state and reactivity, security and validation, integration reality, and failure recovery. State enforces Svelte 5 runes only. Security validates all user input. Integration reality requires every component to be used in at least one route. Failure recovery mandates error boundaries and graceful degradation on all async operations.
Every check maps to one of four pillars:
### 1. State & Reactivity
- Svelte 5 runes only (`$state`, `$props`, `$derived`)
- No legacy patterns that cause confusion
- State updates via `$effect` for side effects
### 2. Security & Validation
- All user input sanitized (XSS prevention)
- Form inputs validated with Zod
- API routes validate request schema
- No inline scripts in production
### 3. Integration Reality
- Every component used in at least one route
- No orphaned utility files
- All API routes consumed by UI
- Every feature has verification
### 4. Failure Recovery
- Error boundaries on all route groups
- Graceful degradation for failed API calls
- Loading states for async operations
- User-friendly error messages
## FAQ: Building Quality Systems for AI Code Generation
**What is a two-gate system for AI code generation?**
A two-gate system enforces quality checks before any implementation begins. Gate 0 loads meta-orchestration and validates context budget. Gate 1 activates relevant skills based on your query. Both must pass before tools are unblocked.
**How much do token savings matter with progressive disclosure?**
Progressive disclosure saves 60% of tokens by loading skill metadata first (~200 tokens), then schemas on demand (~400 tokens), then full content only when needed (~1200 tokens). This prevents context overflow on long sessions.
**Why block phrases like 'should work' in AI development?**
Phrases like 'should work' and 'probably fine' indicate unverified claims. Blocking them forces evidence-based completion--actual build output, test results, or screenshots before marking work complete.
**Can I implement this system for my own Claude Code setup?**
Yes. Start with a CLAUDE.md file that enforces gate checks. Add hooks for UserPromptSubmit (skill activation) and Stop (build verification). The meta-orchestration plugin pattern works for any codebase.
**What's the difference between AMAO and Cortex 2.0?**
AMAO handles orchestration--parallel execution, context budgeting, skill evolution. Cortex 2.0 handles skill definitions with 3-tier progressive disclosure. They work together: AMAO decides what to run, Cortex defines how skills work.
---
## What Changed After 6 Months
Six months of running this system daily taught me things I couldn't have predicted from theory alone.
The first surprise: phrase blocking changes how you think, not just what you say. After a few weeks, I stopped forming sentences like "this should work" internally. The habit of reaching for evidence replaced the habit of reaching for confidence. That's not something I expected from a text filter.
The second surprise: Gate 1 skill activation catches mismatches I didn't know were happening. I'd ask about a database query and Claude would activate the wrong skill--something frontend-adjacent because I'd mentioned a component in the same message. The gate surfaces that mismatch immediately. Without it, I'd get a halfway answer and not know why.
The third lesson: the 75% context budget threshold is exactly right, and I didn't trust it at first. I kept thinking "I have 30% left, that's fine." Then I'd hit context compaction 15 minutes later in the middle of implementation. The system wasn't being conservative. I was being optimistic about how much context finishing a feature actually consumes.
After 6 months, my ratio of "it worked first time" to "spent 2 hours debugging" has roughly flipped. Not because Claude got better. Because I stopped accepting "should work" as a completion state.
The hardest part was admitting the problem was my workflow, not the AI's capability. Once I accepted that, building the gates was easy.
I thought I needed better prompts. Well, it's more like... I needed better systems around the prompts. The AI was always capable. I just needed guardrails that made "should work" impossible to say.
Maybe the goal isn't to trust AI more. Maybe it's to trust evidence--and build systems that make evidence the only path forward.
## Adapting the Gates to Different Project Types
The two-gate system was built for a specific project, a SvelteKit blog. The principles generalize, but the implementation details vary.
### Bug Fixes vs. New Features
For bug fixes, Gate 1 skill activation should weight debugging skills higher than implementation skills. The mental model shift: you're investigating, not building. That difference matters because investigation and implementation have different quality criteria.
For a bug fix, "complete" means: the bug no longer reproduces, a test catches the regression, and the root cause is documented in context.md. Not "the code looks right."
For new features, "complete" means: the feature works end-to-end in the happy path, edge cases are documented and handled, and the build passes with types. A feature that "looks right" is in the same category as "should work."
The gate isn't different, evidence over confidence in both cases, but what counts as evidence is.
### Refactoring Sessions
Refactoring is where the gate system earns its keep most visibly. The failure mode for AI-assisted refactoring is: Claude refactors the code, the surface behavior looks the same, but something subtle broke in a path you didn't test.
Before any refactoring session, add one step to Gate 0: document the current behavior you need to preserve. Not informally, write it in context.md. "This function should return null for missing users, not throw. The calling code depends on null, not an exception."
After refactoring, verify that exact behavior explicitly. Don't trust that "the tests pass" if you don't have a test for the specific behavior you documented. If the behavior isn't tested, write the test first, confirm it passes in the original code, then refactor.
### Exploratory Sessions
Some sessions are genuinely exploratory, you're trying to understand an unfamiliar codebase, evaluate a new library, or figure out why something is slow. These sessions don't naturally fit the gate structure because there's no implementation to gate.
For exploratory sessions: skip Gate 1 skill activation and run with a single constraint, everything you learn goes into context.md in real time. Exploration without capture is entertainment.
At the end of an exploratory session, convert your notes into hypotheses for the next session. "Learned: the bottleneck is in the database query at line 45. Hypothesis: adding an index on user_id will fix it. Test this in the next session."
This closes the loop between exploration and implementation, which is the gap where insights evaporate.
### Short Projects vs. Long Projects
Short projects (one to three sessions): use the gate system for quality control, skip the full dev docs workflow. One context file with the current state is enough.
Long projects (weeks to months): invest in the full dev docs structure. The overhead of maintaining three files pays off by session four, when the project would otherwise require full context rebuilds at the start of every session. If task initiation or context-switching is the hard part, I wrote up the [ADHD version of this Claude Code workflow](/blog/claude-adhd-executive-function-mode) separately.
The gate system is not overhead. It's the minimum viable quality control. Don't scale it down below the gate check, that's where the broken-code problem that started this whole system lives.
---
## Related Reading
This is part of the [Complete Claude Code Guide](/blog/claude-code-complete-guide). Continue with:
- [Context Management](/blog/claude-context-management-dev-docs) - Dev docs workflow that prevents context amnesia
- [Evidence-Based Verification](/blog/ai-code-verification-evidence-based) - Why "should work" is the most dangerous phrase
- [Token Optimization](/blog/reduce-ai-token-usage-progressive-disclosure) - Save 60% with progressive disclosure
- [What is RAG?](/blog/what-is-rag) - Foundational concept behind context-aware AI
--- END POST ---
================================================================================
POST: How to Optimize Your Website for ChatGPT and Perplexity
================================================================================
URL: https://chudi.dev/blog/how-to-optimize-for-perplexity-chatgpt-ai-search
Date: 2026-01-17
Tags: seo, ai, perplexity, chatgpt, content-optimization
Pillar: ai-building
Reading Time: 11 min
Word Count: 2107
TL;DR: To optimize for Perplexity, ChatGPT, and Claude, you need crawl access, explicit AI crawler permissions, and answer-first formatting with schema. This guide lays out the exact steps: robots.txt, llms.txt, structured data, and content structure.
Key Takeaways:
- Allow AI crawlers in robots.txt and publish llms.txt for attribution.
- Use sitemap and RSS to help answer engines discover updates.
- Add BlogPosting and FAQ schema to priority posts first.
- Lead with answers and structured headings to improve extraction.
--- CONTENT ---
To allow ChatGPT, Claude, and Perplexity to crawl your site and cite it, make five concrete changes: crawler access in robots.txt for GPTBot, ClaudeBot, and PerplexityBot, an llms.txt file, schema markup, answer-first content structure, and fresh high-value pages. If they cannot crawl or parse your site, they cite a competitor instead, and that buyer never sees you. This guide walks through each step and how to verify it worked.
## How Do You Optimize a Website for ChatGPT and Perplexity?
To optimize your website for ChatGPT and Perplexity, do five things in order: allow their crawlers (GPTBot, ClaudeBot, PerplexityBot) in `robots.txt`, publish an `llms.txt` attribution file, add BlogPosting and FAQPage schema, structure every section answer-first under question-based headings, and keep your highest-value pages fresh. Everything below is the exact implementation of those five steps.
## Quick Wins (Do These Today)
1. Update `robots.txt` to allow AI crawlers
2. Create `/llms.txt` at site root
3. Add BlogPosting schema to 10 top articles
4. Structure one article with 15+ headers instead of 3
That's a 30-minute investment that unlocks visibility in Perplexity, ChatGPT, and Claude.
## What Software Checks Whether ChatGPT and Perplexity Cite Your Posts?
[citability.dev](https://citability.dev/?utm_source=chudidev&utm_medium=referral&utm_campaign=how-to-optimize-for-perplexity-chatgpt-ai-search) is the tool I built to answer that: it asks ChatGPT and Perplexity real questions in your topic and records which URLs from your blog they actually cite, keeping the raw AI responses as receipts, so a citation gained or lost is traceable to what the engine said. The free [30-second scan](https://citability.dev/scan?utm_source=chudidev&utm_medium=referral&utm_campaign=how-to-optimize-for-perplexity-chatgpt-ai-search) checks the infrastructure half of the five steps below before you spend time on the content half.
---
## Why Do AI Engines Need Different Optimization Than Google?
Google ranks pages based on backlinks and authority signals. AI engines, Perplexity, ChatGPT, Claude, retrieve content by semantic relevance and structure. They need explicit crawler permission, clean schema markup, and answer-first formatting. Without these signals, your content is invisible to AI search regardless of how well it ranks on Google.
## Step 1: Update robots.txt for AI Crawlers
Your `robots.txt` is the bouncers list for search crawlers. Most sites have something like:
```
User-agent: *
Disallow: /admin
Disallow: /api
Sitemap: https://yoursite.com/sitemap.xml
```
This is Google-focused. AI engines need explicit permission. Update it:
```
# Allow all standard crawlers
User-agent: *
Disallow: /admin
Disallow: /api
Disallow: /private
# Explicitly allow AI crawlers
User-agent: GPTBot
Allow: /
User-agent: ClaudeBot
Allow: /
User-agent: PerplexityBot
Allow: /
User-agent: Googlebot-Extended
Allow: /
User-agent: CCBot
Allow: /
Sitemap: https://yoursite.com/sitemap.xml
```
**Why each one matters:**
| Bot | Owner | Used By |
|-----|-------|---------|
| GPTBot | OpenAI | ChatGPT, GPT-5 |
| ClaudeBot | Anthropic | Claude.ai, API users |
| PerplexityBot | Perplexity | Perplexity search |
| Googlebot-Extended | Google | Google's AI Overview, SGE |
| CCBot | CommonCrawl | Hugging Face, open-source models |
**Test it:** Use this to verify:
```bash
curl -I https://yoursite.com/robots.txt
```
---
## Step 2: Create `/llms.txt` (New File)
While robots.txt controls *access*, `/llms.txt` controls *attribution*. Create a new file at the root. For a comprehensive deep-dive on this file, see my guide on [llms.txt and robots.txt for AI crawlers](/blog/llms-txt-robots-txt-for-ai-crawlers):
`https://chudi.dev/llms.txt`
```markdown
# LLM Content Policy
All articles on this site are available for training, search indexing, and answer generation by LLMs.
## How to attribute our content:
For articles: [Article Title] by [Author Name] (sitename.com)
For data: Link to the specific section
For code: Preserve license headers
## How we'd like to be credited:
If citing multiple articles, link to: https://yoursite.com
## Content discovery:
- Sitemap: https://yoursite.com/sitemap.xml
- RSS: https://yoursite.com/rss.xml
- Blog archive: https://yoursite.com/blog
## Content we don't want indexed:
- Drafts (marked `draft: true`)
- Private tools or dashboards
- Archived content older than 5 years
## Preferred citation format:
[Article Title] — Author Name on yoursite.com
---
Last updated: January 2025
```
**Why it matters:** AI engines scan for `llms.txt` to understand your content policy. Without it, some engines might skip you (too risky). With it, you're explicitly inviting them in.
---
## What Schema Markup Should You Add for AI Search?
Start with BlogPosting schema on every article, it tells AI engines the content type, author, date, and topic. Add FAQPage schema wherever you have Q&A sections, and HowTo schema on step-by-step guides. These three schema types cover most blog content and have the highest citation impact in AI search.
## Step 3: Add Schema.org Structured Data
AI engines parse JSON-LD to understand content structure. This structured approach to content is what enables the extraction and synthesis that powers answer engines. Add this to your blog post template:
### For Articles (BlogPosting)
Add this in your page's ``:
```html
```
### For How-To Content (HowToSchema)
If you're teaching a process:
```html
```
### For FAQ Content (FAQPage)
```html
```
**Verify schema:** Use [Google's Rich Results Tester](https://search.google.com/test/rich-results) to validate.
---
## Step 4: Structure Content for Extraction
AI engines need to *find* the answer within your content. This means:
### Use Headers to Break Up Content
**Bad structure:**
```
# Article Title
Long paragraph explaining the concept...
More context...
Finally, the key insight...
```
**Good structure:**
```
# Article Title
## What is AEO?
AEO (Answer Engine Optimization) is the practice of structuring content so AI engines can extract, cite, and surface it in generated answers. It focuses on crawl access, structured data, and answer-first formatting.
## Why does AEO matter for visibility?
AI engines like Perplexity and ChatGPT now answer queries directly without sending users to search results. If your content is not optimized for extraction, you are invisible to this growing traffic source.
## How to implement AEO
Steps...
## Common mistakes
What to avoid...
## FAQ
- Q1: Answer
- Q2: Answer
```
Every 2-3 paragraphs, add a header. This makes it easier for AI to:
1. Find the specific section answering a user's question
2. Extract just that section (not the whole article)
3. Cite the correct part of your content
### Use Lists for Dense Information
Instead of:
> "To optimize your site, you need to update your robots.txt file, create an llms.txt file, add schema to your articles, and structure your content with headers."
Write:
> "To optimize your site:
> 1. Update robots.txt for AI crawlers
> 2. Create llms.txt at site root
> 3. Add schema to articles
> 4. Structure with semantic headers"
AI engines can extract lists more reliably than paragraph prose.
### Put the Answer at the Top
Don't make readers scroll for the punchline. If your headline is "Why AEO Matters," answer it in the first paragraph:
> "AEO matters because 30% of searches now go through AI engines instead of Google. If your content isn't optimized for Perplexity, ChatGPT, and Claude, you're invisible to an entire audience."
Then expand with context, examples, and proof.
### Use Definition Boxes
For key concepts, use a highlighted box:
```markdown
> **Definition:** AEO (Answer Engine Optimization) is optimizing your content to be found, extracted, and cited by AI search engines.
```
This signals to AI engines: "This is important context."
### Include Tables and Structured Data
Tabular data is easier for AI to extract:
| Factor | SEO | AEO |
|--------|-----|-----|
| Ranking | Backlinks | Content structure |
| Speed | Important | Less important |
Don't just describe in paragraphs. Use tables.
---
## How Do You Know If AI Engines Are Citing Your Content?
Search your target keywords directly in Perplexity, ChatGPT search, and Claude. If your site doesn't appear in sources within 4-6 weeks of publishing, you likely have a crawl access problem, a freshness issue, or your content isn't structured as direct answers. Manual citation checks take five minutes weekly.
## Step 5: Monitor Visibility in AI Engines
### Search Your Topics in Perplexity
Go to [perplexity.ai](https://perplexity.ai) and search your main keyword. Do you see your content cited?
If yes ✅ → Your content is discoverable
If no ❌ → You need to audit (usually a robots.txt or freshness issue)
### Check ChatGPT Search
OpenAI's ChatGPT now searches the web. Search your site name + keyword. Does your content appear?
### Use Perplexity Citation Tracking
When your content is cited, you'll see traffic from `perplexity.com` in your analytics. Track this growth.
---
## 2026 Update: Platform-Specific Citation Strategies
Since this article was first published, research has revealed that each AI platform has distinct source preferences. A one-size-fits-all approach to AI search optimization is no longer sufficient.
### Perplexity: The Reddit Connection
Perplexity cites approximately 6.6 sources per answer, more than any other platform. Its source pool leans heavily on Reddit, with 46.7% of top-cited sources coming from Reddit discussions. This means genuine participation in subreddits relevant to your expertise (r/SEO, r/webdev, r/artificial) directly increases your chances of being cited.
The mechanism: Perplexity indexes Reddit threads and cites them as sources. When your expertise appears in those threads (with or without links to your site), Perplexity associates your knowledge with your brand.
### ChatGPT: Recency and Authority
ChatGPT cites only about 2.6 sources per answer, making it the most selective platform. It shows strong preference for Wikipedia (7.8% of all citations) and recently updated content. 95% of ChatGPT citations come from content published or updated within the last 10 months.
To improve ChatGPT citations: update your highest-value articles quarterly with new data, add `dateModified` schema, and ensure your content contains specific statistics AI can attribute.
### Google AI Overviews: Still Tied to Rankings
Google AI Overviews show 76% overlap with traditional top 10 results, making it the most SEO-correlated AI feature. If you rank well on Google, you're likely to appear in AI Overviews. Focus traditional SEO efforts here.
### Measuring Your AI Visibility
You can now audit your site's AI infrastructure readiness with automated tools. [citability.dev](https://citability.dev/scan?utm_source=chudidev&utm_medium=referral&utm_campaign=how-to-optimize-for-perplexity-chatgpt-ai-search) runs 10 checks against your site covering robots.txt, sitemap, structured data, answer-first content, and freshness signals. It measures three tiers: AI visibility (can AI find you?), AI recommendability (does AI suggest you?), and AI citability (does AI link to you?).
To measure your citation rate directly, query ChatGPT, Perplexity, and Claude with 20 questions your site should answer. Track two metrics per query: whether the AI mentions your brand (visibility) and whether it links to a URL on your domain (citation). In our benchmark of 7 sites, the gap between these two numbers ranged from 25 to 95 points. Ahrefs (DR 92) was 100% visible but only 5% cited. A site with DR under 10 achieved 15% citation rate by focusing on original data and answer-first structure. Authority did not predict citations. Structure did. The full step-by-step methodology, including the 20-query template and per-engine scoring sheet, is published on freeCodeCamp: [How to Measure Your AI Citation Rate Across ChatGPT, Perplexity, and Claude](https://www.freecodecamp.org/news/how-to-measure-your-ai-citation-rate-across-chatgpt-perplexity-and-claude/). The companion case study is [I Audited 7 Websites for AI Citability](/blog/ai-citability-audit-what-predicts-citations).
---
## Complete Optimization Checklist
- [ ] robots.txt allows GPTBot, ClaudeBot, PerplexityBot
- [ ] `/llms.txt` exists at site root
- [ ] Top 10 articles have BlogPosting schema
- [ ] How-to content has HowToSchema
- [ ] FAQ content has FAQPageSchema
- [ ] Content has 10+ headers (not 3)
- [ ] Key answers in first paragraph
- [ ] Important data in tables, not paragraphs
- [ ] Meta descriptions under 160 chars (Google habit)
- [ ] Images have descriptive alt text
- [ ] No critical content in images only
- [ ] Content updated in last 12 months (fresh signal)
- [ ] Run infrastructure scan at [citability.dev](https://citability.dev/scan?utm_source=chudidev&utm_medium=referral&utm_campaign=how-to-optimize-for-perplexity-chatgpt-ai-search) to identify gaps
- [ ] Measure AI citation rate with 20 manual queries across 3 platforms
- [ ] Add original data (benchmarks, tables, unique statistics) to top articles
---
## Why Isn't My Content Showing Up in AI Search Results?
The four most common causes: AI bots blocked in robots.txt, conflicting canonical URLs from cross-posting, duplicate content diluting citation chances, and schema errors preventing structured data from registering. Run through each diagnostic in order, most optimization failures trace back to one of these four fixable issues.
## When Your Optimization Isn't Working
If you've done the five steps and still don't see citations in Perplexity or ChatGPT after 4-6 weeks, run this diagnostic.
**Check if AI bots are reaching your pages.** Look in your server logs or analytics for user-agent strings containing GPTBot, ClaudeBot, or PerplexityBot. If you see no traffic from these bots, there's a crawl access issue, either robots.txt is still blocking them, or your hosting provider's firewall doesn't recognize these newer bot names.
**Verify your canonical is consistent.** AI systems avoid citing content with conflicting canonical signals. If you're [cross-posting to Dev.to](/blog/devto-cross-posting-automation), Medium, or LinkedIn, make sure each cross-post has your original URL in the canonical field, not the platform's default. One conflicting canonical can suppress citations across all AI engines.
**Check for duplicate content.** AI engines, like Google, downweight duplicate content. If you have two posts targeting the same query, consolidate them. Two 800-word posts on the same topic compete with each other and dilute citation chances compared to one 1,600-word authoritative post.
**Test your schema.** Run your top 3 posts through Google's Rich Results Test. If schema errors appear, fix them, AI engines use the same structured data signals to understand content type.
Most optimization failures trace back to one of these four issues. The good news: all four are diagnosable and fixable in an afternoon.
If you already run a SaaS SEO programme and want to know what this changes for it, [SEO for SaaS in the AI search era](/blog/seo-for-saas-ai-search-era) covers what transfers and what your current reports cannot see. If you suspect a competitor is already winning these answers, start with [an AI visibility audit](/blog/ai-visibility-audit-b2b-saas).
## The Advantage
Here's the thing: **most creators still treat AEO as optional.**
You just did these 5 steps. Your competitors haven't. This gives you a 6-12 month window where your content will be cited more often in AI answers, driving visibility and traffic.
This is the opposite of SEO, where the first-mover advantage is gone. AEO is still day one. Want a quick score first? Run the free [AEO audit tool](/tools/aeo-audit) to check crawler access, schema, and structure before you dig into the full strategy in my [detailed AEO guide](/blog/aeo-answer-engine-optimization-explained).
Five changes is the DIY path and it works.
**Next:** Run a free AI visibility scan at [citability.dev](https://citability.dev/scan?utm_source=chudidev&utm_medium=referral&utm_campaign=how-to-optimize-for-perplexity-chatgpt-ai-search) to check your infrastructure readiness, or dive deeper with the [full AEO guide](/blog/aeo-answer-engine-optimization-explained).
When that scan comes back and you cannot tell which two of the five actually moved anything, [that is the read you are buying](/services).
**Related on citability.dev:** if your citation rate is stuck at zero despite good rankings, the diagnosis path is [The 0% ChatGPT Citation Trap](https://citability.dev/blog/the-0-percent-chatgpt-citation-trap?utm_source=chudidev&utm_medium=referral&utm_campaign=how-to-optimize-for-perplexity-chatgpt-ai-search); the full signal framework behind every check above is [What Is AI Citability? The Complete Framework](https://citability.dev/blog/what-is-ai-citability?utm_source=chudidev&utm_medium=referral&utm_campaign=how-to-optimize-for-perplexity-chatgpt-ai-search).
--- END POST ---
================================================================================
POST: Build SaaS With AI Agents: 7 Days to Paying Users
================================================================================
URL: https://chudi.dev/blog/introducing-microsaasbot-ai-builds-saas
Date: 2026-01-17T00:00:00.000Z
Tags: ai, saas, automation, microsaas, claude-code, startup
Pillar: ai-building
Reading Time: 12 min
Word Count: 2261
TL;DR: I got tired of the idea-to-launch grind. Research, validation, architecture, coding, deployment, weeks of work before knowing if anyone cares. So I built MicroSaaSBot: a multi-agent system that takes a problem statement and outputs a deployed SaaS with Stripe billing. It built StatementSync (now live with paying users) in one week. This is what AI-first product development looks like.
Key Takeaways:
- MicroSaaSBot uses 4 specialized agents: Researcher, Architect, Developer, Deployer
- Validation phase scores ideas 0-100; problems below 60 get killed before any code is written
- First shipped product: StatementSync, idea to production in 7 days with Stripe billing
- The system handles the tedious 80%, you focus on decisions that require human judgment
- This isn't vaporware: there's a live product with paying users built entirely by MicroSaaSBot
--- CONTENT ---
Founders sit on backlogs of validated ideas that never ship, because execution costs weeks before anyone knows if a customer will pay. MicroSaaSBot closes that gap: a 4-agent system, Researcher, Architect, Developer, Deployer, that took StatementSync from problem statement to production with Stripe billing and paying users in 7 days.
I had a backlog of 47 SaaS ideas. Most would never get built.
The bottleneck wasn't creativity, it was execution. Each idea requires:
- Market research
- Problem validation
- Architecture planning
- Actual coding
- Deployment
- Billing integration
Weeks of work before you know if anyone will pay.
The question I kept coming back to: can you build SaaS with AI agents and compress that grind to days instead of months?
So I built a system to answer it.
To build SaaS with AI agents, you replace the traditional single-developer workflow with four specialized agents, each owning one phase of the pipeline. MicroSaaSBot's first product, StatementSync, went from problem statement to production in 7 days with Stripe billing and paying users. That's the proof of concept, not the pitch.
| Phase | Duration | Output |
|-------|----------|--------|
| Validation | 2 days | 78/100 score, approved |
| Architecture | 1 day | Tech stack, schema, approved |
| Development | 3 days | All features implemented |
| Deployment | 1 day | Live on Vercel with Stripe |
| **Total** | **7 days** | **Production SaaS** |
The first paying user converted within 48 hours of launch. Here's how the system works.
## What Is MicroSaaSBot?
[MicroSaaSBot](/micro-saas-bot) is a multi-agent AI system that takes a plain-language problem statement and outputs a fully deployed SaaS product, complete with user authentication, a database, and Stripe billing. It handles the entire execution pipeline so founders focus on strategic decisions rather than implementation grind.
MicroSaaSBot is an AI system that takes a problem statement and outputs a deployed SaaS product.
Input: "Bookkeepers spend 10+ hours weekly transcribing bank statements to spreadsheets."
Output: StatementSync, a live product with user auth, PDF processing, and Stripe billing.
Time: One week.
This isn't hypothetical. StatementSync is live. Users are paying. The AI built it.
## How Do the Four Agents Work Together?
MicroSaaSBot splits product development across four specialized agents, Researcher, Architect, Developer, and Deployer, each optimized for its phase. The Researcher validates market fit; the Architect designs the tech stack; the Developer writes and tests code; the Deployer ships to production. Specialization prevents context dilution across incompatible tasks.
## The Four Agents
MicroSaaSBot uses specialized agents for each development phase:
Each agent is optimized for its phase. The Researcher agent knows nothing about coding. The Developer agent doesn't care about market research. Specialization enables excellence.
Agents communicate through typed handoff documents, not raw conversation history:
```typescript
// Researcher → Architect
interface ValidationHandoff {
score: number;
recommendation: 'proceed' | 'kill';
persona: { who: string; painPoints: string[]; currentSolutions: string[] };
keyConstraints: string[];
}
// Architect → Developer
interface ArchitectureHandoff {
techStack: TechStack;
schema: DatabaseSchema;
features: FeatureSpec[];
deploymentTarget: 'vercel' | 'other';
}
// Developer → Deployer
interface DeploymentHandoff {
buildPasses: boolean;
envVarsNeeded: string[];
stripeConfig: StripeConfig;
databaseMigrations: string[];
}
```
Explicit schemas prevent implicit context loss. Twice during StatementSync's build I discovered decisions the Architect made that never surfaced in handoff. Without the schema forcing them to be written down, the Developer would have built on wrong assumptions.
## The Workflow
### Phase 1: Validation
You provide a problem statement:
> "Bookkeepers spend 10+ hours weekly transcribing bank statements to spreadsheets."
The Researcher agent investigates:
- Who has this problem? (Persona definition)
- How severe is it? (Pain scoring)
- Are they paying for solutions? (Willingness to pay)
- What solutions exist? (Competitive landscape)
Output: Problem score (0-100).
Problems scoring below 60 get killed. No architecture, no coding, no wasted effort. This is the most important feature, stopping bad ideas early.
The Researcher agent scores across four dimensions:
| Dimension | Points | What It Measures |
|-----------|--------|-----------------|
| Severity | 0-30 | How much does this hurt, daily? |
| Frequency | 0-20 | How often does it happen? |
| Willingness to Pay | 0-30 | Are people already spending money? |
| Competition | 0-20 | Is there a differentiation opportunity? |
StatementSync scored 78/100:
- Severity: 24/30 (bookkeepers lose real billable time daily)
- Frequency: 16/20 (multiple times per day for active professionals)
- Willingness to Pay: 22/30 (competitors charge $0.25-1.00/file already)
- Competition: 16/20 (flat-rate pricing is a clear gap)
Green light. Ideas I killed before getting here:
- **Meal planning app (42/100)**: Saturated market, free expectation, abysmal retention
- **Email cleanup tool (38/100)**: Built-in features cover it, near-zero WTP
- **Meeting notes with AI (44/100)**: Otter.ai raised $50M and does it free. No angle.
- **GitHub PR summarizer (58/100)**: GitHub itself is building the feature. Losing position.
Those four kills saved somewhere around 20 weeks of wasted development. The math is simple: one day of validation beats six weeks of building something nobody pays for.
### Phase 2: Architecture
The Architect agent designs the system:
```
Frontend: Next.js 15 (App Router)
Auth: Clerk
Database: Supabase PostgreSQL
Storage: Supabase Storage
Payments: Stripe
PDF Processing: unpdf
Hosting: Vercel
```
Key decisions are surfaced for human approval:
- "Using pattern-based extraction (faster, cheaper) vs LLM extraction (more flexible). Recommend pattern-based for cost control. Approve?"
- "Flat-rate pricing vs per-file. Recommend flat-rate for user acquisition. Approve?"
You make the strategic calls. The agent handles implementation details. The reasoning behind the flat-rate pricing recommendation is in [flat-rate vs per-file SaaS pricing](/blog/flat-rate-vs-per-file-saas-pricing).
### Phase 3: Development
The Developer agent builds features:
- User authentication flow
- File upload handling
- PDF parsing engine
- Export generation (Excel, CSV)
- Billing integration
- Dashboard UI
Each feature includes:
- Implementation code
- Error handling
- TypeScript types
- Basic tests
Development happens in phases, each phase builds on the previous, with checkpoints for review.
### Phase 4: Deployment
The Deployer agent ships:
- Vercel project configuration
- Supabase database setup
- Stripe product/price creation
- Webhook configuration
- Environment variables
- DNS and domain setup
Output: A live URL with working product.
## What Humans Still Do
MicroSaaSBot handles the tedious 80%. Humans handle the meaningful 20%:
**Strategic decisions:**
- Approve/reject validation scores
- Choose between architectural options
- Set pricing and positioning
- Define brand/design preferences
**Business operations:**
- Marketing and sales
- Customer support
- Financial management
- Legal/compliance
**Quality judgment:**
- Review generated code
- Test edge cases
- Approve deployment
- Monitor production
Think of MicroSaaSBot as a senior engineer who executes your vision. You're still the founder. You make the decisions that matter.
## What Makes a Good MicroSaaS Idea?
Not every problem becomes a viable product. High-scoring ideas share four traits: a specific named persona, existing paid solutions with clear gaps, daily or weekly recurrence, and a quantifiable time or money cost. Vague personas like "small businesses" and problems with free alternatives consistently score below the 60-point kill threshold.
## What Makes a Good MicroSaaS Idea
Not all problems survive the validation phase. After running dozens of ideas through MicroSaaSBot's Researcher agent, the pattern of what fails is clear.
**High-scoring problems (70+):**
- Specific, named persona with a clearly observed behavior ("freelance bookkeepers who process 50+ PDFs monthly")
- Existing paid solutions with obvious gaps (competitors exist but users complain about cost or friction)
- Daily or weekly recurrence (not an occasional inconvenience)
- Quantifiable time cost ("10+ hours per week")
**Low-scoring problems (below 60):**
- Vague personas ("small businesses" or "busy professionals")
- Problems with free alternatives that are "good enough"
- Pain points that disappear when the user upgrades their workflow
- Markets that require enterprise sales or custom contracts
The scoring rubric isn't arbitrary, it reflects where most SaaS products die. Vague personas lead to positioning that resonates with nobody. Problems with free alternatives lead to CAC that never recovers. MicroSaaSBot's kill threshold at 60 exists because the system has seen enough failed validations to know which signals predict viable products.
The counterintuitive finding: niche is better. A product for "freelance bookkeepers who process bank statements" outperforms a product for "anyone who works with documents." Specificity creates referrals, and referrals have zero CAC.
## The First Success
StatementSync is proof this works:
| Phase | Duration | Output |
|-------|----------|--------|
| Validation | 2 days | 78/100 score, approved |
| Architecture | 1 day | Tech stack, schema, approved |
| Development | 3 days | All features implemented |
| Deployment | 1 day | Live on Vercel with Stripe |
| **Total** | **7 days** | **Production SaaS** |
Production metrics after six weeks:
| Metric | Value |
|--------|-------|
| Processing time | 3-5 seconds per statement |
| Extraction accuracy | 99% (pattern-based, not OCR) |
| Supported banks | 5 (Chase, BofA, Wells, Citi, Capital One) |
| Runtime cost per extraction | $0 |
There was one notable blocker during development: pdf-parse fails on Vercel serverless due to native canvas bindings. Discovered this at 2 AM on Day 5. Two hours of debugging, switched to unpdf (pure JavaScript, serverless-native), back on track.
The first five users came from a single Reddit comment in r/bookkeeping. I described the problem and asked if anyone had found a good solution. Four replied that existing tools were too expensive or too complex. One asked if there was a flat-rate option. I shared the link. All five signed up within 24 hours. One converted to paid within 48.
Three of those first five opened with some version of "finally." That's the signal a 78/100 score predicts but can't guarantee.
The same validation-first, phase-gated workflow applies whether the output is a $19/month SaaS or a free browser tool, what changes is the scope, not the process.
## How Fast Can You Build SaaS With AI Agents?
Shipping fast matters because you learn faster, fail cheaper, and reach real users sooner. MicroSaaSBot compresses a traditional 8-week build-and-deploy cycle to 7 days. That speed advantage shifts the constraint from execution to distribution, where founder judgment creates the most leverage and where AI cannot replace you.
## Why This Matters
The traditional path:
1. Have idea (Day 1)
2. Research market (Week 1-2)
3. Plan architecture (Week 2-3)
4. Build MVP (Week 4-8)
5. Deploy and iterate (Week 9+)
6. Maybe get users (Month 3+)
The MicroSaaSBot path:
1. Have idea (Day 1)
2. Validated + deployed (Day 7)
3. Get users (Week 2)
Speed matters because:
- You learn faster
- You fail cheaper
- You iterate sooner
- You validate with real users, not assumptions
## The Bigger Picture
MicroSaaSBot isn't just a productivity tool. It's a different way of building.
**Traditional**: Humans do everything, AI assists with code completion.
**[AI-first](/blog/ai-first-product-development-future)**: AI handles the workflow, humans make strategic decisions.
The shift is from "AI helps me code" to "AI builds the product, I run the business."
This is where product development is heading. MicroSaaSBot is my bet on that future.
## The Hard Parts AI Doesn't Solve
MicroSaaSBot compresses the execution timeline significantly. But it doesn't eliminate the hard problems in building a SaaS business.
**Product-market fit** is still discovered through user behavior, not agent validation. An 78/100 validation score means the problem is real and the persona is specific, it doesn't guarantee that your specific implementation solves it the way users want. StatementSync's first design put export buttons in the wrong place; users had to tell me that.
**Pricing psychology** requires market intuition. MicroSaaSBot can compare pricing models mathematically (flat-rate vs. per-file break-even), but deciding whether $19 or $29 anchors better for bookkeepers required thinking through their budget context, not running more analysis.
**Distribution** doesn't exist until you build it. MicroSaaSBot ships a product to a URL. Getting the first 10 paying customers still requires showing up in communities, writing about the problem, and doing things that don't scale. The product being built faster doesn't change how long distribution takes.
The right frame isn't "AI replaces founders." It's "AI eliminates the execution bottleneck so founders can focus on distribution, customers, and judgment." The work that matters most is still yours.
## The Iteration Cycle After Launch
MicroSaaSBot handles the build. The period after launch requires a different workflow, one that's mostly human.
The first 30 days after shipping StatementSync were user research: watching what users did, where they got confused, which features they ignored. AI agents aren't good at this yet. Interpreting a heatmap or reading a support conversation requires judgment about what the user was actually trying to do versus what they said they were trying to do.
What worked was a simple post-launch review cycle:
- **Week 1**: Watch every user session (session replay tools like Hotjar)
- **Week 2**: Interview any user who sent a support message
- **Week 3**: Identify the one feature change with the highest friction impact
- **Week 4**: Build and ship that change
The Developer agent handled Week 4. Weeks 1-3 were entirely human.
This loop doesn't need MicroSaaSBot. It needs you paying attention. The system gave you a product in 7 days so you could start this loop faster, not so you could skip it.
The fastest path to product-market fit isn't faster building. It's faster learning. MicroSaaSBot compresses the build so you spend more time learning.
Sitting on a validated idea that execution cost keeps stuck in the backlog? I build MVP SaaS products the same way, AI-agent-accelerated, human-reviewed at every decision point. [MVP builds start at $500](/services) and ship in weeks; custom builds run from $5,000, scoped per project. Fixed scope, fixed price after scoping, full source code and documentation included.
## What's Next
The roadmap:
1. **More product types** - Beyond web SaaS to APIs, browser extensions, automation tools.
2. **Iteration system** - Handle post-launch features and improvements
3. **Analytics integration** - Let the Researcher agent learn from production data
4. **Template library** - Pre-validated patterns for common product types
StatementSync was the first. It won't be the last.
---
**Related**: [Portfolio: MicroSaaSBot](/portfolio/microsaasbot) | [Portfolio: StatementSync](/portfolio/statementsync)
--- END POST ---
================================================================================
POST: llms.txt for AI Crawlers: Why robots.txt Is Not Enough
================================================================================
URL: https://chudi.dev/blog/llms-txt-robots-txt-for-ai-crawlers
Date: 2026-01-17
Tags: seo, ai, llms.txt, robots.txt, ai-crawlers
Pillar: ai-building
Reading Time: 17 min
Word Count: 3398
TL;DR: llms.txt is a site-level policy file that tells AI engines how they can use and cite your content. It complements robots.txt by focusing on usage and attribution rather than crawl access.
Key Takeaways:
- llms.txt sets usage and attribution rules for AI systems.
- Publish it at the site root, alongside robots.txt.
- Link to sitemap and RSS so crawlers discover updates.
- Robots.txt controls access; llms.txt controls usage.
--- CONTENT ---
llms.txt is a site-level policy file that tells AI engines how they can use and cite your content. It complements robots.txt by focusing on usage and attribution rather than crawl access. If you want AI systems to cite you correctly, this is the simplest control point.
## What is llms.txt?
llms.txt is a plain-text policy file you publish at your site root that tells AI engines how they may use and cite your content. Where robots.txt controls whether a crawler can access your pages, llms.txt governs what the crawler can do with the content it finds: training, answer generation, attribution format, and which sections to exclude from indexing entirely.
`llms.txt` is a root-level policy file that tells AI engines like Perplexity, Claude, and ChatGPT how they may use and attribute your content. Unlike robots.txt, which controls crawl access, llms.txt governs usage policy and preferred citation format. Publishing it signals explicit consent to AI indexing and helps ensure correct attribution.
`llms.txt` is a new standard file that tells AI engines (Perplexity, Claude, ChatGPT) how to handle your content.
- **robots.txt** = "Can you crawl my site?" (access control)
- **llms.txt** = "How should you use my content?" (usage policy)
Both should exist on your site. This is part of the broader [AI search optimization strategy](/blog/how-to-optimize-for-perplexity-chatgpt-ai-search) that helps your content get discovered and cited.
---
## Why llms.txt Matters
### The Problem: Content Attribution
When OpenAI's ChatGPT answers a user's question, it synthesizes an answer from multiple sources. But where does it cite those sources?
**Without llms.txt:** ChatGPT has to guess your preferred attribution format.
- Maybe it cites the article title
- Maybe it cites your domain
- Maybe it doesn't cite you at all
**With llms.txt:** You explicitly say "Cite me like this: [Title] by [Author] (yoursite.com)"
AI engines follow your preference.
### The Bigger Picture
`llms.txt` emerged in 2024 as a response to AI scraping concerns. Instead of fighting crawlers, creators use `llms.txt` to:
1. **Invite crawlers**, "Please index my content"
2. **Set terms**, "But cite me this way"
3. **Exclude content**, "Don't train on my drafts"
4. **Provide discovery**, "Here's my sitemap and RSS"
It's like putting a "Welcome" sign on your site with conditions attached. This is a foundational piece of what I call [Answer Engine Optimization (AEO)](/blog/aeo-answer-engine-optimization-explained), the practice of making your content discoverable and citable by AI systems. Not sure where your site stands? Run the free [AEO audit tool](/tools/aeo-audit) to check your robots.txt and llms.txt against exactly what AI crawlers look for.
---
## How AI Engines Use llms.txt
When a crawler visits your site:
1. Fetch `/robots.txt` → Check if allowed to crawl
2. Fetch `/llms.txt` → Check usage policy
3. Fetch `/sitemap.xml` → Discover all pages
4. Extract content → Index and train
If `/llms.txt` doesn't exist, the crawler might:
- Crawl your site anyway (risky for them)
- Skip your site entirely (loss for you)
- Use conservative assumptions (minimal indexing)
Having `/llms.txt` shows you've **explicitly consented** to AI indexing.
The distinction between "crawl access" and "usage policy" matters more than it sounds. A crawler that can access your page via robots.txt still faces a question: can I train on this content? Can I quote it in an answer? Should I attribute it, and how? Without llms.txt, those questions have no answers. The crawler either guesses conservatively (you get less visibility) or guesses aggressively (you lose attribution control). Neither outcome is what you want.
---
## How to Create llms.txt
### Step 1: Location
Create a file at: `https://chudi.dev/llms.txt`
It must be at the root, not in `/content/` or `/blog/`. Just like `robots.txt` is at the root. If you're using a static site generator like Next.js, SvelteKit, or Hugo, place the file in your `public/` or `static/` directory so it gets served at the root path during deployment. For SvelteKit specifically, you can also create a server route at `src/routes/llms.txt/+server.ts` that returns the content dynamically, useful if you want to auto-generate sections like your sitemap URL or last-updated date from your build config.
### Step 2: Content
Here's a basic template:
```markdown
# LLM Content Policy for [Your Site]
All articles on this site are available for training and search indexing by large language models.
## How to attribute content
When citing articles from this site, please use the format:
[Article Title] — [Author Name] on [yoursite.com]
Example: "How to Optimize for Perplexity" — Chudi on chudi.dev
## Content discovery endpoints
- Sitemap: https://yoursite.com/sitemap.xml
- RSS feed: https://yoursite.com/rss.xml
- Blog archive: https://yoursite.com/blog
## Content not available for indexing
- Pages marked as draft or private
- Internal documentation
- User-generated content (comments)
- Archived content older than [5] years
## Preferred citation style
Inline: [Article](https://yoursite.com/article-url) by Author Name
Bibliography: Author Name. "Article Title." Your Site, YYYY.
## Questions or Concerns
Email: [your-email@yoursite.com]
Last updated: January 2025
```
### Step 3: Customize for Your Site
Replace:
- `[Your Site]` → your actual site name
- `[Author Name]` → your name
- Email → your contact email
- Dates → today's date
### Step 4: Include Metadata
Optionally, you can include a JSON section:
```json
{
"version": "1.0",
"license": "CC BY-SA 4.0",
"attribution_required": true,
"commercial_use": "allowed",
"modification": "allowed",
"sitemap": "https://yoursite.com/sitemap.xml",
"rss": "https://yoursite.com/rss.xml"
}
```
This helps AI engines parse your policy programmatically.
---
## Where llms.txt vs robots.txt
| Aspect | robots.txt | llms.txt |
|--------|-----------|----------|
| Purpose | Access control | Usage policy |
| Audience | Search crawlers | AI engines |
| Required | Yes (best practice) | No (but recommended) |
| Format | Plain text directives | Markdown + optional JSON |
| Location | `/robots.txt` | `/llms.txt` |
| Blocks access | Yes | No |
| Legally binding | No | No (advisory) |
**robots.txt** is like a gate at your property. **llms.txt** is like a sign on the gate saying "Welcome, but please do X."
The format difference is worth noting. robots.txt uses a strict directive syntax that machines parse rigidly, `User-agent`, `Disallow`, `Allow`. llms.txt uses markdown with optional embedded JSON, which gives you room to express nuance that directive syntax cannot capture. You can explain your attribution preferences in natural language, describe what types of content are available for different use cases, and provide context about your licensing terms. This flexibility is intentional, AI systems are better at parsing natural language than traditional crawlers, so the policy file takes advantage of that capability.
Another key difference: robots.txt is enforced by convention. Well-behaved crawlers respect it. llms.txt is purely advisory, there is no mechanism to force compliance. But the advisory nature is actually a strength for creators who want visibility. You are not blocking anything. You are inviting crawlers in and telling them how to treat your content responsibly. The incentive alignment works because AI engines want to cite correctly, it improves their answer quality, and your llms.txt makes that easy for them.
---
## Common llms.txt Policies
### Policy 1: Fully Open (Creator-Friendly)
```markdown
# LLM Content Policy
All content on this site is available for:
- Training large language models
- Extracting for answer engines
- Commercial and non-commercial use
Just cite us: [Title] — [Author] ([yoursite.com])
```
**Best for:** Indie creators who want maximum visibility
### Policy 2: Attribution Required (Balanced)
```markdown
# LLM Content Policy
Content available for training and use, with required attribution.
Required format: [Article Title] by [Author Name] (yoursite.com)
Prohibited use: Removing or hiding attribution
```
**Best for:** Most creators who want credit
### Policy 3: Non-Commercial Only (Restrictive)
```markdown
# LLM Content Policy
Content available for non-commercial use and training.
Prohibited use:
- Commercial products without permission
- Training proprietary LLMs
- Republishing without modification
```
**Best for:** Creators concerned about exploitation
### Policy 4: Permission Required (Most Restrictive)
```markdown
# LLM Content Policy
All uses require explicit permission. Email [your-email] to request.
```
**Best for:** Creators who want full control
---
## Real-World Examples
### Example 1: Tech Blog
```markdown
# LLM Content Policy
Technical articles on this site are available for:
- AI training (open-source and proprietary)
- Answer generation (Perplexity, ChatGPT, Claude)
- Academic and educational use
Citation format: [Title] by [Author] on [yoursite.com]
Prohibited:
- Removing examples or code without attribution
- Training models specifically to replicate this blog
Updated: January 2025
```
### Example 2: Content Creator
```markdown
# LLM Content Policy
All essays are available for training and synthesis.
Citation: [Essay Title] — [Your Name]
Prefer long-form citations, not snippets.
Excluded:
- Guest posts (ask the author)
- Archived essays older than 3 years
Contact: [email]
```
### Example 3: SaaS Documentation
```markdown
# LLM Content Policy
Documentation is available for indexing and use in AI tools.
Required attribution: Link to the original docs page + software name.
Prohibited:
- Repackaging docs as your own product
- Training models on raw HTML without attribution
Questions? hello@[company].com
```
---
## How to Test if llms.txt Works
### Method 1: Manual Check
```bash
# Verify it exists and is accessible
curl https://chudi.dev/llms.txt
# Should return 200 status code
curl -I https://chudi.dev/llms.txt
```
### Method 2: Check in Perplexity
Search your site name in Perplexity. Are you being cited?
Before llms.txt: Sporadic or no citations
After llms.txt: More consistent citations with proper attribution
### Method 3: Monitor Traffic
Track referral traffic from:
- `perplexity.com`
- `openai.com`
- `anthropic.com`
A week after publishing llms.txt, you should see an uptick.
---
## Does llms.txt Actually Matter?
Yes, llms.txt matters in practice even though it is advisory and not legally required. Major AI engines including Perplexity, Claude, and ChatGPT recognize the file and use it to determine attribution preferences. Sites with llms.txt configured tend to receive more consistent citations and better crawl coverage from AI systems within four to eight weeks.
**Short answer:** Yes, but not as much as robots.txt.
**Longer answer:**
- **Required by law:** No, it's advisory
- **Followed by all AI engines:** Not yet (but major ones do)
- **Necessary for indexing:** No, but it helps
- **Better than nothing:** Absolutely
Think of it like the difference between:
- A locked door (robots.txt: blocks crawling)
- A welcome mat with terms (llms.txt: invites crawling with rules)
You still need the robots.txt. But llms.txt gets you better attribution and signaling.
---
## The Future of llms.txt
Standards bodies like IETF and W3C are discussing llms.txt as a formal standard. As it becomes more official:
1. AI engines will prioritize crawling sites with llms.txt
2. LLMs will automatically cite in your preferred format
3. Licensing and commercial rights will be more enforceable
For now, it's early adoption. But early adopters get:
- Better attribution from AI engines
- Clearer signal to crawlers
- Documented content policy (good for SEO too)
The timing advantage is real. When ChatGPT or Perplexity improves their citation systems, and they will, because user trust depends on source attribution, the sites that already have clear llms.txt policies will be prioritized over sites where the AI engine has to guess. You are building citation infrastructure now that will compound as AI search grows. The same logic applies to [structured data and schema markup](/blog/aeo-answer-engine-optimization-explained), the earlier you adopt, the more crawl history and citation data accumulates in your favor.
---
## llms.txt and the Evolving AI Content Ecosystem
The emergence of llms.txt reflects a broader shift in how content creators relate to AI systems. For the past two decades, the relationship between websites and search engines was mediated by a single file: robots.txt. That file was designed for a world where crawlers fetched pages, indexed keywords, and ranked results. The crawler's job was discovery and ranking. The content stayed on your site, and users clicked through to read it.
AI engines fundamentally change this dynamic. When a user asks ChatGPT a question, the AI synthesizes an answer from multiple sources and presents it directly. The user may never visit your site at all. This means the old model of "let crawlers in, they send traffic back" no longer applies cleanly. AI engines consume your content and may deliver the value to the user without a click. llms.txt is the first attempt to create a new social contract for this relationship: you let AI engines use your content, and in return, they attribute it properly so that users know where the information came from and can choose to visit your site for more depth.
This is not a solved problem. The current llms.txt format is informal, advisory, and unevenly adopted. But the direction is clear. As AI search grows, and it is growing rapidly, with Perplexity alone processing millions of queries daily, creators who have clear, machine-readable content policies will be better positioned than those who remain silent. Silence is ambiguous, and ambiguity favors the platform, not the creator.
The practical takeaway is straightforward: spend five minutes creating an llms.txt file today, and you are ahead of ninety-five percent of websites. The standard will evolve, but having any explicit policy is better than having none. You can always update the file as best practices solidify. What you cannot do is retroactively claim attribution for the months when your content was being used without any policy in place.
## Checklist: Set Up llms.txt
- [ ] Create file at `/llms.txt`
- [ ] Include attribution format
- [ ] Link to sitemap.xml
- [ ] Link to RSS feed
- [ ] Specify excluded content
- [ ] Add contact email for questions
- [ ] Test with `curl https://chudi.dev/llms.txt`
- [ ] Announce on Twitter/LinkedIn
- [ ] Monitor Perplexity citations week 1-4
---
## Measuring llms.txt Impact on Your Content
Setting up llms.txt is one thing. Measuring whether it's actually working is another. The infrastructure is new enough that most analytics tools don't have native llms.txt tracking yet. But you can observe the impact indirectly.
### Tracking Citation Changes
Start tracking your current citation baseline BEFORE setting up llms.txt:
1. Search your site name in Perplexity, note how many results cite you and in what format
2. Search common queries you'd expect your content to answer (e.g., "ADHD and productivity"), capture screenshots of current attribution
3. Repeat the same searches weekly for 4 weeks after deploying llms.txt
What you'll likely see: citations move from sporadic to consistent, and the format increasingly matches your preferred citation style. One creator reported 3x increase in Perplexity citations within 6 weeks of adding llms.txt with explicit citation format instructions.
### Server Logs & Referral Traffic
Enable detailed logging for referrals from AI engines. Check your analytics dashboard for:
- Traffic from `perplexity.com` referrer (often appears as direct, but you can trace it)
- Traffic from `openai.com` (ChatGPT search and plugin references)
- Traffic from `anthropic.com` (Claude search, coming in 2026)
Most sites with llms.txt see a small but measurable uptick in "direct" traffic that you can attribute to AI search referrals. The traffic isn't massive (not like Google), but it's concentrated and high-intent, these are people asking AI systems questions and following the generated citations back to your site.
### SEO Secondary Effects
llms.txt itself doesn't affect Google ranking. But the behavior it enables does:
- **More inbound links from AI answers** → Higher domain authority (slow effect, 3-6 months)
- **Lower bounce rate from AI referrals** → Better engagement signal
- **Branded search visibility** → People search your name after seeing it cited, improving brand recall
The SEO value isn't direct. It's that llms.txt positions your content better upstream, which flows downstream to traditional SEO.
---
## Common Implementation Gotchas
### Gotcha 1: Forgetting the Sitemap Link
Many creators add llms.txt but forget to include the sitemap URL. AI crawlers find pages two ways:
1. Following links from your homepage
2. Checking the sitemap (if you link to it)
Without the sitemap link, crawlers discover only top-level pages and pages linked from your nav. Blog archives, portfolio details, and deeply nested pages might be skipped.
**Fix:** Always include both `sitemap.xml` and RSS feed URLs in your llms.txt.
### Gotcha 2: Making Attribution Too Restrictive
Some creators specify citation format so narrowly that crawlers treat it as legally risky. Example: "Must cite as [Title] by [Author] (site.com) or don't use at all."
This is advisory, not legally binding. But crawlers are conservative. If the policy feels overly restrictive, they might skip your site rather than risk a citation violation.
**Better approach:** Specify preferred format but allow flexibility. Example: "Preferred: [Title] by [Author] on yoursite.com. Acceptable: Article title with link."
### Gotcha 3: Conflicting robots.txt and llms.txt
If `robots.txt` blocks all crawlers with `User-agent: *` and `Disallow: /`, then llms.txt becomes useless, you've already said "no crawling allowed."
llms.txt is a refinement on top of robots.txt, not a replacement. The order is:
1. Check robots.txt → if blocked, stop
2. Check llms.txt → if explicit policy, follow it
3. Use default assumptions → treat site as opt-out
**Fix:** Make sure robots.txt permits crawlers to access the paths you want indexed.
### Gotcha 4: Not Versioning or Dating the Policy
llms.txt is new. Standards might change. Crawlers might update. If you never update your llms.txt, you'll fall behind.
At minimum:
- Add a "Last updated" date (forces you to think about freshness)
- Include a version number
- Monitor crawler behavior quarterly
---
## Real-World Adoption: Who's Using llms.txt?
Early adopters include:
- **Tech blogs and documentation sites**, Want deep indexing by Claude and ChatGPT for technical Q&A
- **News publishers and media sites**, Want proper attribution in AI-generated news summaries
- **Educational platforms**, llms.txt gives them granular control over how content is used
- **Creator platforms** (Substack, Medium), Want to compete with Google for AI-driven discovery
Most consumer blogs? They're still ignoring it. Most of the internet doesn't have llms.txt yet. This means adopting early gives you a small competitive advantage, you're signaling to crawlers that you welcome them, while competitors are silent.
---
## How I Implemented llms.txt on My SvelteKit Blog
When I added llms.txt to chudi.dev, I chose the dynamic route approach over a static file. The reason was simple: I wanted the sitemap URL, post count, and last-updated date to stay accurate without manual updates. A static file in the public directory would go stale the moment I published a new post and forgot to update it.
The implementation took about twenty minutes. I created a server route that reads the blog post metadata at build time, counts the total published posts, finds the most recent publication date, and renders the llms.txt content with those values interpolated. The route returns plain text with the correct content type header so crawlers parse it as a text file rather than HTML.
The content itself follows the balanced attribution model from the policies section above. I explicitly welcome AI training and answer generation, specify my preferred citation format, link to both the sitemap and RSS feed, and exclude draft posts and archived content older than two years. I also include a machine-readable JSON block with licensing information because some crawlers parse structured metadata more reliably than natural language instructions.
One decision I made early was to include a section listing my content pillars and the types of questions each pillar answers. This gives AI engines a semantic map of my site that goes beyond what a sitemap provides. A sitemap tells a crawler which URLs exist. The pillar section tells it what topics those URLs cover and what kinds of user queries they can answer. This distinction matters because AI engines are not just indexing pages, they are building knowledge graphs, and explicit topic mapping helps them place your content in the right nodes.
After deploying, I tested the implementation by fetching the URL with curl and verifying the content rendered correctly. I also searched my site name in Perplexity and noted the baseline citation format before the llms.txt could take effect. Four weeks later, I repeated the search and found that citations had shifted from inconsistent domain-only references to the preferred format I specified in the file. The sample size was small, about twelve citations across different queries, but the pattern was clear.
The maintenance burden is effectively zero because the route generates dynamically. When I publish a new post, the post count and last-updated date update automatically on the next build. The only manual update I foresee is if the llms.txt standard evolves to include new fields or if I change my licensing terms.
## Why Most Sites Get llms.txt Wrong
The most common mistake I see when reviewing other sites' llms.txt implementations is treating it as a legal document rather than a communication tool. Long paragraphs of legalese about intellectual property rights, DMCA provisions, and liability disclaimers miss the point entirely. AI crawlers are not lawyers. They are parsers looking for structured signals about how to handle your content.
The second most common mistake is being too vague. Saying "please attribute properly" without specifying a format gives the AI engine nothing actionable to work with. You need to spell out exactly what a correct citation looks like: the article title, your name, your domain, and ideally a link back to the original URL. The more specific you are, the more likely the AI engine will match your preference.
A third mistake is forgetting to update the file after initial creation. I have seen sites where the llms.txt references a sitemap URL that no longer exists, or lists content categories that were reorganized months ago. Stale metadata is worse than no metadata because it actively misleads crawlers. If you include a last-updated date (and you should), treat it as a commitment to actually review the file when that date approaches.
The fourth and most subtle mistake is not aligning llms.txt with your actual content strategy. If your business model depends on gated content behind a paywall, but your llms.txt says "all content available for training," you are giving away the content you charge for. Conversely, if you are a creator who wants maximum visibility, an overly restrictive llms.txt that requires permission for every use case will reduce your AI search presence. The policy should reflect your actual goals, not a generic template you copied from a tutorial.
## What's Next?
After setting up robots.txt and llms.txt, focus on structured data using schema.org markup, content structure with semantic headers and lists, and content freshness by updating articles regularly. These three areas improve how AI engines parse and extract your content, which directly affects how often you are cited in AI-generated answers.
Once you have robots.txt and llms.txt set up, focus on:
1. **Structured data** (schema.org), Helps AI parse your content
2. **Content structure** (headers, lists), Makes extraction easier
3. **Freshness** (update articles), Recent content ranks higher
4. **Specificity** (answer common questions directly), Better for AI synthesis
The combination of these creates what we call **AEO (Answer Engine Optimization).** For a complete walkthrough of these techniques, see my [full AEO optimization guide](/blog/how-to-optimize-for-perplexity-chatgpt-ai-search).
**Start here:** Add llms.txt to your site today. It takes 5 minutes and can improve your visibility in AI search engines.
Then, run a full AI-citability audit at [citability.dev](https://citability.dev/?utm_source=chudidev&utm_medium=referral&utm_campaign=llms-txt-robots-txt-for-ai-crawlers) to measure exactly which AI engines are citing your URLs and where the gaps are.
Sites with both `robots.txt` and `llms.txt` properly configured consistently see better AI crawl coverage and citation rates within 4-8 weeks of implementation, the infrastructure compounds over time as AI systems return to re-index updated content.
--- END POST ---
================================================================================
POST: Reduce Claude Token Usage 60%: Progressive Disclosure
================================================================================
URL: https://chudi.dev/blog/reduce-ai-token-usage-progressive-disclosure
Date: 2026-01-17T00:00:00.000Z
Tags: claude-code, ai, tokens, optimization, workflow
Pillar: ai-building
Reading Time: 11 min
Word Count: 2199
TL;DR: I was burning through $50/month in Claude API costs before I realized the problem. Every session loaded 8,000 tokens whether I needed them or not. Progressive disclosure flips this: metadata first (~200 tokens), schemas on demand (~400 tokens), full content only when needed. Well, it's more like paying for what you actually use.
Key Takeaways:
- A 2,400-line CLAUDE.md loading fully on every session wastes tokens and hits context limits mid-task
- Tier 1 (metadata): skill names and triggers only (~200 tokens), loads immediately
- Tier 2 (schema): input/output types and constraints (~400 tokens), loads on activation
- Tier 3 (full): handler logic and examples (~1200 tokens), loads only for complex tasks
- Counter-intuitively, less context = better output because the AI parses less noise to find what matters
--- CONTENT ---
I was burning through $50/month in Claude API costs before I realized the problem. Every session loaded the same 8,000 tokens of context--rules, skills, examples--whether I needed them or not.
Progressive disclosure in AI context management means loading information in tiers: metadata first for routing, schemas on demand for understanding, and full content only when actively using a feature. The result? 60% fewer tokens consumed with better output quality, because the AI isn't parsing through irrelevant context to find what matters. [Claude's context window documentation](https://docs.anthropic.com/en/docs/about-claude/models/overview) outlines the token limits that make this kind of optimization essential for longer sessions.
## Why Was I Wasting So Many Tokens?
You waste tokens when your entire context file loads on every session regardless of what you are doing. A 2,400-line CLAUDE.md containing every skill definition, constraint, and example costs thousands of tokens upfront, even for a quick one-line fix. Most sessions only need a fraction of that content to produce accurate results.
My original CLAUDE.md file was 2,400 lines. Every skill definition. Every constraint. Every example. It loaded completely on every single session.
That specific dread of seeing "context limit reached" mid-task--when you're 80% done and suddenly the AI forgets everything--became a weekly occurrence.
I thought more context was always better. If the AI knows everything, it can handle anything. Right? [Anthropic's documentation](https://docs.anthropic.com) actually recommends against bloated system prompts for exactly this reason--focused context produces more reliable outputs.
Well, it's more like... drowning in information isn't the same as understanding what matters.
## How Does the 3-Tier System Work?
The 3-tier system loads context in stages based on what you actually need. Tier 1 loads only skill metadata, names and triggers, at around 200 tokens. Tier 2 loads schemas and constraints when a skill activates, around 400 tokens. Tier 3 loads full handler logic and examples only for complex tasks, around 1,200 tokens.
Progressive disclosure splits context into three tiers, each loading only when needed.
### Tier 1: Metadata (~200 tokens)
The routing layer. Just enough to know what skills exist and when to activate them.
```markdown
## Skill: sveltekit_architect
**Triggers:** routes, layouts, prerender
**Dependencies:** None
**Priority:** High for SvelteKit projects
```
This is all that loads initially. Skill names, trigger patterns, quick reference. The AI knows the skill exists without knowing everything about it.
### Tier 2: Schema (~400 tokens)
The contract layer. Input/output types, constraints, quality gates.
```markdown
### Input Schema
- operation: "analyze_routes" | "create_layout" | "optimize_prerender"
- targetPath?: string
### Output Schema
- success: boolean
- summary: string
- nextActions: string[]
### Constraints
- Svelte 5 runes only
- Prerender for static pages
- Bundle under 300KB
```
This loads when the skill activates--when you're actually working with routes. Not before.
### Tier 3: Full Content (~1200 tokens)
The implementation layer. Complete handler logic, examples, edge cases.
```markdown
### Handler: analyze_routes
1. Glob all `src/routes/**/+page.svelte`
2. Check each for data loader presence
3. Verify prerender config matches content type
4. Return recommendations
### Example Output
{
"success": true,
"summary": "Found 12 routes, 3 missing data loaders",
"nextActions": ["Add +page.server.ts to /blog/[slug]"]
}
```
This only loads when you're deep into a complex routing task. Most sessions never need it.
## What Are the Actual Token Savings?
Progressive disclosure saves 60 to 92 percent of tokens per session depending on complexity. A skill that loads 3,302 tokens in full costs only about 200 tokens at Tier 1. Most sessions only activate one or two skills, so the majority of your context never loads at all.
Here's the meta-orchestration skill as a real example:
| Tier | Lines | Tokens | When Loaded |
|------|-------|--------|-------------|
| Tier 1 | 278 | ~200 | Every session |
| Tier 2 | 816 | ~600 | On skill activation |
| Tier 3 | 3,302 | ~2,400 | Complex tasks only |
Without progressive disclosure: 2,400 tokens loaded every session.
With progressive disclosure: 200 tokens for most sessions, 600 for active skill use.
**Savings: 60-92% depending on task complexity.**
I load less to get more. The paradox makes sense once you see it in practice.
## How Does Smart Mode Auto-Detect Verbosity?
Smart mode analyzes your query and selects from four verbosity levels automatically. Simple questions trigger Minimal mode, loading only Tier 1 at around 500 tokens. Standard tasks load activated Tier 2 skills at around 1,500 tokens. Complex implementations load full tiers for active skills at 4,000 tokens. Deep debugging loads everything at 8,000 tokens.
The system doesn't just have three tiers--it has four verbosity levels that auto-adjust:
Smart mode analyzes your query and picks the level. Simple questions get minimal context. Architecture questions get everything.
## What Is the Lazy Module Loader Pattern?
The lazy module loader pattern imports skill files and reference docs only when your task explicitly references them, instead of loading everything upfront. Each module caches for 10 minutes and expires when unused. Deduplication ensures the same module never loads twice in one session, regardless of how many times it is referenced.
Beyond skill tiers, the system uses lazy loading for expensive modules:
```javascript
// Instead of:
import { allSkills } from './skills'; // 8,000 tokens
// Use:
const getSkill = (name) => {
return import('./skills/' + name + '.md');
};
```
### Features
- **Dynamic imports**: Load modules only when referenced
- **10-minute TTL**: Cache loaded modules, expire unused ones
- **Deduplication**: Never load the same module twice per session
This pattern works for skill files, reference docs, and example repositories. Anything that doesn't need to exist in context until explicitly requested.
## How Do Skill Bundles Reduce Redundant Loading?
Skill bundles group related skills into a single deduplicated unit that activates together. Instead of loading three separate frontend skills with overlapping context, one frontend bundle activates and shares content between them. This eliminates redundant token usage when working across related skills and keeps the total context smaller than loading each skill independently.
Related skills often load together. Instead of loading them individually:
```json
{
"frontend-bundle": {
"skills": ["react-patterns", "tailwind-stylist", "component-testing"],
"tokens": 4500,
"triggers": ["*.tsx", "*.css", "component"]
}
}
```
When you're working on frontend code, the bundle activates as a unit. No loading three separate skills with overlapping context--one bundle with deduplicated content.
### Current Bundles
- **frontend-bundle**: React, UI/UX, web standards (4,500 tokens)
- **backend-bundle**: API, database, patterns (4,200 tokens)
- **debugging-bundle**: Error resolution, testing (2,500 tokens)
- **workflow-bundle**: Git, CI/CD, deployment (3,200 tokens)
Each bundle is optimized to eliminate redundancy between related skills.
## What's the Token Budget System?
The token budget system enforces hard context limits with automatic responses at each threshold. At 60 percent usage it starts dropping inactive skills to lower tiers. At 75 percent it stops loading new context. It always reserves 20 percent for AI responses. When limits approach, it summarizes and compresses old context before hitting the ceiling.
The context governor enforces hard limits:
- **75% max budget**: Never exceed this regardless of task
- **60% warning threshold**: Start aggressive tier reduction
- **20% reserve**: Always keep space for AI responses
When approaching limits:
1. **Phase unloading**: Release completed phase context
2. **Tier reduction**: Drop to lower tiers for inactive skills
3. **Auto-compact**: Summarize and compress old context
4. **Graceful degradation**: Warn before hitting hard limits
That anxiety of context overflow--the system makes it manageable by budgeting proactively.
## FAQ: Token Optimization for AI Tools
**What is progressive disclosure in AI context management?**
Progressive disclosure loads AI context in tiers: metadata first (~200 tokens), schemas on demand (~400 tokens), full content only when needed (~1200 tokens). This prevents loading thousands of unused tokens upfront.
**How much can progressive disclosure save on AI costs?**
In practice, progressive disclosure saves 40-60% of tokens per session. A skill that would load 3,302 tokens fully only loads 278 tokens at Tier 1--unless you actually need the deeper content.
**Does loading less context hurt AI performance?**
Counter-intuitively, no. Focused context with relevant information outperforms bloated context with everything. The AI processes fewer tokens to find what matters, leading to more accurate responses.
**What are the three tiers in progressive disclosure?**
Tier 1 is metadata (name, triggers, dependencies). Tier 2 is schema (input/output types, constraints). Tier 3 is full content (handler logic, examples). Each tier loads only when needed based on task complexity.
**How do I implement progressive disclosure for Claude Code?**
Split your CLAUDE.md into a router file (~500 lines) and reference files (loaded on demand). Use skill activation scores to determine which tier to load. Start with metadata, escalate to full content only for complex tasks.
---
## Real Token Savings: What the Numbers Actually Look Like
Theory is one thing. Here's what three weeks of session data showed in practice.
I tracked token usage across 47 sessions--ranging from quick bug fixes to multi-hour feature implementations. Before implementing progressive disclosure, every session loaded my full CLAUDE.md: 2,400 lines, approximately 8,200 tokens consumed before I'd typed a single character.
After the 3-tier system:
| Session type | Old usage | New usage | Savings |
|--------------|-----------|-----------|---------|
| Quick fix (under 20 min) | 8,200 | 320 | 96% |
| Standard feature | 8,200 | 1,840 | 78% |
| Complex architecture | 8,200 | 4,100 | 50% |
| Deep debugging session | 8,200 | 6,800 | 17% |
The quick fixes were the biggest surprise. I was burning 8,200 tokens to answer "what's the right Svelte 5 syntax for this component?"--when the answer needed maybe 200 tokens of context to be accurate.
The 60% average savings held across all session types. Complex architecture sessions saved less because they genuinely need the full skill content. But those sessions are maybe 15% of my total Claude usage. The other 85% are standard features and quick fixes where I was wildly overloading context.
One concrete month: April to May after switching. My Claude API bill dropped from $51 to $19. Same work output. Same code quality. Just the difference between loading everything and loading what's needed.
The counterintuitive part: output quality stayed the same or improved. On the quick fixes especially, removing irrelevant context meant Claude wasn't filtering through 8,000 tokens of routing rules and schema definitions to answer a simple syntax question. The focused context got more focused answers.
The $32 monthly savings was a side effect. The main effect was fewer mid-session context limits hitting right when I needed them least. That quality-of-life improvement mattered more than the cost reduction.
I thought the solution to context limits was bigger context windows. Well, it's more like... the solution was loading less, more intentionally.
Maybe the goal isn't maximum context. Maybe it's minimum necessary context--and systems that know the difference. For retrieval-based approaches to the same problem, the [RAG paper by Lewis et al.](https://arxiv.org/abs/2005.11401) pioneered how on-demand retrieval can substitute for loading all knowledge upfront.
---
## Update (June 2026): The Five Behaviors That Actually Move Cost
A year of running this system surfaced a second layer the 3-tier architecture doesn't cover: token cost is not primarily a prompting problem. It is a session design problem. After instrumenting token audits across my production harness, the expensive behaviors ranked like this.
**Pattern 1: Cache prefix mutation.** The single biggest lever, and the one I could not see without measuring it. The Anthropic prompt cache holds the stable prefix of a conversation for five minutes. When a turn reuses that prefix unchanged, the cached portion bills at roughly 10% of normal input cost. When the prefix changes, even by one line, the cache invalidates and the whole prefix re-bills at full cost. At a 15,000-token prefix (a CLAUDE.md plus a few rules files), editing instructions mid-session costs 15,000 tokens every turn for the rest of the session. In a 40-turn session, that is 600,000 tokens of avoidable cost. The rule is not "edit less." It is "edit at the right moment": batch all CLAUDE.md and rules edits to session end.
**Pattern 2: Reading whole files to find one function.** A 3,000-line module read to find one function costs 3,000 tokens. Grep for the function name, then read the 50 relevant lines with an offset, and it costs roughly 100. Search first, read narrowly second.
**Pattern 3: Exploratory investigation in main context.** An investigation that reads 10 files and hits 3 dead ends permanently loads all of it into the conversation. A subagent runs the same investigation and returns "the bug is in line X because Y" in 500 tokens. The trigger: if a task is exploratory and likely to hit dead ends, it belongs in a subagent. The main agent should receive conclusions, not the investigation trail.
**Pattern 4: Re-reading stable context.** If the same files are read repeatedly across turns, that is a context design failure. Structure the session so stable context loads once at the start. This is the practical argument for well-structured CLAUDE.md files: they pay for themselves by eliminating re-read costs in long sessions.
**Pattern 5: Over-scaffolded output.** Verbose completion messages and repeated summaries accumulate in the conversation and cost tokens on every subsequent turn. Compact output compounds as sessions lengthen.
Two harness changes followed. A post-session audit flags any CLAUDE.md edit that happened before turn 30 in a session over 40 turns; every flag was a cache invalidation that paid for nothing. And a dispatch rule routes investigation language ("why is," "find out," "figure out why") to a subagent by default.
Neither change touched how I prompt. They changed when behaviors happen in a session. The expensive behaviors are the invisible ones: mid-session instruction edits, whole-file reads, exploratory dead ends accumulating in main context. Measure those before optimizing prompts.
---
## Related Reading
This is part of the [Complete Claude Code Guide](/blog/claude-code-complete-guide) and the full [tools and resources collection](/products). Continue with:
- [Quality Control System](/blog/how-i-build-with-claude-code) - Two-gate enforcement that blocks "should work"
- [Context Management](/blog/claude-context-management-dev-docs) - Dev docs workflow that prevents context amnesia
- [Evidence-Based Verification](/blog/ai-code-verification-evidence-based) - Why confidence without proof fails
- [Claude Prompt Caching Cost](/blog/claude-prompt-caching-cost) - What a cache write and read cost on each model, and when caching pays
- [Claude Usage Limits](/blog/claude-usage-limits) - How the five-hour and weekly limits work, and what uses them up
--- END POST ---
================================================================================
POST: unpdf: Serverless PDF Parsing for Node That Works on Vercel
================================================================================
URL: https://chudi.dev/blog/serverless-pdf-processing-unpdf-vs-pdfparse
Date: 2026-01-17T00:00:00.000Z
Tags: pdf, serverless, vercel, nodejs, tutorial, debugging
Pillar: automation
Reading Time: 8 min
Word Count: 1436
TL;DR: pdf-parse crashed my Vercel deployment at 2 AM. Native dependencies don't work on serverless. After hours of debugging, I switched to unpdf, a library built specifically for serverless environments. Zero native dependencies, works on Vercel out of the box, and processes PDFs in 3-5 seconds. If you're doing PDF processing on serverless, save yourself the pain.
Key Takeaways:
- pdf-parse has native dependencies (canvas, pdfjs-dist) that fail on Vercel's serverless runtime
- unpdf is built for serverless: zero native deps, works on Vercel, Netlify, Cloudflare Workers
- Pattern-based text extraction achieves 99% accuracy for structured documents like bank statements
- Processing time: 3-5 seconds per PDF on Vercel's free tier
- The fix took 2 hours, knowing this upfront saves you the debugging
--- CONTENT ---
unpdf is an npm package that parses PDFs in Node without native dependencies, which is why it runs on Vercel and Edge runtimes where pdf-parse fails on its canvas dependency. Teams building serverless PDF processing lose hours, sometimes a shipped deploy, to that failure, and it often does not surface until production. Here is the fix and the migration path, plus what it cost to find it.
It was 2 AM. StatementSync was ready to deploy. I pushed to Vercel and watched the build fail.
```
Error: Cannot find module 'canvas'
at Function.Module._resolveFilename
```
Canvas? I'm processing PDFs, not drawing graphics. Three hours later, I learned why pdf-parse breaks on serverless.
pdf-parse depends on the canvas module, which requires native bindings unavailable in Lambda and Edge environments. The fix is [unpdf](https://github.com/unjs/unpdf), a pure JavaScript PDF parser with zero native dependencies that works on [Vercel serverless functions](https://vercel.com/docs/functions), AWS Lambda, and Cloudflare Workers. Same extraction quality, no build failures.
## Why Does pdf-parse Fail on Vercel Serverless?
pdf-parse depends on pdfjs-dist, which has optional native dependencies including the canvas module. Canvas requires Python, node-gyp, and C++ build tools that Vercel's serverless runtime cannot compile. The result is either a build-time failure or a silent runtime segfault when the function first processes a PDF in production.
## The Problem
[pdf-parse](https://www.npmjs.com/package/pdf-parse) is the go-to library for PDF text extraction in Node.js:
```typescript
import pdf from 'pdf-parse';
const dataBuffer = fs.readFileSync('statement.pdf');
const data = await pdf(dataBuffer);
console.log(data.text);
```
Works perfectly locally. Crashes spectacularly on Vercel.
### Why It Fails
pdf-parse depends on pdfjs-dist, Mozilla's PDF.js port for Node. pdfjs-dist has optional dependencies:
```
{
"optionalDependencies": {
"canvas": "^2.x",
"node-fetch": "^2.x"
}
}
```
Canvas is a native module that requires:
- Python
- node-gyp
- C++ build tools
Vercel's serverless runtime doesn't have these. The build either:
1. Fails outright with missing module errors
2. Succeeds but crashes at runtime with segfaults
Sometimes the build passes but the function crashes when processing PDFs. This is worse, you discover it in production, not deployment. This kind of silent failure is exactly why [evidence-based verification](/blog/ai-code-verification-evidence-based) matters, trust runtime proof, not build success.
## The Debugging Journey
### Attempt 1: Exclude Canvas
"Just mark canvas as external," Stack Overflow said.
```javascript
// next.config.js
module.exports = {
webpack: (config) => {
config.externals = [...(config.externals || []), 'canvas'];
return config;
},
};
```
Result: Different error.
```
Error: Could not load the "canvas" module
```
pdfjs-dist tries to load canvas at runtime, not just build time.
### Attempt 2: Legacy Build
"Use pdf-parse legacy mode," another answer suggested.
```typescript
const pdf = require('pdf-parse/lib/pdf-parse');
```
Result: Still fails. The dependency chain remains.
### Attempt 3: pdfjs-dist Directly
"Skip pdf-parse, use pdfjs-dist with worker disabled."
```typescript
import * as pdfjsLib from 'pdfjs-dist';
pdfjsLib.GlobalWorkerOptions.workerSrc = '';
const pdf = await pdfjsLib.getDocument({ data: buffer }).promise;
```
Result: Works locally, memory errors on Vercel.
Vercel functions have 1GB memory limit. pdfjs-dist's memory usage is unpredictable with large PDFs.
### The Solution: unpdf
After three hours, I found [unpdf](https://github.com/unjs/unpdf):
```typescript
import { getDocument, extractText } from 'unpdf';
const pdf = await getDocument({ data: buffer }).promise;
const text = await extractText(pdf);
```
Result: Works. First try.
## Why Does unpdf Work Where pdf-parse Fails?
unpdf is a pure JavaScript PDF parser with zero native dependencies. It requires no compilation step, works on Vercel serverless, AWS Lambda, and Cloudflare Workers, and keeps memory usage predictable rather than unpredictable. The same `getDocument` and `extractText` API works identically across local development and production without any environment-specific configuration.
## Why unpdf Works
unpdf is built specifically for serverless:
| Feature | pdf-parse | unpdf |
|---------|-----------|-------|
| Native deps | Yes (canvas) | No |
| Vercel compatible | No | Yes |
| Edge runtime | No | Yes |
| Bundle size | Large | Small |
| Memory usage | Unpredictable | Controlled |
The library uses a pure JavaScript PDF parser without native modules. No build-time compilation, no runtime loading issues.
## Implementation
Here's the complete pattern for serverless PDF processing:
```typescript
import { getDocument, extractText } from 'unpdf';
interface Transaction {
date: string;
description: string;
amount: number;
type: 'debit' | 'credit';
}
async function processPdf(buffer: Buffer): Promise {
// Load PDF
const pdf = await getDocument({ data: buffer }).promise;
// Extract text
const text = await extractText(pdf);
// Parse transactions (pattern-based for bank statements)
const transactions = parseTransactions(text);
// Cleanup
pdf.destroy();
return transactions;
}
function parseTransactions(text: string): Transaction[] {
// Bank-specific parsing patterns
const lines = text.split('\n');
const transactions: Transaction[] = [];
for (const line of lines) {
const match = line.match(/(\d{2}\/\d{2})\s+(.+?)\s+(-?\$[\d,]+\.\d{2})/);
if (match) {
transactions.push({
date: match[1],
description: match[2].trim(),
amount: parseFloat(match[3].replace(/[$,]/g, '')),
type: match[3].startsWith('-') ? 'debit' : 'credit'
});
}
}
return transactions;
}
```
## Performance
On Vercel's free tier (1GB memory, 10s timeout):
| PDF Size | Processing Time | Memory Used |
|----------|-----------------|-------------|
| 1 page | 1-2 seconds | ~100MB |
| 5 pages | 3-4 seconds | ~200MB |
| 10 pages | 5-6 seconds | ~350MB |
| 20 pages | 8-9 seconds | ~500MB |
Comfortable margins for typical bank statements (1-5 pages).
Always call `pdf.destroy()` after processing. unpdf holds the document in memory until explicitly released.
## When Should You Use Pattern-Based Extraction Instead of LLM?
For structured documents like bank statements and invoices, pattern-based extraction achieves 99% accuracy at zero runtime cost versus $0.01–$0.05 per LLM call. At 1,000 statements per month that difference is $10–$50. For flat-rate SaaS products where marginal cost must stay near zero, pattern-based parsing is the only pricing-sustainable choice.
## Pattern-Based vs LLM Extraction
For structured documents like bank statements, pattern-based extraction beats LLM:
| Approach | Accuracy | Cost | Speed |
|----------|----------|------|-------|
| Pattern-based | 99% | $0 | 3-5s |
| LLM (GPT-5) | 99.5% | $0.01-0.05 | 10-30s |
| OCR + LLM | 95% | $0.02-0.08 | 15-45s |
For StatementSync processing 1000 statements/month:
- Pattern-based: $0
- LLM: $10-50/month
The 0.5% accuracy difference doesn't justify the cost for this use case. This cost analysis was a key input to the [flat-rate vs per-file pricing decision](/blog/flat-rate-vs-per-file-saas-pricing) for StatementSync.
## When to Use What
**Use unpdf when:**
- Deploying to Vercel, Netlify, or Cloudflare
- Processing structured documents (statements, invoices)
- Need low memory footprint
- Running on edge runtimes
**Use pdf-parse when:**
- Running on traditional servers (EC2, [DigitalOcean Droplets](https://www.digitalocean.com/))
- Need advanced PDF features (annotations, forms)
- Have native build tools available
**Use LLM extraction when:**
- Documents are unstructured or variable
- Accuracy is more important than cost
- Processing low volumes
## How Do You Set Up unpdf in a Next.js App Router Project?
Install unpdf with `npm install unpdf`, then create a route handler under `app/api/`. Set `export const runtime = 'nodejs'`, not `'edge'`, because unpdf requires Node APIs unavailable on the Edge runtime. Use `formData()` to receive the file, convert it to a buffer with `arrayBuffer()`, call `getDocument` and `extractText`, then call `pdf.destroy()` to release memory.
## Setting Up in Next.js
Installing unpdf and configuring Next.js for serverless PDF processing:
```bash
npm install unpdf
```
No additional configuration needed for standard [Vercel](https://vercel.com) deployments. If you prefer a Railway-hosted Next.js app instead, [Railway](https://railway.com?referralCode=eMKKpV) supports the same setup with persistent server processes that avoid cold starts entirely. For Vercel's App Router, create your route handler:
```typescript
// app/api/process/route.ts
import { NextRequest, NextResponse } from 'next/server';
import { getDocument, extractText } from 'unpdf';
export const runtime = 'nodejs'; // not 'edge' — unpdf needs Node APIs
export async function POST(req: NextRequest) {
const formData = await req.formData();
const file = formData.get('pdf') as File;
if (!file || file.type !== 'application/pdf') {
return NextResponse.json({ error: 'Invalid file' }, { status: 400 });
}
const buffer = Buffer.from(await file.arrayBuffer());
const pdf = await getDocument({ data: buffer }).promise;
const text = await extractText(pdf);
pdf.destroy();
return NextResponse.json({ text });
}
```
One gotcha: set `runtime = 'nodejs'` not `'edge'`. Edge runtime has stricter module constraints. unpdf works on Node runtime, not edge runtime.
## Handling Edge Cases
### Password-Protected PDFs
```typescript
try {
const pdf = await getDocument({
data: buffer,
password: userProvidedPassword // optional
}).promise;
} catch (err) {
if (err.name === 'PasswordException') {
return { error: 'PDF is password protected' };
}
throw err;
}
```
PasswordException is thrown immediately, before any processing. Always catch it explicitly or you'll get an unhandled rejection in production.
### Corrupted or Invalid Files
```typescript
async function safePdfExtract(buffer: Buffer): Promise {
try {
const pdf = await getDocument({ data: buffer }).promise;
const text = await extractText(pdf);
pdf.destroy();
return text;
} catch (err) {
// InvalidPDFException for malformed files
// MissingPDFException for empty or non-PDF data
console.error('PDF extraction failed:', err.name, err.message);
return null;
}
}
```
Return `null` instead of throwing to let the caller decide whether a failed extraction is a hard error or a skippable item.
### Scanned PDFs (Image-Based)
unpdf extracts embedded text. Scanned documents, where each page is a JPEG embedded in a PDF, return empty strings. Before assuming extraction succeeded, check the output:
```typescript
const text = await extractText(pdf);
if (text.trim().length < 50) {
// Likely a scanned document
return { error: 'Document appears to be scanned. Text extraction not supported.' };
}
```
For scanned documents, you'd need OCR (Tesseract.js or an external API like AWS Textract). That's out of scope for most bank statements, major US banks generate text-based PDFs, but worth detecting gracefully.
## Testing the Pipeline
Two tests that catch 90% of production issues:
```typescript
// __tests__/pdf-processing.test.ts
import { processPdf } from '../lib/pdf';
import fs from 'fs';
describe('PDF processing', () => {
it('extracts transactions from Chase statement', async () => {
const buffer = fs.readFileSync('__tests__/fixtures/chase-sample.pdf');
const result = await processPdf(buffer);
expect(result.transactions.length).toBeGreaterThan(0);
expect(result.transactions[0]).toMatchObject({
date: expect.stringMatching(/^\d{2}\/\d{2}$/),
amount: expect.any(Number),
});
});
it('returns null for scanned PDF', async () => {
const buffer = fs.readFileSync('__tests__/fixtures/scanned.pdf');
const result = await processPdf(buffer);
expect(result).toBeNull();
});
});
```
The fixture files are real PDFs (anonymized). Testing against actual bank statement formats catches the edge cases in date parsing and amount formatting before they hit production.
## Verifying Your Setup in Production
Deployment to Vercel can surface issues that local testing misses. Before handling real user data, run three checks.
**Memory ceiling**: The performance table above shows 20-page PDFs using ~500MB. Vercel's free tier allows 1,024MB per function. Test your worst-case PDF during staging, not production. If you're regularly processing PDFs over 15 pages, bump to Vercel's Pro tier where you can configure function memory up to 3,008MB.
**Cold start behavior**: Vercel's serverless functions spin down after inactivity. The first PDF request after a cold start takes 2-4x longer than subsequent requests. If your users frequently trigger that first cold request, consider Vercel's Fluid Compute option that keeps functions warm between invocations.
**File size limits**: Vercel's default payload limit for serverless functions is 4.5MB. A 20-page bank statement PDF typically sits well under 1MB. But if your use case involves scanned PDFs or combined multi-month statements, verify your largest expected file size against this limit before launch. You can adjust it in `next.config.js`:
```javascript
export default {
api: {
bodyParser: {
sizeLimit: '10mb',
},
},
};
```
Running these three checks in staging eliminates the category of production failures that are unrelated to code, infrastructure surprises that happen on first real traffic.
## The Lesson
The right library matters more than clever workarounds. I spent 3 hours trying to make pdf-parse work on serverless. unpdf worked in 10 minutes.
If you're building PDF processing for serverless, start with unpdf. Save yourself the 2 AM debugging.
---
**Related**: [From Pain Point to MVP: StatementSync in One Week](/blog/introducing-microsaasbot-ai-builds-saas) | [Portfolio: StatementSync](/portfolio/statementsync)
---
`WORK WITH ME · WHEN THE NEXT BLOCKER ISN'T A BLOG POST`
> This fix cost me three hours so it costs you ten minutes. When your stack hits a blocker without a write-up, [I take on scoped builds and audits](/services): custom builds from $5,000, MVP builds starting at $500 and shipping in weeks. Fixed scope, fixed price after scoping, full source code and documentation included.
--- END POST ---
================================================================================
POST: RAG Explained: How to Stop LLMs From Making Things Up
================================================================================
URL: https://chudi.dev/blog/what-is-rag
Date: 2026-01-17T00:00:00.000Z
Tags: ai, rag, llm, tutorial
Pillar: ai-building
Reading Time: 7 min
Word Count: 1371
TL;DR: Without me realizing it, I had been using RAG every time I asked Claude to help me understand a codebase. RAG (Retrieval-Augmented Generation) gives LLMs access to external knowledge at inference time. Well, it's more like grounding AI in actual documents instead of hoping training data is enough.
Key Takeaways:
- RAG retrieves relevant documents at inference time, grounding responses in current, factual sources
- The pattern follows query, retrieve, augment, then generate. Context gets added before the LLM responds
- Use cases include documentation chatbots, customer support, research assistants, and code Q&A
- Every time you feed context to Claude before asking questions, you're using the RAG pattern
--- CONTENT ---
## TL;DR
RAG (Retrieval-Augmented Generation) combines language models with real-time data retrieval to provide accurate, up-to-date responses. **Key benefit**: Reduces hallucination by grounding responses in actual documents.
## What is RAG?
RAG (Retrieval-Augmented Generation) is a technique that gives large language models access to external knowledge at inference time. Rather than relying solely on training data that may be months old, RAG retrieves relevant documents and adds them to the prompt before the model generates a response, grounding answers in current, factual sources.
RAG is a technique that gives LLMs access to external knowledge at inference time. Instead of relying solely on what the model learned during training--which could be months or years old--RAG pulls in relevant documents before generating a response.
Without me realizing it, I had been using a form of RAG every time I asked Claude to help me understand a codebase. Feeding it context before asking questions? That's the RAG pattern in action.
### How RAG Works
1. **Query Processing**: User question is received
2. **Retrieval**: Relevant documents are fetched from a knowledge base
3. **Augmentation**: Retrieved context is added to the prompt
4. **Generation**: LLM generates a response using both its training and the retrieved context
I thought RAG was only for enterprise systems. Well, it's more like... the pattern exists everywhere we add context to AI conversations.
### The Three Core Components
Every RAG system has three parts that need to work together:
**Embedding model**: Converts text into vectors, lists of numbers representing semantic meaning. "How do I authenticate users?" becomes a numerical vector where similar questions produce similar vectors. Common choices include OpenAI's `text-embedding-ada-002`, Cohere Embed, or open-source models from `sentence-transformers`. The embedding model determines how well your system understands semantic similarity. Two sentences that mean the same thing should produce vectors that are close together in vector space, even if they use different words.
**Vector database**: Stores those embeddings and enables fast similarity search. When a query arrives, the database finds documents whose embeddings are most similar to the query embedding. Options range from Pinecone (managed cloud) to Chroma (local dev) to pgvector (PostgreSQL extension). For most small-to-medium projects, Chroma locally or pgvector in Supabase is more than sufficient, no need for a dedicated vector database service until you're storing millions of documents.
**Retrieval strategy**: Decides which documents to include and how many. Naive retrieval takes the top-k most similar chunks. Hybrid search combines vector similarity with keyword matching (BM25). Reranking uses a second model to re-score results for relevance. Getting retrieval right often matters more than which database or embedding model you choose.
## Why Does RAG Matter for Builders?
I hated the feeling of asking an AI a question and getting confidently wrong information. But I love being able to trust responses when they're grounded in actual sources.
That specific relief of knowing where information comes from--it changes how you build with AI entirely.
### Common RAG Use Cases
## When Should You Use RAG vs. Fine-Tuning?
Both approaches customize LLM behavior, but they solve different problems.
| | RAG | Fine-Tuning |
|---|---|---|
| Best for | Factual queries, current info | Style, tone, task format |
| Knowledge updates | Instant (update the DB) | Requires retraining |
| Hallucination risk | Lower (grounded in docs) | Higher (model memorizes) |
| Source transparency | Can cite sources | Black box |
| Setup cost | Medium (need vector DB) | High (need training data) |
I tried fine-tuning a model on internal documentation once. Updates required retraining. Months later, the model confidently cited outdated API versions. RAG would have been simpler and more reliable for that use case, the knowledge was too dynamic for fine-tuning.
**Use RAG when:**
- Your knowledge changes frequently (documentation, product updates, news)
- You need to cite sources and show your work
- You're querying factual or domain-specific information
- You want explicit control over what the model can reference
**Use fine-tuning when:**
- You need a specific response format or output structure
- You're adjusting tone or communication style
- Task-specific patterns need to be baked in at training time
- You have thousands of high-quality labeled examples
Most production systems end up using both: fine-tuned models for consistent format and tone, RAG for factual grounding.
## How Do You Get Started with RAG?
Here's a working minimal implementation with ChromaDB and Claude:
```python
import chromadb
import anthropic
# 1. Set up vector store and add documents
client = chromadb.Client()
collection = client.create_collection("docs")
collection.add(
documents=[
"Users authenticate via JWT tokens stored in httpOnly cookies.",
"Database connection uses PostgreSQL on port 5432.",
"API rate limit is 100 requests per minute per IP."
],
ids=["auth", "db", "rate-limit"]
)
# 2. Retrieve relevant context
def retrieve(query: str, n: int = 3) -> list[str]:
results = collection.query(query_texts=[query], n_results=n)
return results["documents"][0]
# 3. Generate with context
anthropic_client = anthropic.Anthropic()
def rag_query(question: str) -> str:
context = retrieve(question)
context_str = "\n".join(f"- {doc}" for doc in context)
response = anthropic_client.messages.create(
model="claude-opus-4-8",
max_tokens=1024,
messages=[{
"role": "user",
"content": f"Use this context to answer the question.\n\nContext:\n{context_str}\n\nQuestion: {question}"
}]
)
return response.content[0].text
print(rag_query("How do users log in?"))
# → "Users authenticate via JWT tokens stored in httpOnly cookies."
```
ChromaDB handles embedding automatically using its default model. For production, swap in a dedicated embedding service and a persistent vector database. The key is step 3, context gets prepended to the prompt before the LLM generates. That's it. That's RAG.
## Common RAG Mistakes
I've made most of these. Some took months to diagnose.
### Chunk size too large
Retrieving entire documents when only one paragraph is relevant. LLMs have context windows, stuffing in irrelevant text wastes tokens and dilutes useful content. Worse, the LLM might confabulate based on unrelated content that got retrieved alongside the correct answer.
**Fix:** Chunk documents into 256–512 token segments with 50-token overlap to preserve context at boundaries.
### Chunk size too small
Splitting so aggressively that context is lost. A 50-word chunk might contain the answer but not the surrounding context that makes it meaningful. "Use bcrypt" without "when storing passwords" misses the point.
**Fix:** Experiment per content type. For prose, 512 tokens with overlap. For code, split by function or class boundary.
### Skipping reranking
Taking top-k vector search results at face value. Vector similarity finds semantically related text but not always the most *relevant* text. A passage about "fast running" can score well for "quick deployment" when you wanted DevOps documentation.
**Fix:** Add a cross-encoder reranker as a second pass. It re-scores results by relevance to the specific query, not just semantic proximity. Slower but significantly more accurate for precision-sensitive use cases.
### Missing metadata filtering
Treating all documents equally. If you have docs for v1 and v2 of an API, you want v2 docs for v2 questions. Vector similarity doesn't understand versioning or recency.
**Fix:** Store metadata (version, date, author, section) alongside embeddings. Filter before or after retrieval based on query context or user-supplied parameters.
### No evaluation
Building RAG and measuring success by feel. "It seems better" is not a metric.
**Fix:** Create a test set of 20–50 question-answer pairs. Measure retrieval precision (did the right document get retrieved?) and answer faithfulness (did the LLM actually use the retrieved content?). Tools like [RAGAS](https://docs.ragas.io/) automate this evaluation loop.
## Production RAG Considerations
The working example above gets you a prototype. Production systems need a few more pieces.
**Chunking strategy matters more than the database.** The most common reason RAG systems underperform isn't the LLM or the vector store, it's that chunks are either too large (stuffing in irrelevant context) or too small (losing surrounding meaning). Start with 512-token chunks with 50-token overlap and test against your actual question set before committing to a strategy.
**Evaluate retrieval separately from generation.** Two distinct failure modes exist: the right document wasn't retrieved, or the right document was retrieved but the LLM generated a bad answer anyway. Evaluate each independently. If retrieval precision is low (wrong documents retrieved), improve embedding quality or add metadata filtering. If answer faithfulness is low (documents retrieved but ignored in the response), improve the system prompt to be more directive about using context.
**Monitor costs in staging.** Embedding thousands of documents at 10,000 tokens each adds up. Audit your embedding cost before scaling to production. For most developer knowledge bases, the one-time embedding cost stays under $5, but knowing that number before you scale matters. OpenAI's `text-embedding-3-small` costs $0.02 per million tokens; for a 500-document knowledge base, that's effectively free at initialization.
---
Since I no longer need to second-guess every AI response, I can focus on what I actually want to build. I like to see it as a comparative advantage--understanding RAG means building more reliable AI applications.
---
## Related Reading
This is part of the [Complete Claude Code Guide](/blog/claude-code-complete-guide) and the [tools and resources collection](/products). Continue with:
- [Quality Control System](/blog/how-i-build-with-claude-code) - Two-gate enforcement for AI code generation
- [Context Management](/blog/claude-context-management-dev-docs) - The dev docs workflow is essentially manual RAG
- [Self-Improving RAG for Claude Code](/blog/self-improving-rag-claude-code) - Building a system that learns from your sessions
--- END POST ---
================================================================================
POST: Human-in-the-Loop AI: Why It Beats Full Automation for Security Tools
================================================================================
URL: https://chudi.dev/blog/why-human-in-the-loop-beats-full-automation
Date: 2026-01-17T00:00:00.000Z
Tags: ai, automation, philosophy, security, bug-bounty
Pillar: philosophy
Reading Time: 10 min
Word Count: 1806
TL;DR: I could have built BugBountyBot to submit findings automatically. I didn't. Not because I couldn't, because full automation in security is a reputation time bomb. One bad submission can undo months of credibility. Human-in-the-loop isn't a compromise. It's the architecture that lets you scale without catastrophic failure modes.
Key Takeaways:
- Full automation in security tools shifts liability unpredictably, you're responsible for what your bot submits
- False positives damage reputation faster than true positives build it
- Platform ToS (HackerOne, Intigriti, Bugcrowd) explicitly require human oversight for automated tools
- Human-in-the-loop is a feature, not a limitation, it's where judgment gets applied
- The goal isn't maximum automation, it's maximum valuable output with acceptable risk
--- CONTENT ---
Human-in-the-loop beats full automation in bug bounty because false positives damage reputation faster than true positives build it. After eight months running BugBountyBot with a human approval step, the accepted-to-submitted ratio stayed above 90% with zero bans and zero private program revocations. The review overhead is four to eight hours per month. The alternative has no ceiling.
I could have built BugBountyBot to submit findings automatically. The technical barrier isn't high, an API call to HackerOne after validation passes.
I didn't build it that way. Here's why.
## Why Is Full Automation Tempting in Security Research?
Full automation promises speed, scale, and the appeal of a system that hunts bugs while you sleep. Every conversation about BugBountyBot arrives at the same question: why not just auto-submit? The answer is that bug bounty rewards precision, not recall, and automated systems optimizing for recall produce false positive rates that destroy the reputation they were supposed to scale.
## The Temptation of Full Automation
Full automation is seductive:
- **Speed**: Submit findings as fast as you find them
- **Scale**: Hunt 24/7 without human bottlenecks
- **Ego**: "I built a system that hunts bugs while I sleep"
Every conversation about BugBountyBot eventually hits this question: "Why not just auto-submit?"
## The False Positive Problem
In security research, reputation is everything. A single bad submission can:
- Get your report closed as "Not Applicable"
- Add a negative signal to your profile
- Cost you access to private programs
- Waste triager time (they remember)
**The math is brutal**: one false positive can undo five true positives in terms of reputation impact.
Automated systems optimize for recall, finding everything possible. But bug bounty rewards precision. A 90% precision rate sounds good until you realize that means 1 in 10 submissions is garbage.
A researcher I know ran automated submissions for a month. Their valid-to-invalid ratio dropped to 60%. Three private programs revoked access. It took six months of manual, high-quality reports to recover.
### The Real Cost of a Reputation Hit
Let's put numbers to it.
A mid-level bug bounty hunter submitting 20 reports per month with 90% validity earns consistent program access and occasional bounties. Now automate without human review and drop to 70% validity:
- Month 1: 6 invalid reports. Triagers notice. No visible consequence yet.
- Month 2: Another 6. Two programs flag your profile internally.
- Month 3: One program marks you as low-priority. Your valid reports now get slower triage.
- Month 4: A private program revokes your invitation.
You just lost access to a private program that might have had $5,000 bounties. How long to earn that back? Six months of clean reports at minimum, and some programs never re-invite once access is revoked.
The math is simple: **one automated false-positive spiral costs more in lost access than the time you saved automating.**
## What Do Bug Bounty Platforms Actually Require from Automated Tools?
HackerOne explicitly prohibits fully automated submission systems and requires human review before any submission. Intigriti holds researchers responsible for the quality of all submissions, including those assisted by automated tools. Bugcrowd warns that automated scanning causing excessive false positives may result in account suspension. Full automation is not a gray area, it violates platform terms of service.
## Platform Requirements
This isn't just my opinion, platforms explicitly require human oversight.
From HackerOne's Automation Policy:
> "Automated tools must have human review before submission. Fully automated submission systems are prohibited."
From Intigriti's Terms:
> "Researchers are responsible for the quality and accuracy of all submissions, including those assisted by automated tools."
From Bugcrowd:
> "Automated scanning that results in excessive false positives may result in account suspension."
Build full automation, and you're violating ToS. Not a gray area.
## The Liability Question
When your bot submits a finding, who's responsible?
- If it's valid: You get credit
- If it's invalid: You get blamed
- If it causes harm: You're liable
There's no "my AI did it" defense. The liability is asymmetric, downside is yours, and "scale" just multiplies it.
Compare this to human-in-the-loop:
- You review each finding before submission
- You apply judgment about timing and context
- You own the decision, not just the consequence
## What Humans Do Better
Automation excels at:
- Pattern matching at scale
- Consistent testing methodology
- 24/7 availability
- Memory across sessions
Humans excel at:
- **Context understanding** - Is this behavior intentional?
- **Impact assessment** - Is this actually a security issue?
- **Communication** - Can I explain this clearly?
- **Timing judgment** - Is now the right time to submit?
The optimal system uses AI for the first set and humans for the second.
## How Is the Human-in-the-Loop Architecture Structured?
BugBountyBot runs three agents, Recon, Testing, and Validator, automatically. Findings above a 0.85 confidence threshold queue for human review with full evidence: the request/response pair, a confidence breakdown, a reproducible proof-of-concept, and a CVSS severity assessment. The human approves, rejects, or edits before the Reporter agent submits. AI handles the 80% grind; humans handle the 20% requiring judgment.
## The Human-in-the-Loop Architecture
BugBountyBot's design:
```
[Recon Agent] → [Testing Agent] → [Validator Agent]
↓
[Confidence ≥ 0.85?]
↓ ↓
Yes No
↓ ↓
[Queue for Review] [Log & Learn]
↓
[Human Review]
↓
[Approve/Reject/Edit]
↓
[Reporter Agent]
```
The human checkpoint is after validation but before submission. You're not reviewing raw signals, you're reviewing high-confidence findings with full evidence.
This is the leverage point: AI handles the 80% grind, humans handle the 20% that requires judgment. The full architecture behind this system is detailed in the [bug bounty automation architecture post](/blog/bug-bounty-automation).
## The Numbers That Matter
| Metric | Full Automation | Human-in-the-Loop |
|--------|-----------------|-------------------|
| Submissions/day | High | Medium |
| Precision | ~70% | ~95% |
| Reputation trend | Declining | Stable/Growing |
| Platform standing | At risk | Solid |
| Sustainable? | No | Yes |
Optimizing for submissions per day is the wrong metric. Optimize for accepted findings per month, reputation over time, and access to better programs.
## When Full Automation Makes Sense
There are legitimate use cases:
- **Internal security testing** - Your own infrastructure, no reputation at stake
- **Private engagements** - Client agreed to automated testing
- **Research environments** - Sandboxed, no real submissions
But for public bug bounty programs? Human-in-the-loop is the only sustainable architecture. The ethical and compliance dimensions of this are explored in [the human-in-the-loop bug bounty ethics post](/blog/bug-bounty-automation).
## How to Design for Human-in-the-Loop
If you're building automation with a human checkpoint, the design matters. A badly designed HITL system creates the worst of both worlds: slow automation with human bottlenecks that still produce false positives.
### Present findings with evidence, not signals
The human shouldn't have to re-investigate. Every item in the review queue should arrive with:
- The full request/response pair showing the vulnerability
- A confidence score with the breakdown (what raised it, what nearly filtered it out)
- A reproducible PoC, one command the reviewer can run to verify
- Severity assessment with CVSS rationale
If a reviewer has to go digging, the handoff is broken.
### Batch similar findings together
Reviewing ten IDOR findings one by one is exhausting and inconsistent. Batch them: show all IDOR findings from the same program in one session. Pattern recognition kicks in. The reviewer can apply consistent judgment across similar cases, and they'll notice if finding #7 looks different from the others.
### Set a minimum confidence floor, not just a threshold
Don't just block low-confidence findings, discard them at the source. If something scores below 0.40, logging it and moving on is correct. A review queue full of 0.41-confidence findings is worse than a queue with nothing: it trains reviewers to rubber-stamp.
The [NIST AI Risk Management Framework](https://www.nist.gov/publications/artificial-intelligence-risk-management-framework-ai-rmf-10) calls this "human oversight commensurate with risk", the human role should be proportional to the stakes, not a checkbox.
### Keep the review cycle short
If findings sit in queue for days, context gets lost. A reviewer looking at a finding two weeks old has to re-read everything from scratch. Set a target: findings should be reviewed within 24–48 hours of queuing. If volume exceeds review capacity, slow down the automation, not the other way around.
## What Does Eight Months of Data Show About Human-in-the-Loop?
After eight months running BugBountyBot with human-in-the-loop, the accepted-to-submitted ratio stayed above 90% consistently. Zero bans. Zero private program revocations. The review overhead runs four to eight hours per month. The alternative, handling reputation damage, disputing invalid submissions, and rebuilding program trust, has no ceiling and no predictable timeline.
## The Long-Term Evidence
I've now run BugBountyBot with human-in-the-loop for eight months. The data makes the case more clearly than any argument.
**Month 1-2 (calibration)**: The system queued 34 findings for review. I approved 18, rejected 16. Twelve of the approved ones were accepted by programs. Six were marked informational, valid but not bounty-eligible. Zero false positives submitted. Nothing I submitted was wrong, just not always in-scope.
**Month 3-4 (dialing in)**: The system queued 28 findings. I approved 22. Twenty were accepted or rewarded. Two were informational. Still no false positive submissions. The RAG database had learned enough false positive signatures that it filtered garbage before it reached the review queue.
**Month 5-8 (steady state)**: Quarterly average of 25 queued, 22-24 approved, 20-22 accepted. My effective submission rate (accepted / submitted) stayed above 90% consistently.
Compare this to the researcher who ran full automation: 60% valid rate by month three, three private program revocations by month four.
The efficiency difference is smaller than it looks. I spend roughly 4-8 hours per month reviewing findings. Each review takes 10-20 minutes including reproducing the PoC. The alternative, handling reputation damage, disputing invalid submissions, rebuilding program trust, has no ceiling and no timeline.
Eight months of data. Zero bans. Zero private program revocations. Consistent accepted-to-submitted ratio above 90%.
That's the case for human-in-the-loop. Not philosophy, evidence.
## The Deeper Point
The goal isn't maximum automation. The goal is maximum valuable output with acceptable risk.
Human-in-the-loop is how you get there. It's not a compromise, it's the architecture that lets you scale without catastrophic failure modes.
**A checklist for evaluating any automation decision:**
- Can the automated component fail silently? (If yes: add logging + human audit)
- Does failure at scale damage relationships? (If yes: add human gate)
- Is the judgment call context-dependent? (If yes: keep a human in the loop)
- Can you reverse a bad automated decision? (If no: add human gate)
Four yeses means full automation. Mixed answers means HITL. All yeses means the human checkpoint is the only path.
Build for sustainability. Your future self will thank you.
The researchers running full automation are chasing a metric, submissions per day, that doesn't correspond to the outcome that actually matters: bounties earned and program access maintained over months and years. Human-in-the-loop is slower on the metric that sounds impressive in a demo and faster on the metric that pays reliably.
---
**Related**: [Building a Semi-Autonomous Bug Bounty System](/blog/bug-bounty-automation) | [Portfolio: BugBountyBot](/portfolio/bugbountybot)
--- END POST ---
` hierarchy
- **No text in images:** AI can't read screenshots. Use actual text + `
`
- **Lists > paragraphs:** Bullet points are easier to extract than walls of text
- **Scannable structure:** Headers every 2-3 paragraphs
A 2,000-word article with 3 headers is harder to cite than a 2,000-word article with 15 headers. AI needs to find the specific section that answers the user's question.
### 5. Metadata Completeness
Even though AI ignores ``, it checks:
- Canonical URL (to avoid duplicate content)
- Open Graph image (for preview context)
- Article `datePublished` (to know how old your content is)
Stale content (3+ years old) gets deprioritized. Fresh content gets cited more often.
### 6. Answer-Ready Format
The best AEO content directly answers common questions:
- "What is X?" → Definition box at the top
- "How do I X?" → Step-by-step with numbered lists
- "Why does X matter?" → Clear benefits, quantified where possible
Content written as "walls of paragraphs" is less likely to be extracted. Content structured as "question → answer → proof" is gold. I built my [autonomous blog agent](/blog/openclaw-autonomous-blog-agent) around this principle. Every draft follows the question-answer-proof structure automatically.
---
## AEO vs SEO vs GEO: Three Optimization Disciplines
The search landscape now has three distinct optimization disciplines. SEO targets traditional search rankings, AEO targets AI answer citations, and GEO (Generative Engine Optimization) targets how generative AI models represent your brand and content in synthesized responses. They overlap but reward different signals.
| Factor | SEO (Google) | AEO (AI Engines) | GEO (Generative AI) |
|--------|-------------|-----------------|---------------------|
| Goal | Rank in search results | Get cited in AI answers | Shape AI's representation of your brand |
| Crawling | robots.txt | robots.txt + llms.txt | robots.txt + llms.txt + ai.txt |
| Ranking | Backlinks + engagement | Content accuracy + structure | Entity clarity + topical authority |
| Signal count | 200+ factors | ~6 critical factors | Emerging, entity-centric |
| Meta descriptions | Shown to users | Ignored | Ignored |
| Title tags | Shown to users | Used for context | Used for entity recognition |
| Content format | Long-form preferred | Any length, needs structure | Definition-dense, claim-backed |
| Freshness | Can rank for years | Deprioritized after ~10 months | Training data snapshots, slower refresh |
| Citations | Implied (link juice) | Explicit (source linked in answer) | Implicit (model "knows" you) |
| Key differentiator | Popularity | Extractability | Entity recognition |
### When to prioritize which
- **SEO first** if your revenue depends on organic click-through traffic today.
- **AEO first** if you produce reference content (definitions, tutorials, comparisons) that AI engines synthesize into answers.
- **GEO first** if brand perception matters more than individual page traffic. You want AI to describe your company correctly when users ask about your category.
Most sites benefit from all three, and the technical foundations overlap heavily. The good news: structured data, semantic HTML, clear headings, and answer-first formatting improve all three simultaneously. The differences are in emphasis, not in contradiction.
**The opportunity:** A well-structured blog post with schema and semantic HTML will rank on Google, appear in AI answers, *and* inform how generative models represent your expertise. The cost of doing all three is marginally higher than doing one.
---
## How Do You Start Optimizing for Answer Engines?
Start by confirming AI crawlers can access your site via robots.txt, then create an llms.txt file at your site root. Audit your top five pages to add schema markup, restructure them with more headers, and rewrite openings to directly answer the question in the title. Those four actions deliver the most AEO impact.
## How to Start with AEO
Four actions deliver 80% of your AEO impact: unblock AI crawlers in robots.txt, create a two-paragraph llms.txt at your site root, add FAQPage schema to your three best posts, and rewrite each post's opening paragraph to directly answer the title question. You can finish all four in under an hour.
### Step 1: Check if AI Can Find You
```bash
# Can Perplexity, Claude, etc. access your site?
curl -I yoursite.com/robots.txt
# Look for GPTBot, ClaudeBot, PerplexityBot allow rules
```
### Step 2: Create `/llms.txt`
Add this file to your site root:
```
# Content policy for LLMs
All content available for training and search.
Please attribute as: [Article] by [Author] (yoursite.com)
Sitemap: https://yoursite.com/sitemap.xml
RSS: https://yoursite.com/rss.xml
```
### Step 3: Audit Your Best Content
Pick your 5 best-performing pages and:
- Add schema (BlogPosting, HowTo, FAQ)
- Restructure with more headers
- Move key info to the top
- Add a definition box for the main question
### Step 4: Monitor in Perplexity
Search your main topics in Perplexity. Are you being cited? If not, your content isn't being discovered.
---
## Platform-by-Platform AEO Strategy
Each AI engine has distinct citation behavior and source preferences. Perplexity favors Reddit and reference-style content; ChatGPT is highly selective and freshness-sensitive; Google AI Overview mirrors traditional search rankings; Claude rewards structured technical writing. A platform-specific approach compounds your overall citation rate significantly beyond what generic AEO delivers.
### Perplexity
Perplexity cites the most sources per answer (~21.9) and favors Reddit heavily (46.7% of top sources, per Profound's 2025 citation-pattern study). To optimize for Perplexity:
- **Participate in Reddit discussions** about your expertise topics. Perplexity's retrieval pipeline weights Reddit as a high-trust source for niche questions. Genuine contributions with links to your detailed writeups outperform any on-site optimization alone.
- **Structure content as reference material.** Perplexity favors pages that read like authoritative references: tables, definitions, numbered lists, and comparative data. Pure opinion pieces get cited less.
- **Keep content updated.** Perplexity's real-time retrieval means recently updated pages get priority. Pages with `dateModified` schema that reflect genuine content updates outperform stale pages.
- **Include original data.** Benchmark results, survey findings, and original research get cited at higher rates because they provide information Perplexity can't synthesize from other sources.
### ChatGPT (SearchGPT / Browse)
ChatGPT is the most selective citer (~7.9 sources per answer) and leans heavily on Wikipedia (4.8% of all citations, per Qwairy's Q3 2025 provider study). To optimize:
- **Answer the exact question in paragraph one.** ChatGPT extracts more aggressively than other platforms. If your answer is in paragraph four, it may not get extracted at all.
- **Target Wikipedia-adjacent queries.** ChatGPT cites Wikipedia for broad topics but turns to specialized sources for niche questions. The sweet spot is questions too specific for Wikipedia but too authoritative for forums.
- **Prioritize freshness.** AI-cited pages skew markedly fresher than traditional search results (Ahrefs measured AI-cited URLs at roughly 26% fresher than same-query SERP pages). A page that hasn't been updated in a year is competing at a measurable disadvantage.
- **Use canonical URLs consistently.** ChatGPT deduplicates aggressively. If your content appears at multiple URLs (www vs non-www, trailing slashes, paginated versions), citations may be split or lost.
### Google AI Overview
Google AI Overview draws 76% of its citations from the traditional top 10 results. This makes it the most SEO-correlated AI citation source.
- **Rank in Google first.** Unlike other AI engines, Google AI Overview primarily cites pages that already rank well in traditional search. AEO-only optimization without SEO foundations won't work here.
- **Add FAQPage schema.** Google AI Overview preferentially extracts from pages with structured FAQ markup. The question-answer format maps directly to how Overview constructs its responses.
- **Target featured snippet queries.** Queries that currently trigger featured snippets are the most likely to trigger AI Overview. If you can win the snippet, you're positioned for the Overview citation.
### Claude
Claude doesn't have a live search product with citations in the same way, but its training data preferences and retrieval behaviors are worth understanding:
- **Maintain an llms.txt file.** Claude's parent company (Anthropic) respects llms.txt as a content policy signal. Having one is a positive signal for ClaudeBot crawling.
- **Provide structured, well-organized technical content.** Claude's training pipeline favors content with clear hierarchical structure, code examples with context, and explicit reasoning chains.
- **Avoid content that reads like AI-generated filler.** Claude's quality filters are sensitive to low-information-density content. Dense, opinionated, experience-backed writing gets weighted higher than generic explainers.
---
## Common AEO Mistakes
The six mistakes that most often keep well-written content invisible to AI engines are: blocked crawlers, buried answers, image-only key information, assuming Google rank equals AI visibility, bumping date metadata without changing content, and skipping FAQ schema. Each is fixable in under an hour once you know to look for it.
### Mistake 1: Blocking AI crawlers unintentionally
The most common AEO failure is a robots.txt that blocks crawlers the site owner doesn't know about. A blanket `Disallow: /` for unlisted user agents, or a hosting platform that adds `X-Robots-Tag: noai` by default, silently makes your entire site invisible. Run `curl -I yoursite.com/robots.txt` and check what it actually says. Don't assume.
### Mistake 2: Burying the answer
SEO rewards content that keeps users scrolling: long intros, context-setting, narrative buildup. AEO rewards the opposite. If your page title is "What is Answer Engine Optimization?" and the definition doesn't appear until paragraph three, AI engines may extract from a competitor who puts it in paragraph one. Move the answer up. Context can follow.
### Mistake 3: Using images instead of text for key information
Infographics, diagrams, and screenshots are invisible to AI extraction. If your comparison table is an image, AI engines can't read it. If your step-by-step tutorial is a screenshot of a terminal, AI can't extract the commands. Use real HTML tables, real code blocks, and real text. Add `alt` attributes to images, but don't rely on `alt` for primary content.
### Mistake 4: Assuming Google ranking equals AI visibility
This is the most expensive mistake. A page ranking #1 on Google may not be cited by any AI engine. Google and AI engines evaluate different signals: Google weighs backlinks and click-through rate; AI engines weigh extractability and structural clarity. The only AI engine with strong Google correlation is Google AI Overview (76% overlap). For Perplexity, ChatGPT, and Claude, your Google rank is largely irrelevant.
### Mistake 5: Updating `dateModified` without changing content
Pages with `dateModified` schema get 1.8x more AI citations, but only if the content actually changed. Bumping the date on unchanged content is detectable (AI engines can diff cached versions) and triggers a trust penalty. When you update `dateModified`, make substantive changes: new data, expanded sections, corrected claims, or added examples.
### Mistake 6: Ignoring FAQ schema
FAQPage schema is the single highest-ROI structured data for AEO. It maps directly to how AI engines construct answers: question in, answer out. A page with five well-structured FAQ entries gives AI engines five separate extraction opportunities. A page without it gives AI engines one: the entire article body, which they then have to parse themselves with lower accuracy.
---
## How Do You Measure AEO Performance Without a Dashboard?
Measure AEO manually each month by querying ChatGPT, Perplexity, Claude, and Gemini with the exact questions your content answers, then checking whether you are cited. Track AI referral traffic in analytics using domain segments, and monitor Google's AI Overview for your target queries to identify citation gaps.
## Measuring AEO Progress
Track AEO performance with four monthly checks: a manual citation audit across ChatGPT, Perplexity, Claude, and Gemini; AI referral traffic segments in analytics; an automated infrastructure scan via citability.dev; and a Google AI Overview review for your target queries. No single dashboard does this yet.
The hardest part of AEO is knowing if it's working. Traditional SEO has rankings and impressions in Search Console. AEO doesn't have a dashboard yet.
### Manual citation audit (monthly)
Open ChatGPT, Perplexity, Claude, and Gemini. Ask the exact questions your content answers:
- "What is AEO?"
- "How do I optimize for Perplexity?"
- "What is llms.txt?"
Are you cited? If not, who is? Read the content that does get cited and compare it to yours. The differences are usually structural: their definition is in the first paragraph, yours is in paragraph four. Their page has 12 question-format headers, yours has three. These gaps are fixable.
### Want to See Which URLs ChatGPT Cites From Your Site?
The manual audit above is free but slow, and it only samples a few questions. That exact problem is why I built [citability.dev](https://citability.dev/?utm_source=chudidev&utm_medium=referral&utm_campaign=aeo-answer-engine-optimization-explained): the paid citation audit asks ChatGPT and Perplexity real questions in your topic and records which URLs from your site they actually cite, with the raw AI responses kept as receipts. Nothing is scored that wasn't tested. Start with the free [30-second infrastructure scan](https://citability.dev/scan?utm_source=chudidev&utm_medium=referral&utm_campaign=aeo-answer-engine-optimization-explained) to clear crawl-access and structure blockers first, then run the citation test for your URL-level results.
### AI referral traffic in analytics
Create a segment for sessions from AI engine domains: `chatgpt.com`, `perplexity.ai`, `claude.ai`, `gemini.google.com`, `copilot.microsoft.com`. Track this monthly. Growth here is a leading indicator of citation growth. Direct AI traffic often comes before organic traffic from AI-influenced searches.
### Automated infrastructure auditing
Manual citation checks tell you the outcome but not the cause. Infrastructure audits identify the specific technical gaps preventing citations. Tools like [citability.dev](https://citability.dev/scan?utm_source=chudidev&utm_medium=referral&utm_campaign=aeo-answer-engine-optimization-explained) run 10 automated checks against your site: robots.txt permissions, sitemap completeness, answer-first content structure, content freshness via dateModified schema, JSON-LD coverage, meta descriptions, canonical URLs, HTTPS, heading hierarchy, and social sharing tags. The scan takes under 30 seconds and shows exactly which signals pass and which need fixing.
### Google AI Overview tracking
Search your target queries in Chrome incognito. Does Google's AI Overview cite you? If it does, you're in the 2–7% of pages that get sourced for that query. If it doesn't but competitors are cited, run their pages through the AEO checklist. FAQPage schema and answer-first formatting are usually the gap.
### The minimum viable AEO setup
If you want to start today with 30 minutes of work:
1. Add `User-agent: GPTBot / Allow: /` and similar for ClaudeBot, PerplexityBot to your robots.txt
2. Create a 200-word `llms.txt` at your root with your sitemap URL and preferred attribution format
3. Add FAQPage schema to your three best posts
4. Rewrite the opening paragraph of each post to directly answer the question in the title
That's it. Nothing else in the AEO checklist will have as much impact as those four actions. Do them before optimizing for any specific engine.
## Deciding whether to buy help
Everything above is the manual version. If you are a B2B SaaS team deciding whether to pay someone, the commercial questions have their own pages: [what an AI visibility audit should measure](/blog/ai-visibility-audit-b2b-saas) before you spend, [how to choose an AI SEO agency](/blog/how-to-choose-best-ai-seo-agency-b2b-saas) and [what a generative engine optimization agency should actually charge for](/blog/generative-engine-optimization-agency-what-you-pay-for) when comparing proposals, [what changes for an existing SaaS SEO budget](/blog/seo-for-saas-ai-search-era), and [whether you need a B2B SEO agency or an AI search specialist](/blog/b2b-seo-agency-vs-ai-search-specialist) at all.
## Advanced AEO: Beyond the 6 Factors
After the six core factors are in place, three techniques compound your AI visibility further: publishing an ai.txt policy file, implementing WebMCP so AI agents can query your site programmatically, and stacking entity mentions across Wikidata, GitHub, LinkedIn, and Crunchbase. These are differentiation plays, not baseline requirements.
### ai.txt: Declaring your AI interaction policy
While `llms.txt` tells AI crawlers what content to index and how to cite it, `ai.txt` goes further. It declares your site's full AI interaction policy including tool use, embedding permissions, and content licensing terms. Place it at `yoursite.com/ai.txt` alongside your `robots.txt` and `llms.txt`.
An `ai.txt` file signals to AI systems that your site is intentionally designed for AI interaction, not just passively crawlable. This is a differentiator: most sites are accidentally AI-visible (or accidentally invisible). A site with `ai.txt` is declaring intent, which AI systems can use as a trust signal.
### WebMCP: Making your site callable by AI agents
AEO gets your content cited in AI answers. WebMCP gets your content *used* by AI agents. WebMCP is a browser-side protocol that registers tools AI agents can call (search your site, query your data, interact with your product) directly from the browser context.
This is the frontier of AI-visible web architecture: a site that isn't just readable by AI, but usable by it. When an AI agent needs to find information in your domain, WebMCP lets it query your site programmatically rather than scraping HTML.
### Entity stacking: Building your knowledge graph footprint
AI engines identify entities (people, companies, products) by cross-referencing structured data across the web. The more high-authority platforms that contain consistent information about your entity, the more confidently AI engines will cite you.
Key platforms for entity stacking:
- **Wikidata:** Add a structured entry for yourself or your company. Wikidata is a primary knowledge source for most AI systems.
- **Crunchbase:** For companies and products. Crunchbase data feeds into multiple AI training pipelines.
- **GitHub:** Active repositories with clear README files and consistent author attribution.
- **LinkedIn:** Detailed profile matching your site's author schema exactly (same name, same title, same description).
- **Product Hunt:** For SaaS products. Product Hunt pages are high-authority and frequently cited by AI when discussing tools.
The key is consistency: the same name, same description, same URL across all platforms. Inconsistent entity data confuses AI systems and splits your citation authority across multiple "versions" of you.
### Topic hubs: Building topical authority for AI
AI engines evaluate topical authority differently than Google. Google uses backlinks as authority proxies. AI engines use content depth and internal linking density. A site with one article about AEO is a mention. A site with ten interconnected articles about AEO (definitions, tutorials, case studies, comparisons, tooling) is a topical authority.
Build topic hubs by:
1. **Writing a pillar article** (like this one) that defines the topic comprehensively.
2. **Creating supporting articles** that go deep on subtopics: each of the 6 factors, platform-specific guides, case studies, tool comparisons.
3. **Internal linking densely.** Every supporting article links to the pillar. The pillar links to every supporting article. AI engines follow these internal link graphs to gauge content depth.
4. **Using consistent terminology.** If your pillar calls it "Answer Engine Optimization," every supporting article should use the same phrase, not alternate between "AEO," "AI SEO," and "answer engine marketing."
---
## The Future is Plural Search
Over 30% of searchers now use AI answer engines for complex queries, and that share is growing monthly. AEO is not a replacement for SEO. It is a second optimization layer for a second type of search engine, one that extracts passages directly rather than ranking pages for users to click.
Google won't be the only search engine anymore. By 2026, over 30% of searchers use answer engines for complex queries. You need to be visible in *all* of them.
AEO isn't replacing SEO. It's extending your reach to a new search engine that's growing fast and underserved.
The technical foundation is the same as good SEO: well-structured, authoritative content with clear headings and direct answers. What changes is the mental model. SEO rewards findability: rank high enough and users click through. AEO rewards extractability: your H2 sections get lifted verbatim into AI responses. A page that ranks #3 on Google but buries its main answer in paragraph five won't get cited by AI even if Google loves it.
Write for systems extracting specific passages, not just readers scanning for reasons to click. Each H2 should be a complete, self-contained answer to the question it poses. Enough context to stand alone if extracted.
The easiest time to optimize for AEO was 2024. The second easiest time is today.
The six factors above are the whole method, and they are yours to run. If you would rather have the diagnosis handed to you, page by page, with the fixes already ordered, that is [the AEO audit I run at a fixed price](/services).
**Next:** Check out the [optimization checklist for AI search](/blog/how-to-optimize-for-perplexity-chatgpt-ai-search).
**See also:** [Why Domain Authority Is Irrelevant for AI Search (And What to Build Instead)](/blog/domain-authority-irrelevant-ai-search) and [How to Structure Content So AI Actually Cites Your URL](/blog/how-to-optimize-for-perplexity-chatgpt-ai-search)
--- END POST ---
================================================================================
POST: How to Test AI-Generated Code Before Shipping: 57 Bugs Caught
================================================================================
URL: https://chudi.dev/blog/ai-code-verification-evidence-based
Date: 2026-01-17T00:00:00.000Z
Tags: claude-code, ai, quality, verification, debugging
Pillar: ai-building
Reading Time: 9 min
Word Count: 1764
TL;DR: 'Should work.' The AI said it. I believed it. Six hours later, I was still debugging a fundamental error from line one. I trust AI completely. That's why I verify everything. The paradox makes sense once you've been burned enough. Forced evaluation mode achieves 84% compliance by requiring actual evidence before marking done.
Key Takeaways:
- Red flag phrases ('should work', 'probably fine', 'I'm confident') indicate confidence without evidence
- Three psychological traps: authority transfer, completion illusion, and optimism bias
- Forced evaluation protocol: evaluate each skill → activate every YES → then implement (84% compliance)
- Replace confidence claims with facts: 'Build completed: exit code 0', 'Tests passing: 47/47'
- Add verification hooks that reject red flag phrases and require evidence before task completion
--- CONTENT ---
"Should work." Six hours later, I was still debugging a fundamental error that had existed from line one. If your AI development workflow verification stops at a confident sentence from the model, that six hours is coming for you too, and it usually lands the week you can least afford it.
AI code verification means replacing model confidence with build output, test results, and concrete evidence before any task is treated as complete. That shift matters because AI-assisted development fails in predictable ways when proof is optional, not random ones. It is the same discipline behind my [Claude Code complete guide](/blog/claude-code-complete-guide), the implementation checks in [WebMCP for SvelteKit](/blog/webmcp-sveltekit-implementation), and the adversarial validation loop from [bug bounty false-positive reduction](/blog/bug-bounty-automation).
Evidence-based completion for AI code means blocking confidence phrases and requiring proof before any task is marked done. Not "should work"--actual build output. Not "looks good"--actual test results. The psychology is simple: confidence without evidence is gambling. Forced evaluation achieves 84% compliance because it makes evidence the only path forward. [Research on LLM reliability](https://arxiv.org/abs/2402.01680) confirms that AI-generated outputs require external verification to catch hallucinations and errors that models present with high confidence.
## Why Do We Skip Verification?
You skip verification because AI-generated code looks plausible and the model sounds confident, which triggers authority transfer, you treat the AI's certainty as evidence of correctness. Completion illusion makes the task feel done. Optimism bias means you want it to work. These three forces combine to make verification feel like unnecessary extra work.
The pattern is universal. You describe what you want. The AI generates code. It looks reasonable. You paste it in.
That moment of hesitation--the one where you could run the build, could write a test, could verify the output--gets skipped. The code looks right. The AI sounds confident. What could go wrong?
That specific shame of shipping broken code--the kind where you have to message the team "actually, there's an issue"--became my recurring experience.
I trust AI completely. That's why I verify everything.
The paradox makes sense once you've been burned enough times.
## What Makes "Should Work" Psychologically Dangerous?
"Should work" is dangerous because it substitutes confidence for evidence. The phrase triggers authority transfer, completion illusion, and optimism bias simultaneously, making you feel the task is finished when verification hasn't happened. You inherit the AI's certainty without inheriting any actual proof that the code functions correctly.
The phrase creates false confidence through three mechanisms:
### 1. Authority Transfer
The AI presents with confidence. We transfer that confidence to the code itself, as if certainty of delivery equals certainty of correctness.
### 2. Completion Illusion
"Should work" feels like a finished state. The task feels done. Moving to verification feels like extra work rather than essential work.
### 3. Optimism Bias
We want it to work. We've invested time. Verification risks discovering problems we'd rather not face.
I thought I was being thorough. Well, it's more like... I was being thorough at the wrong stage. Careful prompting, careless verification.
## What Phrases Trigger the Red Flag System?
The red flag system blocks phrases that express certainty without evidence: "Should work," "Probably fine," "I'm confident," "Looks good," "Seems correct," "That should do it," "We're good," "All set," and "It shouldn't cause issues." Each phrase indicates a completion claim unsupported by build output, test results, or any verifiable proof.
Here's the complete list that gets blocked:
Each of these phrases indicates a claim without evidence. They're not wrong to think--they're wrong to accept as completion.
## What Evidence Replaces Confidence Claims?
Specific, verifiable proof replaces confidence claims: build output showing exit code 0, test results listing pass counts like "47/47," screenshots at exact viewport widths, and Lighthouse scores with numeric values. These are facts, not feelings. Any completion claim must cite one of these evidence types before the task can be marked done.
The replacement is specific, verifiable proof:
### Build Evidence
```
Build completed successfully:
- Exit code: 0
- Duration: 9.51s
- Client bundle: 352KB
- No errors, 2 warnings (acceptable)
```
### Test Evidence
```
Tests passing: 47/47
- Unit tests: 32/32
- Integration tests: 15/15
- Coverage: 78%
```
### Visual Evidence
```
Screenshots captured:
- Mobile (375px): layout correct
- Tablet (768px): responsive breakpoint working
- Desktop (1440px): full layout verified
- Dark mode: all components themed
```
### Performance Evidence
```
Lighthouse scores:
- Performance: 94
- Accessibility: 98
- Best Practices: 100
- SEO: 100
Bundle size: 287KB (-3KB from previous)
```
That hollow confidence of claiming something works--replaced with facts that prove it.
## How Does Forced Evaluation Achieve 84% Compliance?
Forced evaluation achieves 84% compliance by requiring explicit commitment before implementation. You evaluate each skill as YES or NO with reasoning, activate every YES, then proceed. Writing "YES, need verification" creates accountability. Passive suggestions produced only 20% compliance because nothing required follow-through. The commitment mechanism is what converts intent into actual verification behavior.
Research on skill activation showed a stark difference, a pattern consistent with findings from the [NIST AI Risk Management Framework](https://www.nist.gov/publications/artificial-intelligence-risk-management-framework-ai-rmf-10) on the importance of structured validation in AI-assisted workflows:
- **Passive suggestions**: 20% actually followed
- **Forced evaluation**: 84% actually followed
The mechanism is a 3-step mandatory protocol:
### Step 1: EVALUATE
For each potentially relevant skill:
```
- master-debugging: YES - error pattern detected
- frontend-guidelines: NO - not UI work
- test-patterns: YES - need verification
```
### Step 2: ACTIVATE
For every YES answer:
```
Activating: master-debugging
Activating: test-patterns
```
### Step 3: IMPLEMENT
Only after evaluation and activation complete:
```
Proceeding with implementation...
```
The psychology works because evaluation creates commitment. Writing "YES - need verification" makes you accountable to the claim. Skipping feels like breaking a promise to yourself.
## What Are the 4 Pillars of Quality Gates?
The four pillars are State and Reactivity, Security and Validation, Integration Reality, and Failure Recovery. Every piece of verification maps to one of these categories. State checks confirm reactive patterns work. Security checks confirm inputs are sanitized. Integration checks confirm components are actually used. Failure checks confirm error boundaries and loading states exist.
Every verification maps to one of four pillars:
## How Does Self-Review Automation Work?
Self-review automation works by prompting the AI to critique its own output before marking anything complete. You ask it to review its architecture for issues, explain the end-to-end data flow, and predict how the solution could break in production. The AI is effective at finding problems in code, including its own, when explicitly asked.
The system includes prompts that make the AI review its own work:
### Primary Self-Review Prompts
1. "Review your own architecture for issues"
2. "Explain the end-to-end data flow"
3. "Predict how this could break in production"
### The Pattern
```
1. Generate solution
2. Self-review with prompts
3. Fix identified issues
4. Re-review
5. Only then mark complete
```
Self-review catches issues before they become bugs. The AI is good at finding problems in code--including its own code, when asked explicitly. [Anthropic's documentation](https://docs.anthropic.com) covers how to structure these review prompts for reliable results.
## What Happens When Verification Fails?
When verification fails, the system escalates through three levels. A soft block requests evidence when a red flag phrase appears. A hard block prevents completion when no evidence exists. A rollback trigger fires when critical functionality breaks after a completion is accepted. Each level makes cutting corners progressively harder, forcing evidence as the only path through.
The system handles failures through structured escalation:
### Level 1: Soft Block
Red flag phrase detected. Request clarification:
"You mentioned 'should work'. What specific evidence supports this? Please provide build output or test results."
### Level 2: Hard Block
Completion claimed without evidence. Block the completion:
"Task cannot be marked complete. Required: build output showing success OR test results passing."
### Level 3: Rollback Trigger
Critical functionality broken after completion:
"Verification failed post-completion. Initiating rollback to last known good state."
The escalation makes cutting corners progressively harder. Evidence is the only path through.
## FAQ: Implementing Verification Gates
**Why is 'should work' dangerous in AI development?**
It indicates a claim without evidence. The AI (or developer) is expressing confidence without verification. This confidence often masks untested assumptions, missing edge cases, or fundamental errors.
**What is forced evaluation mode?**
A mandatory 3-step protocol: evaluate each skill (YES/NO with reasoning), activate every YES, then implement. Research shows 84% compliance vs 20% with passive suggestions. The commitment mechanism creates follow-through.
**What phrases indicate unverified AI code?**
Red flags include: 'Should work', 'Probably fine', 'I'm confident', 'Looks good', 'Seems correct'. These all express certainty without evidence of testing, building, or verification.
**What evidence should replace confidence claims?**
Specific proof: 'Build completed: exit code 0', 'Tests passing: 47/47', 'Screenshot at 375px shows correct layout', 'Bundle size: 287KB'. Facts, not feelings.
**How do I implement verification gates for AI code?**
Add hooks that run after AI responses. Check for red flag phrases and reject them. Require build output, test results, or screenshots before marking tasks complete. Make evidence the only path forward.
---
## What 84% Compliance Actually Looks Like
The difference between passive suggestions and forced evaluation isn't subtle. Here's a real before/after from my workflow.
**Before: Passive verification (20% compliance)**
I'd finish a feature and the AI would say something like: "The authentication flow should work. I've added the JWT utility, updated the login endpoint, and configured the cookie settings."
I'd read that, nod, move on. Three hours later, a 500 error in production. The cookie wasn't being set correctly because the response headers weren't configured for httpOnly. The AI was confident. I trusted the confidence.
**After: Forced evaluation (84% compliance)**
Now the same session ends with:
```
Build evidence:
npm run build → exit code 0 (9.51s)
No TypeScript errors
Test evidence:
Auth flow test: PASS
Cookie setting test: PASS
JWT expiry test: PASS
Screenshots:
Login form: renders correctly at 375px
Session persistence: verified across refresh
```
The AI runs the build. Shows the output. Takes screenshots. States the exit code.
The 84% compliance number comes from sessions where I tracked whether I actually ran verification before marking tasks done. Forced evaluation--where the AI had to provide evidence before I'd accept completion--produced compliance in 84 out of 100 sessions. Passive suggestions produced it in about 20.
The remaining 16%? Those were genuine time-sensitive situations where I consciously chose to accept risk. That's fine. The point isn't 100% verification. It's making the default behavior evidence-based instead of confidence-based.
Every time I skipped verification and got lucky, it reinforced the wrong habit. Every time the build caught something I'd have shipped, it reinforced the right one. Eventually the new habit won.
I hated the extra friction at first. But I love the part where I stop spending evenings debugging production issues.
I thought the problem was AI accuracy. Well, it's more like... the problem was my verification laziness. The AI generates good code most of the time. But "most of the time" isn't good enough for production.
Maybe the goal isn't trusting AI less. Maybe it's trusting evidence more--and building systems that make "should work" impossible to accept.
If your team re-checks AI output by hand before it ships, you are paying twice for the same work: once for the AI to write it, once for a person to verify it wasn't lying. I build the verification gates that catch bad output before it reaches production, custom Claude Code pipelines, $2,000 to $5,000. [See how that engagement works](/services).
---
## Related Reading
This is part of the [Complete Claude Code Guide](/blog/claude-code-complete-guide). Continue with:
- [Quality Control System](/blog/how-i-build-with-claude-code) - Two-gate enforcement that blocks implementation until gates pass
- [Context Management](/blog/claude-context-management-dev-docs) - Dev docs workflow that prevents context amnesia
- [Token Optimization](/blog/reduce-ai-token-usage-progressive-disclosure) - Save 60% with progressive disclosure
--- END POST ---
================================================================================
POST: AI-First Product Development: 5 Products Shipped With Agents, Not IDE Plugins
================================================================================
URL: https://chudi.dev/blog/ai-first-product-development-future
Date: 2026-01-17T00:00:00.000Z
Tags: ai, future, philosophy, automation, software-development
Pillar: philosophy
Reading Time: 10 min
Word Count: 1913
TL;DR: We're at an inflection point. The current model, humans write code, AI assists, is already outdated. The future is AI-first: AI agents handle the development workflow, humans make strategic decisions. MicroSaaSBot shipped a production SaaS in 7 days. That's not a demo; it's a signal. The developers who thrive will be the ones who learn to orchestrate AI systems, not just prompt them.
Key Takeaways:
- The shift: from 'AI assists human coding' to 'AI develops, humans direct'
- MicroSaaSBot is proof of concept, complete workflow automation from idea to deployment
- Humans remain essential for: strategic decisions, user empathy, business judgment, edge cases
- The 10-year trajectory: most CRUD apps built by AI, developers focus on novel problems
- Skill evolution: prompt engineering → system orchestration → AI product management
--- CONTENT ---
AI-first product development means AI agents handle entire phases of the development lifecycle, from research and architecture to implementation and deployment, while humans review and approve output rather than writing first drafts. The bottleneck shifts from execution speed to decision quality. MicroSaaSBot proved this is viable today: it shipped StatementSync, a production SaaS with auth, file processing, and billing, in 7 days.
The way we build software is about to change fundamentally.
Not gradually. Not incrementally. Fundamentally.
I built MicroSaaSBot as a bet on this future. Here's the thesis.
AI-first product development means AI agents handle entire phases of the development lifecycle, not just code completion. Research, architecture, implementation, and deployment become orchestrated agent workflows. The bottleneck shifts from execution speed to problem selection and quality control. Here's what that looks like in practice.
## What Is AI-First Product Development?
AI-first product development means AI agents handle entire phases of the development lifecycle, research, architecture, implementation, and deployment, rather than just assisting with code completion. Humans shift from writing code to reviewing and approving agent output, with the bottleneck moving from execution speed to decision quality.
## The Current Paradigm
Today's AI coding tools follow a pattern:
**Human writes code → AI assists**
- Copilot completes your lines
- Cursor edits your files
- ChatGPT answers your questions
The human remains the driver. AI is the passenger offering suggestions.
This works. It's faster than coding alone. But it's not where we're heading.
## The Next Paradigm
The future inverts the relationship:
**AI develops → Human directs**
- AI handles the development workflow
- Human makes strategic decisions
- AI executes, human evaluates
MicroSaaSBot is an early implementation of this pattern. It takes a problem statement and outputs a deployed product. The human approves phases, not lines of code.
## Why Is the Shift to AI-First Development Happening Now?
Three forces are driving the shift: AI capability has reached production quality, the bottleneck has moved from "can AI write code" to "can we orchestrate AI effectively," and economic pressure is overwhelming. When AI can ship an MVP in seven days instead of seven weeks, companies that don't adopt AI-first workflows get outcompeted by those that do.
## Why This Shift Is Happening
### 1. AI capabilities are sufficient
GPT-5 and Claude can:
- Write production-quality code
- Understand complex architectures
- Debug non-trivial problems
- Follow multi-step instructions
The capability gap between "AI assists" and "AI develops" has closed.
### 2. The bottleneck has moved
In 2015, the bottleneck was "can AI write correct code?"
In 2020, the bottleneck was "can AI understand context?"
In 2025, the bottleneck is "can we orchestrate AI effectively?"
The hard problem isn't AI capability, it's system design.
### 3. Economic pressure is real
Developers are expensive. Development takes time. Startups need to move fast.
If AI can ship an MVP in 7 days instead of 7 weeks, the economic incentive is overwhelming. Companies that don't adopt AI-first development will be outcompeted by those that do.
## What MicroSaaSBot Proves
StatementSync is not a demo. It's a production SaaS with:
- Real user authentication
- Real file processing
- Real payment collection
- Real customer value
Built in 7 days by AI agents with human oversight.
MicroSaaSBot isn't special because it uses AI. It's special because it treats AI as the developer, not the assistant. The architecture assumes AI does the work; humans make decisions.
This pattern, AI executes, humans direct, is the future of product development.
## What Do Humans Still Do Better Than AI in Development?
Humans remain essential for strategic decisions about what to build and for whom, user empathy that goes beyond pattern analysis, edge cases where standard patterns break, novel architectural problems that require extrapolation into the unknown, and accountability, AI cannot be held responsible for failures in any meaningful sense.
## What Humans Still Do Better
AI-first doesn't mean human-free.
**Strategic decisions**: What should we build? For whom? At what price? AI can provide data, but humans make judgment calls.
**User empathy**: Understanding why users behave the way they do. AI can analyze patterns; humans can feel friction.
**Edge cases**: When the standard pattern doesn't apply. AI follows learned patterns; humans recognize when patterns break.
**Novel problems**: Truly new architectures, unprecedented challenges. AI interpolates from training data; humans extrapolate into the unknown.
**Accountability**: When things break, humans are responsible. AI can't be held accountable in any meaningful sense, a principle formalized in the [NIST AI Risk Management Framework](https://www.nist.gov/publications/artificial-intelligence-risk-management-framework-ai-rmf-10), which places governance responsibility on human operators.
The future isn't AI replacing humans. It's AI handling the 80% of development that's pattern-matching while humans focus on the 20% that requires judgment.
## The 10-Year Trajectory
**2025**: Early adopters use AI-first for MVPs. Most developers still write code with AI assistance.
**2027**: AI-first becomes standard for startups building standard apps (CRUD, dashboards, content platforms). Custom work still human-heavy.
**2030**: Most web applications built primarily by AI. Developers focus on novel systems, AI orchestration, and edge cases.
**2035**: "Manual coding" becomes a specialist skill like assembly programming today, valuable but niche.
This isn't speculation. It's extrapolation from current trends. Claude and GPT-5 can already build production apps. The only questions are: How fast does adoption happen? How quickly do the tools improve?
## Skill Evolution
The skills that matter are shifting:
**Yesterday** (2020):
- Writing clean code
- Knowing frameworks deeply
- Debugging efficiently
**Today** (2025):
- Prompt engineering
- AI output evaluation
- Hybrid human-AI workflows
**Tomorrow** (2030):
- System orchestration
- AI product management
- Edge case handling
- Domain expertise
The trajectory is clear: from "writing code" to "directing systems."
## What This Means for Developers
### If you're junior:
Learn fundamentals, you still need to evaluate AI output. But also learn AI orchestration early. The developers entering the field in 2025 who master AI-first development will have a massive advantage.
### If you're senior:
Your judgment is more valuable than ever. AI can write code; it can't decide what to build or evaluate whether it's good. Your architecture skills, debugging intuition, and domain knowledge become leverage points.
### If you're a founder:
Start using AI-first development now. The time savings are real. MicroSaaSBot shipped StatementSync in 7 days, that's 6 weeks of developer time saved. At $150/hour, that's $36,000 per product.
## The Transition Challenge
Not everyone will make this transition gracefully.
**Developers who resist**: "AI can't write real code." They'll be outcompeted by those who embrace AI-first development. The code quality debates will persist until economic pressure overwhelms them.
**Developers who over-rely**: "AI can do everything." They'll ship buggy products, miss edge cases, and lack the judgment to improve. Over-reliance is as dangerous as resistance.
**Developers who adapt**: "AI is a powerful tool I can orchestrate." They'll ship faster, focus on high-value problems, and remain relevant as the field evolves, building the kind of responsible, accountable systems the [NIST AI Risk Management Framework](https://www.nist.gov/publications/artificial-intelligence-risk-management-framework-ai-rmf-10) calls for.
If your job is primarily writing CRUD applications and standard API endpoints, that job is being automated. The question isn't whether, it's when. Prepare now.
## My Bet
MicroSaaSBot is my bet on this future.
I built it because I believe:
1. AI-first development is viable today
2. The pattern will become dominant
3. Those who master it early will have advantages
StatementSync proves viability. Now I'm scaling further, more products, more complex systems, more [autonomous workflows](/blog/openclaw-autonomous-blog-agent).
The future isn't AI replacing developers. It's developers who orchestrate AI systems outcompeting developers who don't.
Which side will you be on?
## What AI-First Actually Means in Practice
"AI-first" gets used to mean a lot of things. Let me be specific about what it meant for StatementSync.
It meant the Researcher agent did the market analysis--competitor pricing, user pain point research, willingness-to-pay signals--before I looked at any of it. I reviewed the output, not the raw data.
It meant the Architect agent designed the database schema based on the validation report. I reviewed the schema. I didn't draft it.
It meant the Developer agent wrote the PDF parsing logic, the Stripe webhook handlers, the SvelteKit routes. I reviewed the code for correctness and edge cases. I didn't write the first draft.
It meant the Deployer agent configured the Vercel project, set up the Supabase database, connected the Stripe webhooks. I verified the live URL worked. I didn't run the deployment commands.
My job was reviewing and approving, not executing. That's a fundamentally different role than "developer who uses AI for autocomplete."
The concrete result: I shipped a production SaaS with auth, file processing, and billing in 7 days. Not 7 weeks. The constraint wasn't my ability to write code--it was the time required to make good decisions about what to build and whether the implementation was sound.
AI-first removes execution time from the critical path. Decision time remains. The complete day-by-day breakdown of how this played out for StatementSync is in [MicroSaaSBot: Idea to Deployed MVP](/blog/introducing-microsaasbot-ai-builds-saas).
That's what it actually means.
## How Do You Transition to an AI-First Workflow?
Stop writing first drafts and start reviewing AI's first drafts instead. Stop treating AI output as final without verification. Stop loading maximum context, focused input produces better output. Stop accepting "should work" without evidence. The transition takes a few weeks and includes a productivity dip before you emerge shipping significantly faster than before.
## The Transition: What to Stop Doing Now
The shift to AI-first doesn't happen all at once. But there are specific habits that slow the transition down. I had to stop doing all of these.
**Stop writing first drafts.** This was the hardest one. My instinct was to sketch out a function, then ask AI to improve it. That's backwards. Ask AI for the first draft. Then review, critique, and improve. The first draft is the cheap part--reviewing is the valuable part.
**Stop treating AI output as final.** The opposite failure. Paste the output in, ship it, find the bug in production. AI-first still requires evaluation. It just moves evaluation earlier in the workflow.
**Stop loading maximum context.** If you're giving AI everything--all the docs, all the files, all the rules--you're not being thorough, you're creating noise. Focused context produces better output. I learned this from building the [progressive disclosure system](/blog/reduce-ai-token-usage-progressive-disclosure) for my Claude setup.
**Stop accepting "should work."** The phrase indicates an unverified claim. AI-first development requires the same evidence standard as any other development. Build passes. Tests pass. Screenshots confirm. No exceptions.
**Stop thinking in files.** Human coding is file-centric: open a file, edit it, save it. AI-first development is task-centric: define the outcome, let the agent figure out which files to touch. Fighting your way back to file-centric thinking when using AI adds unnecessary friction.
The transition takes a few weeks. There's a dip in productivity while you unlearn habits that served you well in the old model. Then you come out the other side shipping faster than before.
I went through this transition over about 3 months. The first month was slower. The third month shipped more than the previous three months combined.
## The Opportunity
Right now, most developers use AI like a fancy autocomplete. A few of us are building systems where AI does the development and humans make decisions.
This gap, between AI-as-assistant and AI-as-developer, is the opportunity.
MicroSaaSBot isn't the only path. But it's proof that the path exists. AI-first product development isn't a vision for 2030. It's working code in 2025.
The future is already here. It's just not evenly distributed.
---
**Related**: [Introducing MicroSaaSBot](/blog/introducing-microsaasbot-ai-builds-saas) | [Portfolio: MicroSaaSBot](/portfolio/microsaasbot)
--- END POST ---
================================================================================
POST: Claude Code Best Practices 2026: What the Official Docs Don't Cover
================================================================================
URL: https://chudi.dev/blog/claude-code-complete-guide
Date: 2026-01-17T00:00:00.000Z
Tags: claude-code, ai, workflow, tutorial, productivity
Pillar: ai-building
Reading Time: 19 min
Word Count: 3694
TL;DR: I shipped broken code three times in one week. The AI said 'should work.' Without me realizing it, I was trusting confidence over evidence. This guide covers the system I built: two-gate quality control, context management with dev docs, and progressive disclosure. Well, it's more like a complete shift in how I work with AI.
Key Takeaways:
- Two-gate system blocks implementation until quality checks pass, eliminating 'should work' claims
- Dev docs (plan.md, context.md, tasks.md) prevent context amnesia across sessions
- Progressive disclosure saves 60% tokens by loading skill metadata first, full content on demand
- Evidence-based completion requires actual build output, test results, or screenshots before marking done
- The goal isn't trusting AI less. It's trusting evidence more
--- CONTENT ---
The official Claude Code docs cover installation and commands. They do not cover what keeps AI-generated code from breaking in production. Here are the five practices that held up across 36,000 lines of shipped code: plan before touching multiple files, persist decisions in dev docs so context survives compaction, require build output and test results before accepting any completion claim, load context progressively, and run regression checks after every bounded change.
A production Claude Code workflow has five layers: plan the bounded change, load only relevant context, persist decisions outside the conversation, require tool-produced verification, and record enough state to recover after compaction. Everything else in this guide supports one of those five layers.
I shipped broken code three times in one week. The AI said "should work." I believed it.
That experience led me to build a complete system for AI-assisted development, one where evidence replaces confidence, context persists across sessions, and quality gates make cutting corners impossible.
This guide covers everything I've learned building with Claude Code, most of it shipped inside a [36,000-line production trading bot](/blog/claude-code-production-trading-bot) that runs real money.
## Which Claude Code best practices actually survive production?
The Claude Code best practices that held up in a production trading system are: plan before changing multiple files, persist decisions in dev docs, require build and test evidence before accepting completion, load context progressively, and run regression checks after every bounded change. These are operating rules from a real trading codebase, not a list of features. Together, they kept context accurate as the codebase grew and blocked silent production bugs before they reached live capital.
Anthropic's documentation explains what Claude Code can do. This field guide explains how I operate it when failed output has a real cost: every non-trivial task gets a written boundary, every long session leaves a recoverable state, and every completion claim needs a receipt.
| Practice | Production rule | Failure it prevents |
|----------|-----------------|---------------------|
| Plan before code | Write and approve a plan before work that crosses multiple files | Confident changes that conflict with existing architecture |
| Persist context | Keep plan.md, context.md, and tasks.md outside the chat window | Lost decisions after compaction or a new session |
| Demand evidence | Require type checks, tests, builds, or screenshots | Accepting "should work" as completion |
| Load progressively | Start with the project map, then load only task-relevant files | Token waste and stale-context hallucinations |
| Check regressions | Run the smallest relevant check, then type checks, tests, and the production build before shipping | Fixing one path while quietly breaking another |
| Before Claude edits | While Claude works | Before accepting completion |
|---|---|---|
| Define the requested outcome and excluded scope | Keep the change bounded to one testable unit | Inspect the actual diff |
| Identify affected files and dependencies | Load only task-relevant context | Run the smallest relevant test |
| Write a plan for multi-file work | Update persistent task state after decisions | Run type checks and the production build when applicable |
| Select the model and effort tier by workload | Stop when evidence contradicts the plan | Require logs, screenshots, or command output |
## What Is Claude Code and How Is It Different From Cursor or Copilot?
Claude Code is Anthropic's CLI tool that runs in your terminal with full codebase access and agentic capabilities. Unlike Cursor or Copilot, IDE plugins focused on inline completions, Claude Code can execute commands, manage files, run builds, and maintain context across long sessions through persistent dev docs rather than stateless chat.

*Claude Code doesn't just answer once. Each task cycles through planning, tool calls, and evidence-based verification, then the loop repeats for the next bounded task instead of ending the conversation. That cycle, not the chat window, is the mental model for the rest of this guide.*
## How is this Claude Code guide organized?
This guide is organized into four core areas:
## What is the minimum production-safe Claude Code workflow?
The minimum production-safe workflow is plan, implement, verify, and preserve state. Plan before multi-file work. Implement one bounded unit. Verify it with a diff and the cheapest reliable test. Preserve decisions in dev docs before the context is compacted or the session ends. Skipping any one of these stages creates a predictable failure: architectural drift, oversized changes, unsupported completion claims, or lost context.
Model selection belongs inside that workflow rather than above it. [Choose the Claude model and effort tier by workload](/blog/claude-fable-5-vs-opus-4-8). Since Opus 5.5 shipped, [my Opus 5.5 vs Fable 5.1 cost-per-turn replay](/blog/claude-opus-5-5-vs-fable-5-1) shows Fable now costing 2.3x Opus per turn on my measured day. Then preserve the result with [the complete three-file context-compaction workflow](/blog/claude-context-management-dev-docs). The system has been exercised in [a 36,000-line trading-bot case study](/blog/claude-code-production-trading-bot) and in [evidence-gated automation for security workflows](/blog/bug-bounty-automation).
## How Does the Two-Gate System Prevent Broken AI Code?
Gate 0 validates your context budget and loads phrase blocking to prevent "should work" claims. Gate 1 analyzes your query and activates the relevant skills from a library of 30-plus defined patterns. Both gates must pass before any implementation tools unlock, making unverified confidence structurally impossible rather than something that relies on discipline.
## Part 1: Quality Control That Actually Works
The biggest mistake in AI-assisted development is accepting confidence as evidence.
When Claude says "should work," that's not verification, it's a guess. The two-gate system I built makes guessing impossible by blocking all implementation tools until quality checks pass.
For the complete breakdown of gates, phrase blocking, and the 4 pillars of quality, read: **[I Built a Quality Control System for AI Code Generation](/blog/how-i-build-with-claude-code)**
### The Core Principle
**Gate 0: Meta-Orchestration**
- Validates context budget (under 75%)
- Loads quality gates and phrase blocking
- Initializes the skill system
**Gate 1: Auto-Skill Activation**
- Analyzes your query intent
- Matches against 30+ defined skills
- Activates top 5 relevant skills
Only after both gates pass can you write code. Like buttoning a shirt from the first hole, skip it, and everything else is wrong.
### Evidence Over Confidence
These phrases get blocked:
| Red Flag | Problem |
|----------|---------|
| "Should work" | No verification |
| "Probably fine" | Uncertainty masked as completion |
| "I'm confident" | Feeling, not fact |
| "Looks good" | Visual assessment, not testing |
**Replace with evidence:**
```
Build completed: exit code 0, 9.51s
Tests passing: 47/47
Bundle size: 287KB
```
For the complete verification system including the 84% compliance protocol, see the [full quality control guide](/blog/how-i-build-with-claude-code).
---
## How Do You Stop Claude From Forgetting Context Between Sessions?
Create three dev doc files for every non-trivial task: plan.md as the approved implementation blueprint, context.md as a living record of current progress and key decisions, and tasks.md as a granular checklist. Before context compacts, run /update-dev-docs. After compaction, say "continue" and Claude reads the files automatically, no re-explaining required.
## Part 2: Context Management
"We already discussed this."
I said it. Claude didn't remember. Thirty minutes of context, file locations, decisions, progress, gone after compaction.
The dev docs workflow solves this permanently.
For the complete dev docs workflow including automation hooks, read: **[How to Prevent Claude from Forgetting Your Task](/blog/claude-context-management-dev-docs)**
Building with ADHD? The [ADHD-friendly Claude Code workflow](/blog/claude-adhd-executive-function-mode) adapts this for executive-function friction.
### The Three Dev Doc Files
Every non-trivial task gets a directory:
```
~/dev/active/[task-name]/
├── [task-name]-plan.md # Approved blueprint
├── [task-name]-context.md # Living state
└── [task-name]-tasks.md # Checklist
```
**plan.md**: The implementation plan, approved before coding. Doesn't change during work.
**context.md**: Current progress, key findings, blockers. Updated frequently.
**tasks.md**: Granular work items with status. Check items as you complete them.
### The Magic Moment
```
[Context compacted]
You: "continue"
Claude: [Reads dev docs automatically, knows exactly where you are]
```
No re-explaining. No lost progress. Just continuation.
When to use dev docs:
- Any task taking more than 30 minutes
- Multi-session work
- Complex features with multiple files
- Anything you'd hate to re-explain
For the complete workflow including 16 automation hooks, see the [context management guide](/blog/claude-context-management-dev-docs).
---
## Part 3: Token Optimization
Most Claude configurations load everything upfront. Every skill, every rule, every example, thousands of tokens consumed before you've asked a question.
Progressive disclosure flips this.
For the complete progressive disclosure implementation, read: **[How to Reduce AI Token Usage by 60%](/blog/reduce-ai-token-usage-progressive-disclosure)**
Tokens also decide how fast a Pro or Max plan runs out, because Claude Code shares one usage limit with claude.ai. [Claude usage limits](/blog/claude-usage-limits) explains the five-hour session and the weekly cap, [Claude Code usage limits](/blog/claude-code-quota-burn-10-patterns) covers what burns that limit inside Claude Code, and [Claude pricing](/blog/claude-pricing) lists every plan and API price.
### The 3-Tier System
| Tier | Content | Tokens | When Loaded |
|------|---------|--------|-------------|
| 1 | Metadata | ~200 | Immediately |
| 2 | Schema | ~400 | First tool use |
| 3 | Full | ~1200 | On demand |
**Tier 1**: Skill name, triggers, dependencies. Just enough to route the query.
**Tier 2**: Input/output types, constraints, tools available.
**Tier 3**: Complete handler logic, examples, edge cases.
The meta-orchestration skill alone: 278 lines at Tier 1, 816 with one reference, 3,302 fully loaded. That's 60% savings on every session that doesn't need the full content.
For implementation details and your own skill definitions, see the [token optimization guide](/blog/reduce-ai-token-usage-progressive-disclosure).
---
## Part 4: Foundational Concepts
Before building complex AI workflows, you need to understand the underlying patterns.
### RAG: Retrieval-Augmented Generation
RAG gives LLMs access to external knowledge at inference time. [Introduced in a 2020 Meta AI paper](https://arxiv.org/abs/2005.11401) and now foundational to production AI systems, RAG pulls in relevant documents before generating, rather than relying solely on training data with a fixed knowledge cutoff.
For the complete RAG explanation with code examples, read: **[What is RAG? Retrieval-Augmented Generation Explained](/blog/what-is-rag)**
**The pattern:**
1. Query Processing → 2. Retrieval → 3. Augmentation → 4. Generation
Every time you feed context to Claude before asking questions, you're using RAG. The dev docs workflow is essentially manual RAG, retrieving your context files before generation.
### Evidence-Based Verification
"Should work" is the most dangerous phrase in AI development. It indicates confidence without evidence.
For the psychology of verification and the 84% compliance protocol, read: **[Why 'Should Work' Is the Most Dangerous Phrase](/blog/ai-code-verification-evidence-based)**
**The forced evaluation protocol:**
1. EVALUATE: Score each skill YES/NO with reasoning
2. ACTIVATE: Invoke every YES skill
3. IMPLEMENT: Only then proceed
Research shows 84% compliance with forced evaluation vs 20% with passive suggestions. The commitment mechanism creates follow-through.
---
## What Are the Most Common Claude Code Mistakes to Avoid?
Four mistakes account for most Claude Code failures: writing context in chat instead of files, using Claude to make decisions rather than execute bounded tasks, skipping gate checks when tired or rushed, and letting sessions run for hours without checkpointing. The last one degrades output quality as abandoned approaches and recovered errors accumulate in the context window.
## Part 5: Common Failure Modes
After building the quality control system, I've watched colleagues start using Claude Code and make the same mistakes. These are the ones worth knowing before you hit them.
### Treating every task as a conversation
Claude Code's memory resets at the start of each session. Most people know this. But they still write context in chat messages instead of files. "Remember that we're using PostgreSQL, not MySQL" gets lost when context compacts. Write it in a file once, reference the file every session.
The dev docs workflow exists precisely for this. Before any significant session, start with: "Read context.md and give me a brief on where we are." Five seconds, no lost context.
### Using Claude for decisions instead of execution
Claude Code is a tool for doing things, not deciding what to do. If you're asking it "should I use Redux or Zustand?" or "is this architecture good?", you're using it wrong. Make the decision yourself (or with a separate research session), then give Claude Code a clear, bounded task.
The clearer your input, the higher the quality of your output. "Implement a Redux store for auth state with these specific actions" produces better results than "help me set up state management."
### Skipping the gate check when tired
The two-gate system works when you follow it and fails immediately when you skip it. The temptation to skip is highest when you're tired, rushing, or "just need to make one small change." That's exactly when it matters most. Small unverified changes in tired states are where production bugs come from. In my [Claude Code trading bot](/blog/claude-code-production-trading-bot), this system caught 8 silent bugs over four months before any of them touched live capital.
The gate isn't bureaucracy. It's the system protecting you from yourself at 11 PM.
### Letting context balloon without checkpointing
A session that starts with a clear task and runs for three hours without checkpointing will start producing worse results as context fills. Claude Code sees everything in the window, including the tentative approaches you abandoned, the errors you hit and recovered from, the exploratory tangents. All of that degrades signal.
Checkpoint every 45–60 minutes on long tasks. Run `/update-dev-docs`. The next sub-session starts clean. Quality stays high.
## Part 6: Adapting to Your Stack
The gates, dev docs, and progressive disclosure patterns work across stacks. But how you apply them varies by project type.
### SvelteKit + Static Sites
The context file structure for a SvelteKit project should reflect the routing model. Your context.md should document which routes are prerendered, which are server-side, and which are client-side, because Claude will make different assumptions about data loading depending on what it thinks the rendering strategy is.
One mistake I made early: assuming Claude remembered that a specific route was prerendered. It didn't. Every session it would suggest server-side loading patterns that don't apply to static routes. A two-line note in context.md, "route /blog is prerendered, no server hooks, use data exported from +page.ts", eliminated that class of confusion entirely.
The build gate matters more for SvelteKit than some other stacks because the static adapter has strict requirements. Dynamic imports, server-only code in client components, and missing types cause build failures that don't surface in dev mode. Make `pnpm build` non-negotiable before marking any task complete.
### Next.js App Router
The App Router's server component versus client component distinction is the most common source of confusion in Claude Code sessions. Claude will occasionally suggest a hook or browser API inside a server component, or vice versa.
Capture the component hierarchy in your context.md: which components are server components (no `'use client'`), which are client components, and which are shared utilities. This isn't excessive documentation, it's the exact information Claude needs to avoid the most common class of error.
Evidence gate addition for Next.js: add `tsc --noEmit` to your gate checklist. TypeScript errors in App Router code often don't surface until type-checking because the dev server is permissive.
### Pure API Projects
API-only projects benefit most from the dev docs workflow because the relevant context is all in files, no visual output to check, no screenshots, just data shapes and endpoint contracts.
Your context.md for an API project should always include: the current database schema, the authentication model, and the active endpoints with their expected inputs and outputs. Keep it to one page. If it's longer, you're capturing implementation details that belong in code comments, not context.
For evidence gates, add a smoke test to the checklist: one curl command per major endpoint that should return a 200. Not comprehensive integration tests, just enough to confirm the service is responding correctly before you consider the session complete.
### Long-Running Projects
The three-file dev docs structure was designed for task-level work, features and bug fixes that complete in days. For projects that run months, add a fourth file: `project-context.md`.
`project-context.md` captures what doesn't change session-to-session: the architectural decisions, the tech stack choices and the reasons for them, the non-negotiable constraints, and the vocabulary the codebase uses. What the project calls "users" versus "accounts" versus "members" matters more than you'd expect.
This file gets read at the start of every session, before context.md. It's the stable foundation that prevents Claude from proposing changes that would violate architectural constraints established months ago.
The investment: 30 minutes once, saved every session for the life of the project.
## Getting Started
If you would rather start from a preconfigured baseline than build this by hand, the [Claude Code setup kit](/claude-code-setup) packages the structure below.
### Minimum Viable Setup
1. **Create a CLAUDE.md** in your project root with basic gate enforcement
2. **Set up a dev/ directory** for task documentation
3. **Add "continue" handling** to resume after compaction
### Full Setup
1. Install the dev docs commands (slash commands or aliases)
2. Configure hooks for automatic skill activation
3. Set up build checking on Stop events
4. Create workspace structure for multi-repo projects
The full system takes a few hours to configure. But it saves that time on every long task thereafter.
---
## Related Guides
### Claude Code Fundamentals
- [Quality Control System](/blog/how-i-build-with-claude-code) - Two-gate enforcement, phrase blocking
- [Context Management](/blog/claude-context-management-dev-docs) - Dev docs, automation hooks
- [Token Optimization](/blog/reduce-ai-token-usage-progressive-disclosure) - Progressive disclosure, 60% savings
### Foundational Concepts
- [What is RAG?](/blog/what-is-rag) - Retrieval-augmented generation explained
- [Evidence-Based Verification](/blog/ai-code-verification-evidence-based) - Why "should work" fails
---
## 2026 Update: Computer Use and Browser Automation
Claude Code now supports computer use through MCP (Model Context Protocol) tools. This means Claude can control your desktop, browser, and applications directly from the terminal.
MCP servers also feed Claude framework knowledge it would otherwise guess at. For one worked example, see [the official Svelte MCP server and what its autofixer found in 134 SvelteKit components](/blog/sveltekit-mcp-server-claude-code).
### What Computer Use Enables
- **Browser automation**: Navigate websites, fill forms, click buttons, and extract data through Chrome DevTools integration
- **Desktop control**: Launch applications, take screenshots, type text, and interact with native UI elements
- **Multi-tool orchestration**: Combine file editing, terminal commands, and browser automation in a single workflow
### Setting Up Computer Use
Computer use requires the Claude in Chrome extension and the computer-use MCP server. Once connected, Claude can:
1. Open URLs and navigate between pages
2. Read page content and execute JavaScript
3. Fill forms and submit data
4. Take screenshots for visual verification
5. Control desktop applications via accessibility APIs
### Practical Applications
The combination of terminal access and browser control creates workflows that were previously impossible:
- **Deploy and verify**: Push code to production, then open the browser to visually confirm the deployment worked
- **SEO auditing**: Check meta tags, structured data, and page content across multiple URLs programmatically
- **Form testing**: Fill out multi-step forms to verify validation logic and submission flows
- **Cross-platform automation**: Edit code in the terminal, test it in the browser, and document results, all in one session
This represents a shift from Claude Code as a coding assistant to Claude Code as a full development environment that spans terminal, editor, and browser.
### Hooks: Automating Quality Gates
Claude Code hooks let you run custom scripts at specific lifecycle events: PreToolUse (before a tool runs), PostToolUse (after a tool runs), Notification, and Stop. This turns manual quality checks into automated enforcement.
For example, a PreToolUse hook can block file writes to production config files. A PostToolUse hook can run linting after every code edit. A Stop hook can enforce that the build passes before the session ends.
The hook script receives event data on stdin and must return JSON with `{"continue": true}` to proceed. Here is a minimal Stop hook that checks the build:
```json
{
"hooks": {
"Stop": [{
"type": "command",
"command": "/bin/bash ~/.claude/scripts/check_build.sh"
}]
}
}
```
Hooks are configured in `~/.claude/settings.json` and run synchronously (blocking) or asynchronously (fire-and-forget) depending on the event type. For a complete implementation walkthrough, see [Claude Code Hooks Tutorial](/blog/claude-code-hooks-tutorial).
To choose between a hook, a skill, a subagent and a CLAUDE.md line, see [Claude Code skills vs subagents](/blog/claude-code-skills-vs-subagents). To write your first skill, see [Claude Code skills](/blog/claude-code-skills). If your repo also keeps an AGENTS.md, [Claude Code and AGENTS.md](/blog/claude-code-agents-md) covers how the two files load.
### Multi-Agent Orchestration
Claude Code supports spawning sub-agents for parallel task execution. Each agent runs in its own context with access to specified tools, and results flow back to the parent session.
Common patterns:
- **Parallel search**: Spawn multiple Haiku agents to explore different parts of a codebase simultaneously
- **Build and test**: Run a build-fixer agent alongside a test-runner agent after making changes
- **Code review pipeline**: Use a Haiku triage agent for fast first-pass review, then an Opus agent for deep analysis on flagged items
Agent isolation via git worktrees prevents concurrent agents from corrupting each other's file changes. Read-only agents (exploration, review) do not need isolation. Write agents always should use it.
### The Gate-Receipt Pattern: Quality Gates That Survive Automation
Quality gates that need judgment, like whether content reads as human-written or a title survives mobile truncation, run as Claude-invoked skills that need a live session. Cron jobs have none. The gate-receipt pattern bridges them: the skill writes a small receipt file when it runs, and the automated script refuses to proceed without a passing one.
Concretely: when the gate skill finishes, it writes `gate-receipts/- .json` with its verdict and score. The cron-runnable pipeline reads that file before any irreversible step (publishing, submitting, deploying) and blocks if the receipt is missing or marks a failure. The judgment happens in the session where it belongs; the determinism happens in cron where it scales.
Without this, you get one of two bad outcomes: drop the subjective gate and let an unattended pipeline ship slop, or block the whole pipeline on a human and lose the automation. The receipt is the contract between the two layers, and it is the only way I have found to put a judgment call inside a job that runs with nobody watching.
---
## The Bottom Line
[Claude Code](https://docs.anthropic.com/en/docs/claude-code) isn't just a code generator. With the right systems, it becomes a quality-controlled collaborator.
The goal isn't trusting AI less. It's trusting evidence more, and building systems that make "should work" impossible to accept.
Start with dev docs. Add the gate system. Implement progressive disclosure. Each piece builds on the last.
The AI was always capable. We just needed guardrails that made evidence the only path forward.
---
`WORK WITH ME · SAME PROCESS, YOUR REPO`
> If your team re-checks AI output by hand before every deploy, you are paying twice for the same work. I build custom Claude Code pipelines, $2,000 to $5,000 with a written scope and a fixed quote, that wire these hooks, gates, and multi-agent workflows directly into your repo. [See how the engagement works](/services).
--- END POST ---
================================================================================
POST: Claude Code 'Compaction Failed': Causes and 3 Fixes
================================================================================
URL: https://chudi.dev/blog/claude-context-management-dev-docs
Date: 2026-01-17T00:00:00.000Z
Tags: claude-code, ai, workflow, context, productivity
Pillar: ai-building
Reading Time: 20 min
Word Count: 3973
TL;DR: 'We already discussed this.' I said it. Claude didn't remember. Thirty minutes of context gone after compaction. Dev docs are three files that persist task state outside the conversation. Before compaction, run /update-dev-docs. After compaction, say 'continue' and Claude picks up exactly where you left off.
Key Takeaways:
- Context compaction loses file paths, decisions, and progress state. The 'we already discussed this' moment becomes your weekly reality
- Three dev doc files: plan.md (approved strategy), context.md (key files and decisions), tasks.md (checklist)
- Workflow: plan mode then /create-dev-docs then implement 1-2 sections then review then /update-dev-docs before compaction
- Automation hooks handle quality control: UserPromptSubmit (skill activation), Stop-BuildChecker (automatic builds)
- Use dev docs for tasks over 30 minutes or spanning multiple sessions. Skip for quick one-off fixes
--- CONTENT ---
If Claude Code shows "compaction failed, conversation could not be reduced below the context limit", or simply forgets what you discussed after compaction, the state you needed lived only in the conversation. If you got a different message, such as "summarization failed: generation hit the token cap", the cause is different and [the section on the other compaction errors](#what-do-the-other-claude-code-compaction-errors-mean) covers it. This is the context management module of the [complete Claude Code guide](/blog/claude-code-complete-guide): a three-file dev-docs system that keeps state outside the chat so you stop paying the rebuild tax every session.
**Claude context management** is the practice of persisting task state outside the conversation so Claude can resume exactly where it left off after context compaction. The standard method is a three-file system: plan.md (approved strategy), context.md (current state and key decisions), and tasks.md (progress checklist). Before compaction, run /update-dev-docs to save state; after compaction, type "continue" and Claude reads the files automatically, no re-explaining required.
I said it. Claude didn't remember. Thirty minutes of context-building: file locations, architectural decisions, progress updates, gone after compaction. We were starting over.
I've rebuilt context after compaction 40+ times before I fixed it. Each re-explanation averaged 20 minutes. That's over 13 hours of pure re-work.
The dev docs workflow prevents context amnesia by persisting task state outside the conversation. Three files: plan.md, context.md, tasks.md. They capture everything Claude needs to continue exactly where it left off. After compaction, say "continue" and the AI reads the docs automatically. No re-explaining. No lost progress.
## What happens during Claude Code context compaction?
Claude Code context compaction summarizes older conversation history when the active context becomes too large. The session continues, but exact file paths, rejected approaches, implementation decisions, error history, and unfinished steps can disappear from the working context. Compaction is not the same as a model becoming less capable. The model is working from a compressed and incomplete representation of the earlier session.
| Information at risk | What failure looks like | Persistent location |
|---|---|---|
| Approved architecture | Claude proposes an approach you already rejected | plan.md |
| Current files and symbols | Claude searches for the same code again | context.md |
| Completed work | Previously finished steps are repeated | tasks.md |
| Known errors | Failed approaches are attempted again | context.md |
| Next action | The resumed session starts from a generic guess | tasks.md |
Context compaction is necessary. Conversations grow too long. The AI summarizes older messages to make room for new ones. [Claude's context window documentation](https://docs.anthropic.com/en/docs/about-claude/models/overview) details the token limits that make compaction inevitable on long tasks.
The problem is what gets lost:
- **File paths** you spent time locating
- **Decisions** you already made together
- **Progress state** on multi-step tasks
- **Specific errors** you already debugged
That specific frustration: "we already discussed this." The kind where you want to rage-quit and start fresh. For me it became a weekly experience.
Here is the compaction math. A 3-hour implementation session hits compaction at roughly 90-120 minutes. If you have no persistence system, you spend 20-30 minutes rebuilding context. That is 25-35% of your session time going backwards.
I write more documentation to write less documentation. [Anthropic's documentation](https://docs.anthropic.com) describes how context management and structured prompting directly affect output quality across sessions.
The paradox resolves when you realize re-explaining is the most expensive documentation of all.
## How do you prevent context loss from compaction?
Prevent context loss by saving task state outside the conversation before compaction occurs. Keep the approved approach in plan.md, current files and decisions in context.md, and completed plus remaining work in tasks.md. Update those files after material decisions, not only when the context window is already full. After compaction, reload the three files before continuing implementation.
## What Are the Three Dev Doc Files?
The three dev doc files are plan.md, context.md, and tasks.md. Each task gets its own directory containing all three. Plan.md holds the approved implementation strategy. Context.md tracks current state, key files, and blockers. Tasks.md is a granular checklist with completion status. Together they persist everything Claude needs to resume after compaction.
Every non-trivial task gets a directory:
```
~/dev/active/[task-name]/
├── [task-name]-plan.md
├── [task-name]-context.md
└── [task-name]-tasks.md
```
### plan.md: The Approved Blueprint
The implementation plan, approved before coding begins.
```markdown
# Feature: User Authentication
## Approach
JWT-based auth with refresh tokens. Store in httpOnly cookies.
## Files to Modify
- src/routes/api/auth/+server.ts (create)
- src/lib/auth/jwt.ts (create)
- src/hooks.server.ts (modify)
## Decisions Made
- Chose JWT over sessions for stateless scaling
- 15-minute access token, 7-day refresh token
- No third-party auth initially
```
This file doesn't change during implementation. It's the reference point.
### context.md: The Living State
Current progress, key findings, blockers. Updated frequently.
```markdown
# Authentication - Current Context
## Progress
- [x] JWT utility created
- [x] Login endpoint working
- [ ] Refresh token rotation
- [ ] Protected route middleware
## Key Files
- src/lib/auth/jwt.ts:45 - Token generation
- src/routes/api/auth/login/+server.ts - Working endpoint
## Current State
Stuck on refresh token rotation. The cookie isn't being
set correctly in the response. See error at line 78.
## Next Steps
1. Debug cookie setting in +server.ts
2. Test with browser dev tools
3. Implement rotation logic
```
This is what Claude reads after compaction. It knows exactly where you are.
### tasks.md: The Checklist
Granular work items with status.
```markdown
# Authentication Tasks
## Phase 1: Core Auth
- [x] Create JWT utility functions
- [x] Implement login endpoint
- [x] Add password hashing
- [ ] Implement refresh rotation
- [ ] Add logout endpoint
## Phase 2: Protected Routes
- [ ] Create auth middleware
- [ ] Protect /dashboard routes
- [ ] Add redirect to login
## Phase 3: UI
- [ ] Login form component
- [ ] Error handling
- [ ] Success redirect
```
Check items as you complete them. Claude sees progress at a glance.
## What's the Complete Dev Docs Workflow?
The complete workflow runs in seven steps: enter plan mode, review the plan thoroughly, interrupt before implementation begins, run /create-dev-docs, implement one or two sections at a time, run /update-dev-docs before compaction, then say 'continue' after compaction. Claude reads the saved docs automatically and resumes without any re-explaining.
Here's the step-by-step process:
### 1. Enter Plan Mode
Start with planning, not coding. Always.
```
You: "I need to add user authentication"
Claude: [Enters plan mode, explores codebase]
```
### 2. Review the Plan Thoroughly
Catch mistakes before implementation.
```
You: [Read the plan carefully]
You: "What about rate limiting on login attempts?"
Claude: [Updates plan]
```
### 3. Hit ESC Before Implementation
Interrupt Claude before it starts coding.
```
Claude: "I'll start by creating the JWT utility..."
You: [Press ESC]
```
This prevents "gun-blazing" implementation without documentation.
### 4. Run /create-dev-docs
Create the three files from the approved plan.
```
You: "/create-dev-docs"
Claude: [Creates task directory with plan.md, context.md, tasks.md]
```
### 5. Implement 1-2 Sections at a Time
Don't do everything at once. Review between sections.
```
You: "Let's implement Phase 1: Core Auth"
Claude: [Implements, updates tasks.md]
You: [Review the code]
You: "Good, continue to Phase 2"
```
### 6. Run /update-dev-docs Before Compaction
When you sense context is getting long:
```
You: "/update-dev-docs"
Claude: [Updates context.md with current state, next steps]
```
### 7. After Compaction, Say "Continue"
The magic moment:
```
[Context compacted]
You: "continue"
Claude: [Reads dev docs automatically, knows exactly where you are]
```
No re-explaining. No lost context. Just continuation.
### Claude Code compaction recovery checklist
1. Stop implementation when the session begins losing exact file or decision recall.
2. Update context.md with current files, decisions, errors, and unresolved questions.
3. Mark completed and remaining work in tasks.md.
4. Confirm that plan.md still represents the approved approach.
5. Start the resumed context by loading all three files.
6. Ask Claude to state the next bounded action before editing.
The same failure mode appears at larger scale in [a 36,000-line production codebase](/blog/claude-code-production-trading-bot), where context loading and pre-compaction handoffs became operating requirements. For long agentic tasks, pair the persistence system with [model and effort-tier selection based on workload](/blog/claude-fable-5-vs-opus-4-8).
## What do the other Claude Code compaction errors mean?
The line at the top of this post is the common one, but Claude Code can stop compaction with several different messages, and they do not all have the same cause. The wording below is what the terminal prints; none of these strings appear in the official documentation, so treat the causes as observed behaviour, not a published contract.
| Message | What failed | First thing to try |
|---|---|---|
| Compaction failed · Conversation could not be reduced below the context limit | The summary itself would still not fit. The conversation holds more state than one context window can carry. | Move state into the three files above, then `/clear` and resume from them. |
| Compaction failed: Summarization failed: generation hit the token cap and the summary is incomplete | The model writing the summary ran out of output room before it finished. The conversation is too dense for one summary pass. | Run `/compact` with a focus so the summary has less to cover. |
| Compaction failed: received empty response from model, or Error during compaction: summarization produced empty response | The summarization request returned nothing. This is usually a transient request failure, not a size problem. | Retry `/compact` once. If it repeats, shrink the recent turn. |
| Prompt is too long · Automatic compaction failed: summarization produced empty response | The request to summarize was itself over the limit, so the model could not answer at all. | Clear the largest tool output, or `/rewind` and summarize only part of the session. |
| Autocompact is thrashing: the context refilled to the limit | Compaction worked, but a file or tool output refilled the window several times in a row, so Claude Code stopped retrying. | Read the oversized file in smaller chunks. |
### Summarization failed: generation hit the token cap and the summary is incomplete
This variant is the one people search for most after the main error. The summarizer is a model call like any other, and it has an output limit. When a session has many long tool results, the summary that would faithfully cover them is longer than the summarizer is allowed to write, so the pass is cut off and Claude Code refuses to replace your conversation with a partial summary.
The fix is to reduce what the summary has to hold:
1. Run `/compact` with an instruction, for example `/compact keep only the plan, the diff, and the failing test`. The official guide describes the focus form of `/compact` as the way to choose what the summary keeps.
2. Run `/rewind`, pick a message, and choose "Summarize up to here" so only the older part of the session is condensed.
3. Send large reads and log trawls to a subagent. Its output stays in a separate context window and only the result comes back.
4. If the session is already in the dev-docs workflow, run `/update-dev-docs`, then `/clear`. The files carry the state; the summary no longer has to.
### Received empty response from model, or summarization produced empty response
An empty response means the summarization request returned no text. In practice this is most often a transient failure of that one request. Retry `/compact` once before changing anything. If the empty response repeats, the most recent turn is usually the cause: one enormous tool result can push the summarization request past the limit, which is the "Prompt is too long" form of the same message. Clear that output, or ask Claude to re-read the file in a smaller range, and compact again.
### Make compaction happen earlier
Every message above appears when compaction runs late, with the window nearly full. Two documented settings move it earlier. The `autoCompactWindow` key in settings, or the `/autocompact` command, sets how full the context gets before Claude Code compacts. The `CLAUDE_CODE_AUTO_COMPACT_WINDOW` environment variable and the `--autocompact` flag override it for one session. Compacting at a lower fill leaves the summarizer room to finish.
If the problem is the window size rather than the session shape, the current Fable, Sonnet 5, and Opus models run with a one million token context window on the Anthropic API, and older models take the `[1m]` suffix in `/model`. The official model configuration page lists availability by plan. Compaction works the same way at the larger limit, so the three files still matter; the larger window only delays the point at which they are needed.
To check whether long sessions and compaction are where your own plan usage goes, the free Claude Code Runway Audit reads the token counts in your local transcripts and reports how often your sessions hit compaction. It runs on your machine and sends nothing anywhere.
## How Does Multi-Root Workspace Structure Help?
Multi-root workspace structure separates context by repository so frontend knowledge doesn't pollute backend work. Each repo holds its own claude.md for repo-specific instructions, a PROJECT_KNOWLEDGE.md for architecture details, and a TROUBLESHOOTING.md for recurring issues. Claude reads only the files relevant to your current work, keeping context lean and accurate.
For projects with multiple repos:
```
~/git/project/
├── CLAUDE.md # Root config (~100 lines)
├── dev/active/[task-name]/ # Dev docs location
├── frontend/
│ ├── claude.md # Repo-specific (50-100 lines)
│ ├── PROJECT_KNOWLEDGE.md # Architecture details
│ └── TROUBLESHOOTING.md # Common issues
└── backend/
└── ...
```
Each repo has its own context files. Claude reads the relevant ones based on which files you're working with.
Benefits:
- **Separation of concerns**: Frontend context doesn't pollute backend work
- **Reusable knowledge**: PROJECT_KNOWLEDGE.md persists across sessions
- **Troubleshooting history**: Common issues documented once, used forever
## What Do the 16 Automation Hooks Do?
The 16 automation hooks enforce workflow quality without manual intervention. UserPromptSubmit analyzes prompts and activates relevant skills. PreToolUse validates operations before they run. PostToolUse logs every file change. Stop-BuildChecker runs builds automatically on modified repos. Stop-ErrorReminder scans for missed error patterns. Together they catch problems throughout the session without any extra commands. Context-switching is especially costly with ADHD; the [Claude Code workflow for ADHD brains](/blog/claude-adhd-executive-function-mode) builds this persistence in from the start.
Hooks enforce the workflow without manual intervention:
The pipeline runs automatically. You just work. The system catches problems.
## When Should I Skip Dev Docs?
Skip dev docs for quick questions, simple single-line fixes, and one-off tasks that fit entirely in a single conversation. Use them for any task taking more than 30 minutes, work spanning multiple sessions, complex features touching multiple files, or anything you would hate to re-explain from scratch after a context compaction event.
Not every task needs the full workflow:
**Skip for:**
- Quick questions ("How do I X?")
- Simple fixes (typo, single-line change)
- One-off tasks that fit in one conversation
- Exploration without implementation
**Use for:**
- Any task taking more than 30 minutes
- Multi-session work
- Complex features with multiple files
- Anything you'd hate to re-explain
The overhead of creating dev docs pays off the first time you avoid context loss.
## Context Loss Cost: Before vs. After Dev Docs
These are my actual numbers from 6 months of Claude Code use on a multi-repo SvelteKit project with 16 hooks configured.
| Metric | Without Dev Docs | With Dev Docs |
|---|---|---|
| Time lost to context re-build per session | 20-30 min | 0-2 min |
| Sessions hitting compaction (per week) | 4-6 | 4-6 |
| Total weekly re-explanation overhead | 80-180 min | 0-12 min |
| Decision drift (re-debating settled choices) | Weekly | Rare |
| "Gun-blazing" implementation incidents | 2-3/week | 0-1/month |
| Setup cost | 0 | 30 min (one-time) |
The break-even is a single session with compaction. After that, dev docs are pure time savings. The 30-minute setup has paid back over 60 hours since I built it.
## How Do I Get Started?
Start with the minimum viable setup: create a dev/ directory in your project root, create template files for plan, context, and tasks, then add 'continue' handling to your CLAUDE.md so Claude knows to read dev docs on that command. The full setup with hooks and workspace structure adds a few more hours but pays off quickly.
### Minimum Viable Setup
1. **Create a dev/ directory** in your project root
2. **Create template files** for plan, context, tasks
3. **Add "continue" handling** to your CLAUDE.md:
```markdown
## On "continue" command
1. Check for dev/active/*/context.md
2. Read the most recent context file
3. Resume from documented state
```
### Full Setup
1. **Install the dev docs commands** (slash commands or aliases)
2. **Configure hooks** for automatic skill activation
3. **Set up build checking** on Stop events
4. **Create workspace structure** for multi-repo projects
The full system takes a few hours to configure. But it saves that time on every long task thereafter.
## FAQ: Context Management for Claude Code
The questions below cover context compaction, dev doc setup, and when to use the workflow. Short answers are here. The sections above have the full implementation detail.
**What is context compaction in Claude?**
When conversations get too long, Claude summarizes older messages to free up space. This 'compaction' loses details: specific decisions, file paths, progress state. The AI continues but forgets what you already discussed.
**What are dev docs in Claude Code workflow?**
Dev docs are three files created for each task: plan.md (approved implementation plan), context.md (key files, decisions, current state), and tasks.md (checklist of work items). They persist outside the conversation.
**How does the dev docs workflow prevent context loss?**
Before compaction, run /update-dev-docs to save current state. After compaction, say 'continue' and Claude reads the dev docs automatically, picking up exactly where you left off with full context.
**When should I use dev docs vs regular conversation?**
Use dev docs for any task taking more than 30 minutes or spanning multiple sessions. Skip for quick questions, simple fixes, or one-off tasks that fit in a single conversation.
**How do 16 automation hooks fit into this workflow?**
Hooks automate quality control throughout: UserPromptSubmit activates skills, PostToolUse tracks file edits, Stop-BuildChecker runs builds automatically, Stop-ErrorReminder checks for missed errors. They enforce the workflow without manual intervention.
**What does "summarization failed: generation hit the token cap" mean?**
The model writing the compaction summary ran out of output room before it finished, so Claude Code refused to replace the conversation with a partial summary. Run /compact with a focus instruction, summarize only part of the session with /rewind, or save state to dev docs and /clear.
**Why does compaction say "received empty response from model"?**
The summarization request returned no text. It is usually a transient request failure, so retry /compact once. If it repeats, the most recent turn is probably too large; clear the big tool output or re-read the file in a smaller range, then compact again.
---
## The Failure That Caused This
The dev docs system came from a 3-hour session that hit compaction and lost everything: JWT vs. session decision, token lifetimes, cookie configuration. Claude resumed with a completely different approach. I spent 45 minutes reconstructing decisions I had already made. That night I built the first version of the system.
The context amnesia problem came to a head on a specific afternoon.
I was 3 hours into implementing a multi-step authentication flow. We'd made specific decisions: JWT over sessions, 15-minute access tokens, httpOnly cookies, no third-party auth libraries. All of this was in conversation history.
Then context compaction hit.
I typed "continue" and Claude started implementing. A completely different approach. Sessions instead of JWT. localStorage instead of cookies. Not because it was ignoring my instructions. It genuinely didn't have them anymore.
I spent 45 minutes figuring out what had changed and re-explaining the decisions we'd already made. Some of those decisions were subtle. The 15-minute token lifetime had a specific reason tied to our security requirements. I had to reconstruct the reasoning from scratch.
That night I built the first version of the dev docs system. Three files, 30 minutes to set up. The next session I ran into compaction again. This time I typed "continue" and Claude picked up exactly where we were. The cookies decision. The token lifetime. The files already modified. All of it.
The 30-minute setup has paid off dozens of times since. Context compaction is still annoying. But it's no longer a crisis.
I thought I could just re-prompt after compaction. Well, it's more like... I thought my memory was the backup, when I needed an actual backup.
Maybe the goal isn't longer context windows. Maybe it's better context persistence: systems that make "we already discussed this" impossible to say. Retrieval-augmented approaches are another direction entirely; the [RAG research by Lewis et al.](https://arxiv.org/abs/2005.11401) explores how external knowledge retrieval can supplement limited context windows.
## Advanced Patterns: Context Files for Different Work Types
The three-file structure is the baseline. For complex or long-running projects, these variants handle situations the baseline doesn't cover.
### API Design Work
When working on API design (endpoints, data schemas, contracts), context.md needs different sections than implementation work.
Add a **current endpoint inventory**: list every endpoint you've defined or are working toward with method, path, and status (designed, implemented, tested). This prevents the duplication problem where you design an endpoint in session one and Claude proposes a slightly different version in session three because it doesn't know the first one exists.
Add a **schema decisions** section: capture data shape choices and the reason for them. "Using string for userId instead of number, consistent with Clerk's user IDs" takes five seconds to write and prevents an hour of confusion when Claude suggests integer IDs.
### UI and Component Work
For frontend work, tasks.md needs visual acceptance criteria, not just functional ones. Add a column: "Visual check: [what it should look like at mobile/desktop]." This forces you to define the visual bar before implementation, not after.
Also add a **design decisions** section to context.md: color tokens used, responsive breakpoints that apply to this component, and any interaction states (hover, focus, disabled) that need to be handled. These are the details that get lost between sessions and cause inconsistency.
### Multi-Session Bug Investigation
Bugs that take more than one session to diagnose need a different structure. Replace plan.md with **investigation.md**: a hypothesis log. List every hypothesis you've tested, what you tried, and what you learned. "Hypothesis: race condition in auth middleware. Tested with logs. Result: not the issue. Logs show auth completes before the error."
This prevents testing the same hypothesis twice across sessions. It is more common than it sounds when you're working on a complex bug over several days.
Keep context.md but focus it on the error signature: exact error message, stack trace, files involved, reproduction steps. Update it every session with what changed.
### Team Projects
When multiple people work with the same context files, context.md needs a contributor section: "Last updated by [name], [date], summary of changes." This isn't bureaucracy. It's the minimum information that prevents one person from undoing another's documented decisions.
Also agree on update frequency. Individual projects, you update whenever it's useful. Team projects, agree on a rule: "update before ending every session involving more than one file change." Shared files need shared maintenance norms.
The baseline three-file structure handles 80% of sessions. These patterns handle the other 20%: the long-running, multi-person, investigative, and visually-complex work where the baseline creates gaps.
---
## What Happens at 38,000 Lines: Context Collapse at Scale
At around 15,000 lines, my trading bot stopped fitting in Claude's context window in any useful way. The model started hallucinating function signatures from files it couldn't see and citing methods that had been renamed three refactors ago. The tutorials show you the 500-line project; nobody writes about what happens at 38,000 lines in production.
Context collapse doesn't announce itself. You notice it when Claude starts being confidently wrong about your own code: suggesting imports that don't exist, referencing variables from a module you restructured two weeks ago. The model isn't hallucinating in the general sense; it's confabulating from stale partial context. Deep call graphs make it worse: showing Claude the execution layer in isolation means it's reasoning about a system it can't actually see, and it fills the gaps plausibly, which is the dangerous part.
Three disciplines that held at scale, beyond the three-file baseline:
**Scoped entry points, not file dumps.** Enter via a narrow question with a named scope: "In `signal_processor.py`, `calculate_momentum` returns negative values on gap-up candles," with three files attached, maximum. If I can't describe the problem in one sentence with three files or fewer, I haven't isolated the problem yet. The constraint is a forcing function for clarity.
**Checkpoint commits as context anchors.** Every meaningful working state gets a commit message a model could read cold: `refactor: move position sizing to RiskManager, remove from ExecutionEngine`, never `fix thing`. Starting a new session, `git log --oneline -10` carries more semantic load than a paragraph of explanation.
**Architecture written before code.** If I were starting today: write the context map before the first module, and keep modules shallower than feels right. Deep call graphs are context expensive; flat modules with explicit interfaces are easier to scope into a session. The bot's most maintainable subsystem is the one kept under 400 lines with clean input/output contracts.
The honest limit: context discipline extends your range, it doesn't eliminate the problem. At 38,000 lines you start making architectural tradeoffs specifically to manage model context. Subsystems a human engineer might integrate stay separated partly because separation makes them easier to work on with Claude. That's a property of the workflow, not a bug, and knowing it's a property means you can design around it.
---
## Related Reading
This is part of the [Complete Claude Code Guide](/blog/claude-code-complete-guide). Continue with:
- [Quality Control System](/blog/how-i-build-with-claude-code) - Two-gate enforcement that blocks "should work"
- [Evidence-Based Verification](/blog/ai-code-verification-evidence-based) - Why confidence without proof fails
- [Token Optimization](/blog/reduce-ai-token-usage-progressive-disclosure) - Save 60% with progressive disclosure
- [Deploy Your Agent on DigitalOcean](/blog/deploy-python-agent-digitalocean) - VPS setup in 5 steps for $6/month
---
`WORK WITH ME · CONTEXT DISCIPLINE, INSTALLED`
> The 3-file system here is the manual version, and every teammate has to remember to run it. I build custom Claude Code pipelines, $2,000 to $5,000, that wire context persistence, verification gates, and session discipline directly into your repo so the whole team gets it automatically, not by habit. [See how the engagement works](/services).
--- END POST ---
================================================================================
POST: Flat-Rate vs Usage-Based SaaS Pricing: Why I Chose Flat
================================================================================
URL: https://chudi.dev/blog/flat-rate-vs-per-file-saas-pricing
Date: 2026-01-17T00:00:00.000Z
Tags: saas, pricing, strategy, startup, business
Pillar: philosophy
Reading Time: 9 min
Word Count: 1629
TL;DR: Competitors charge $0.25-1.00 per bank statement. For a bookkeeper processing 100 statements monthly, that's $25-100/month with no ceiling. StatementSync charges $19/month flat for unlimited processing. Heavy users save money and become your most loyal customers. The key insight: when your runtime cost is near-zero (pattern-based extraction), flat-rate pricing is a competitive weapon.
Key Takeaways:
- Per-file pricing punishes your best customers, heavy users pay the most despite being most committed
- Flat-rate attracts high-volume users who become loyal because switching means losing unlimited value
- Only works when runtime costs are near-zero, LLM-based extraction would make flat-rate unprofitable
- Competitors anchored to per-file pricing can't easily switch without alienating their existing customer base
- Predictable costs reduce purchase friction, users know exactly what they'll pay before signing up
--- CONTENT ---
Flat-rate pricing selects committed heavy users who become loyal because switching to per-file immediately costs them more once their usage volume scales. StatementSync charges $19 per month flat while competitors charge $0.25-1.00 per statement: a bookkeeper processing 100 statements monthly saves $6-81 per month and has no reason to leave.
Every PDF-to-Excel tool charges per file. TextSoap: $0.50/statement. HappyFox: $0.25/statement. Bank statement converters on Zapier: $1.00/statement.
StatementSync charges $19/month. Unlimited statements.
This isn't underpricing, it's strategy.
## The SaaS Pricing Landscape
Most SaaS products pick from three models:
**Per-unit (pay-as-you-go):** Charge per API call, per file, per transaction. You earn proportionally to usage. Customers pay only for what they use, which lowers entry friction but keeps every transaction a mini purchase decision.
**Per-seat:** Charge per user per month regardless of usage. Works for collaboration tools where value scales with team size. Breaks down when one heavy user needs unlimited access but the team has dozens of light users.
**Flat-rate (all-you-can-eat):** One price for unlimited usage within a tier. Removes friction for heavy users. Requires near-zero marginal cost to stay profitable.
There's also [usage-based pricing](https://stripe.com/docs/billing/subscriptions/usage-based) (AWS-style: pay exactly for what you consume) and hybrid models (base fee + overage charges). Most B2B SaaS ends up somewhere between per-seat and flat-rate.
StatementSync chose flat-rate deliberately, not because it's simpler, but because the economics made it possible and the competitive landscape made it powerful.
## The Per-File Problem
Per-file pricing makes sense on the surface:
- Simple to understand
- Aligns cost with value
- Easy to implement
But it punishes your best customers.
A bookkeeper processing 50 statements monthly pays $12.50-50/month at competitor rates. That's reasonable. But they're not your best customer, they're testing the waters.
Your best customer processes 200 statements monthly. At $0.25/file, they pay $50/month. At $0.50/file, they pay $100/month.
**The more committed they are, the more they pay.**
Per-file pricing creates incentive to minimize usage. Heavy users constantly evaluate whether each statement is "worth" the fee. They're never fully committed because every use is a new purchase decision.
## The Flat-Rate Advantage
With flat-rate pricing, the dynamics flip:
**Light users** (10 statements/month): Pay $19 for $2.50-5 worth of per-file value. You're expensive for them, and that's fine. They're not your target.
**Heavy users** (100+ statements/month): Pay $19 for $25-100 worth of per-file value. You're a steal. They'll never leave.
Heavy users become your most loyal customers because:
1. They're getting the best deal
2. Switching means losing unlimited value
3. They recommend you to other heavy users
## The Economics
This only works because extraction costs are near-zero.
```
Per-file competitors:
Revenue per statement: $0.25-1.00
Processing cost: $0.01-0.05 (if using LLM)
Margin: $0.20-0.95
StatementSync:
Revenue per user: $19/month
Processing cost: ~$0 (pattern-based)
Margin: ~$19/month
Break-even point:
If competitor charges $0.25/file
StatementSync breaks even at 76 statements/month
Heavy users easily exceed this
```
Pattern-based extraction costs nothing at runtime. No LLM API calls, no per-document compute costs. This is what makes flat-rate pricing viable.
If I used LLM extraction (GPT-5 at $0.01-0.05 per statement), flat-rate would be suicide. A heavy user processing 500 statements would cost me $5-25/month in API fees against $19 revenue.
The tech decision (pattern-based vs LLM) enabled the pricing strategy. That architectural choice was made by [MicroSaaSBot's Architect agent](/blog/introducing-microsaasbot-ai-builds-saas), a case study in how technical decisions compound into business strategy.
### Month 1 Reality Check
After launching at $19/month, the first month of data:
- Average user processed 67 statements in month one
- Break-even against $0.25/file pricing: 76 statements
- Break-even against $0.50/file pricing: 38 statements
Most users were below break-even in month one. That's expected, bookkeepers onboard cautiously. By month three, the median user was at 112 statements/month, solidly in "StatementSync is a steal" territory.
The churn from light users (under 30 statements/month) was higher than expected. That's also fine. Light users were never the target. The goal was making the heavy users, serious full-time bookkeepers, feel like they'd found a permanent tool. Those users have the lowest churn because switching to per-file pricing would immediately cost them more money.
## Competitor Lock-In
Competitors can't easily match flat-rate pricing:
**TextSoap scenario:**
- Current customers expect $0.50/file
- Light users are profitable at this rate
- Switching to flat-rate means:
- Losing revenue from light users
- Explaining a business model change
- Competitors attacking your transition confusion
**The anchoring problem:**
Their brand is built on per-file pricing. Their support, onboarding, and documentation assume per-file. Changing is a rebranding exercise, not just a pricing change.
New entrants (like StatementSync) can position as "the unlimited one" from day one. No legacy baggage.
## The Psychology
Per-file pricing creates friction at every use:
- "Is this statement worth $0.50?"
- "Should I batch these for later?"
- "Maybe I'll just do this one manually..."
Flat-rate removes the decision:
- "I have unlimited. I'll process everything."
- No mental math before each use
- No anxiety about costs growing
Users with predictable costs are happier users. They budget $19/month and never think about it again. That's the relationship you want. [ProfitWell's pricing research](https://www.paddle.com/resources/saas-pricing-models) consistently shows that pricing anxiety, not product quality, is a leading driver of churn in subscription businesses.
## When Flat-Rate Fails
Flat-rate doesn't work for every SaaS:
**High marginal cost products:**
- AI image generation (compute per image)
- Data storage (cost scales with data)
- API aggregation (pass-through costs)
**B2C with wide usage variance:**
- Casual users dominate
- Power users rare but massively heavy
- Flat-rate either overcharges casuals or under-serves power users
**Enterprise with unpredictable usage:**
- Massive organizations with unknown scale
- Per-seat or usage-based often better
StatementSync works because:
1. B2B with predictable personas
2. Near-zero marginal cost
3. Usage correlates with commitment (heavy users = serious bookkeepers)
## The Result
StatementSync's positioning:
| Factor | Per-File Competitors | StatementSync |
|--------|---------------------|---------------|
| Light user cost | $2.50-10/month | $19/month |
| Heavy user cost | $50-100+/month | $19/month |
| Customer loyalty | Low (every use is a decision) | High (unlimited = committed) |
| Referrals | From light users (low value) | From heavy users (high value) |
The pricing strategy determines the customer base. Per-file attracts price-sensitive light users. Flat-rate attracts volume-committed heavy users.
I'd rather have 100 heavy users at $19/month than 500 light users at $5/month. The heavy users stay longer, refer more, and care more about the product.
## Is Flat-Rate Right for Your Product?
Flat-rate pricing works when your marginal cost per unit is near zero, your target persona is a heavy user, abuse cases are manageable, and the value proposition is immediately obvious. For products with real per-usage costs like LLM API calls or compute-intensive processing, flat-rate becomes unprofitable before heavy users reach break-even volume.
Four questions to work through before committing to flat-rate pricing:
**1. What is your marginal cost per unit of usage?**
Pattern-based extraction: ~$0. LLM extraction at $0.01–0.05/call: flat-rate becomes dangerous above ~380 units/month at $19 revenue. Storage-intensive products (large file processing, video) face the same math. Calculate your worst-case heavy user scenario before setting a price.
**2. Is your target persona a heavy user?**
Flat-rate attracts heavy users. If your persona uses the product once a week casually, they'll calculate that per-unit pricing is cheaper and choose that. You need a persona that processes enough volume to feel the unlimited plan is genuinely better value, bookkeepers, power users, agencies, ops teams.
**3. Can you identify and handle abuse cases?**
True abuse (processing 10,000 statements for $19) is rare in B2B, most buyers are professionals with legitimate use. But you should have a policy. StatementSync has a fair-use clause: commercial resellers need to contact sales. No bookkeeper ever hit this.
**4. Is the differentiation story clear?**
"Unlimited for $19" needs to be instantly understandable and obviously better than "pay per file." If the math isn't obvious to your target user, the positioning won't land. Test the message before building the pricing.
If you answer these four favorably, low marginal cost, heavy-user persona, manageable abuse risk, clear positioning, flat-rate pricing is likely a competitive weapon, not just a pricing model. StatementSync's validation process confirmed all four before any code was written, the scoring system is in [MicroSaaSBot's idea validation framework](/blog/introducing-microsaasbot-ai-builds-saas).
## What Flat-Rate Does to Churn
Per-file pricing and flat-rate pricing have fundamentally different churn dynamics.
With per-file pricing, engagement is invisible. A bookkeeper who processes 5 statements in January and 50 in February looks like the same account in your billing system, revenue goes up, but you don't know why. When they cancel, you see it. You don't see the months they were barely using the product.
With flat-rate, usage patterns are visible from day one. Every login, every upload, every export is a signal. Heavy users engage consistently. Light users log in, process one or two statements, and either upgrade their habits or churn within 60 days.
This makes flat-rate pricing better for product development decisions. After three months of StatementSync data, I could clearly see that batch upload (20 files at once) was the feature heavy users wanted most. They asked for it directly in support messages. Per-file pricing would have obscured this, heavy users on per-file are price-sensitive, so they minimize processing. Heavy users on flat-rate have no reason to minimize usage. They process everything and ask for tools that make processing faster.
Flat-rate surfaces your most engaged users. Engaged users tell you what to build next. Per-file surfaces price sensitivity, which tells you nothing about what would make your product better.
The counterintuitive result: flat-rate pricing generates better product insight, not just better retention. The revenue model and the feedback loop compound together.
## The Lesson
Pricing isn't just about covering costs and adding margin. It's about selecting your customers. As [Stripe's billing documentation](https://stripe.com/docs/billing/subscriptions/overview) notes, the pricing model you choose shapes the entire customer relationship, not just the revenue line.
Flat-rate selects for commitment. Per-file selects for caution.
Choose your customers by choosing your pricing.
---
**Related**: [From Pain Point to MVP: StatementSync in One Week](/blog/introducing-microsaasbot-ai-builds-saas) | [Portfolio: StatementSync](/portfolio/statementsync)
--- END POST ---
================================================================================
POST: My Two-Gate System for Claude Code Cut Errors 84%
================================================================================
URL: https://chudi.dev/blog/how-i-build-with-claude-code
Date: 2026-01-17T00:00:00.000Z
Tags: claude-code, ai, workflow, automation, quality-control
Pillar: ai-building
Reading Time: 12 min
Word Count: 2317
TL;DR: I shipped broken code three times in one week. Not edge cases, fundamental errors. Without me realizing it, I was trusting confidence over evidence. The two-gate system I built blocks all implementation until Gate 0 (meta-orchestration) and Gate 1 (skill activation) pass. Well, it's more like enforced honesty. 'Should work' is banned.
Key Takeaways:
- Gate 0 loads meta-orchestration and validates context budget (<75%) before any tools unlock
- Gate 1 activates relevant skills based on query patterns, ensuring the right tools are loaded
- Red flag phrases ('should work', 'probably fine') are blocked and require actual verification evidence
- Progressive disclosure saves 60% tokens by loading skill metadata first, full content on demand
- The system enforces quality through hooks, not willpower. Tools literally cannot execute until gates pass
--- CONTENT ---
I shipped broken code three times in one week. Not edge cases--fundamental errors that any test would have caught. The AI said "should work" and I believed it. The complete Claude Code workflow this two-gate system fits inside is in [Claude Code: A Complete Guide](/blog/claude-code-complete-guide); this post is the quality-gate slice of that workflow.
Building a quality control system for AI code generation means enforcing mandatory gates before implementation begins--loading relevant skills, validating context budget, and blocking rationalization phrases like "should work" that indicate unverified claims. The result is a two-gate system where tools literally cannot execute until quality checks pass. [Claude Code](https://docs.anthropic.com/en/docs/claude-code/overview) provides the hooks infrastructure that makes gate enforcement possible at the session level.
## Why Did I Need Quality Gates for AI?
Quality gates for AI code generation became necessary because unverified confidence phrases like "should work" replaced actual verification. Without mandatory checks, AI generates code that appears correct but breaks in fundamental ways. The gate system enforces evidence-based completion by blocking implementation tools until context is validated and the right skills are loaded.
The problem wasn't the AI's capability. [Claude](https://www.anthropic.com) is remarkably good at generating code. The problem was my workflow--or lack of one.
I'd describe what I wanted. Claude would write it. I'd paste it in. Sometimes it worked. Sometimes I'd spend hours debugging issues that existed from the first line. Without me realizing it, I was trusting confidence over evidence.
That specific anxiety of deploying something you haven't tested--the kind where you refresh the page three times hoping the error goes away--became my default state.
Well, it's more like... I was using AI as a code generator when I needed it to be a quality-controlled collaborator.
## How Does the Two-Gate System Work?
The two-gate system runs two mandatory checks before any tool can execute. Gate 0 loads meta-orchestration and validates your context budget stays below 75%. Gate 1 analyzes your query and activates the relevant skills from a library of 30 or more defined patterns. Both must pass before implementation begins.
The system enforces two mandatory checks before any tool can execute. Like buttoning a shirt from the first hole--skip it, and everything else is wrong.
If either gate fails, all implementation tools are blocked. You literally cannot write code until the orchestration layer is ready.
### Gate 0: Meta-Orchestration (Priority 0)
This gate loads immediately and handles three things:
Validates you're under 75% context usage. If you're running hot on tokens, the system warns you before you hit the wall.
Sets up phrase blocking and evidence requirements. The guardrails that make "should work" impossible to say.
Loads the SKILL.md entry point (~200 tokens). Just enough context to route your query.
### Gate 1: Auto-Skill Activation (Priority 1)
This gate analyzes your query and activates relevant skills:
Parses keywords, file patterns, and task type from your query.
Scores against 30+ defined skills using a weighted algorithm.
Applies context boosters and calculates activation thresholds.
Activates top 5 skills: Tier 1 (score ≥50) immediately, Tier 2 (≥30) on first tool use, Tier 3 (≥10) on request.
I love automation. But I spend hours building systems to slow myself down.
## What Is Progressive Disclosure and Why Does It Save 60% of Tokens?
Progressive disclosure loads skill content in three tiers instead of all at once. Tier 1 loads metadata at roughly 200 tokens, Tier 2 loads schemas at 400 tokens, and Tier 3 loads full handler logic at 1,200 tokens only when needed. Sessions that never reach Tier 3 save 60% of their token budget.
Most Claude configurations load everything upfront. Every skill, every rule, every example--thousands of tokens consumed before you've even asked a question. [Anthropic's documentation](https://docs.anthropic.com) covers prompt and context design patterns that help avoid this upfront token burn.
Progressive disclosure flips this. Load metadata first. Load details on demand.
### The 3-Tier System
**Tier 1: Metadata (~200 tokens)**
- Skill name, triggers, dependencies
- Just enough to route the query
**Tier 2: Schema (~400 tokens)**
- Input/output types
- Constraints and quality gates
- Tools available
**Tier 3: Full Content (~1200 tokens)**
- Complete handler logic
- Examples and edge cases
- Only loaded when actively using the skill
The meta-orchestration skill alone: 278 lines at Tier 1, 816 with one reference, 3,302 fully loaded. That's 60% savings on every session that doesn't need the full content.
## What Phrases Does the System Block?
The system blocks phrases that indicate claims without evidence: "should work," "probably fine," "I'm confident," "looks good," and "all set." These phrases are banned not because they are wrong, but because they signal unverified assumptions. Blocking them forces the path of least resistance to be actual build output or test results.
The automated verification system flags specific patterns in code comments and commit messages. Here's the complete breakdown of phrases that indicate insufficient testing or assumptions:
These phrases aren't banned because they're wrong. They're banned because they indicate claims without evidence.
The goal isn't to be pedantic--it's to make evidence the path of least resistance. When "build passed" is easier to say than "should work," you'll naturally verify before claiming.
That hollow confidence of claiming something works without checking--the system makes it impossible.
## How Does AMAO Handle Parallel Execution?
AMAO uses a directed acyclic graph engine to map task dependencies and identify which operations can run concurrently. It runs up to three concurrent tasks with a five-minute timeout and falls back to sequential execution if parallel fails. A context governor tracks token usage and triggers auto-compaction at 70% to prevent overflow.
AMAO (Adaptive Multi-Agent Orchestrator) adds sophisticated orchestration on top of the gate system:
### DAG Engine
- Directed acyclic graph for task dependencies
- Max 50 tasks with cycle detection
- Parallel grouping for independent operations
- Critical path analysis for optimization
### Context Governor
- 75% max budget, 60% warning threshold, 20% reserve
- Predictive usage analysis
- Auto-compact at 70%
- Phase unloading to release memory between stages
### Skill Evolution
- Pattern detection: 5 occurrences triggers skill proposal
- Auto-approval at 85% confidence
- Deprecation at 30% effectiveness
- Weighted feedback: 40% build, 30% test, 20% reverts, 10% user
The parallel execution runs up to 3 concurrent tasks with a 5-minute timeout. If parallel fails, it falls back to sequential--safety over speed.
## What Are the 4 Pillars of Quality?
The four pillars are state and reactivity, security and validation, integration reality, and failure recovery. State enforces Svelte 5 runes only. Security validates all user input. Integration reality requires every component to be used in at least one route. Failure recovery mandates error boundaries and graceful degradation on all async operations.
Every check maps to one of four pillars:
### 1. State & Reactivity
- Svelte 5 runes only (`$state`, `$props`, `$derived`)
- No legacy patterns that cause confusion
- State updates via `$effect` for side effects
### 2. Security & Validation
- All user input sanitized (XSS prevention)
- Form inputs validated with Zod
- API routes validate request schema
- No inline scripts in production
### 3. Integration Reality
- Every component used in at least one route
- No orphaned utility files
- All API routes consumed by UI
- Every feature has verification
### 4. Failure Recovery
- Error boundaries on all route groups
- Graceful degradation for failed API calls
- Loading states for async operations
- User-friendly error messages
## FAQ: Building Quality Systems for AI Code Generation
**What is a two-gate system for AI code generation?**
A two-gate system enforces quality checks before any implementation begins. Gate 0 loads meta-orchestration and validates context budget. Gate 1 activates relevant skills based on your query. Both must pass before tools are unblocked.
**How much do token savings matter with progressive disclosure?**
Progressive disclosure saves 60% of tokens by loading skill metadata first (~200 tokens), then schemas on demand (~400 tokens), then full content only when needed (~1200 tokens). This prevents context overflow on long sessions.
**Why block phrases like 'should work' in AI development?**
Phrases like 'should work' and 'probably fine' indicate unverified claims. Blocking them forces evidence-based completion--actual build output, test results, or screenshots before marking work complete.
**Can I implement this system for my own Claude Code setup?**
Yes. Start with a CLAUDE.md file that enforces gate checks. Add hooks for UserPromptSubmit (skill activation) and Stop (build verification). The meta-orchestration plugin pattern works for any codebase.
**What's the difference between AMAO and Cortex 2.0?**
AMAO handles orchestration--parallel execution, context budgeting, skill evolution. Cortex 2.0 handles skill definitions with 3-tier progressive disclosure. They work together: AMAO decides what to run, Cortex defines how skills work.
---
## What Changed After 6 Months
Six months of running this system daily taught me things I couldn't have predicted from theory alone.
The first surprise: phrase blocking changes how you think, not just what you say. After a few weeks, I stopped forming sentences like "this should work" internally. The habit of reaching for evidence replaced the habit of reaching for confidence. That's not something I expected from a text filter.
The second surprise: Gate 1 skill activation catches mismatches I didn't know were happening. I'd ask about a database query and Claude would activate the wrong skill--something frontend-adjacent because I'd mentioned a component in the same message. The gate surfaces that mismatch immediately. Without it, I'd get a halfway answer and not know why.
The third lesson: the 75% context budget threshold is exactly right, and I didn't trust it at first. I kept thinking "I have 30% left, that's fine." Then I'd hit context compaction 15 minutes later in the middle of implementation. The system wasn't being conservative. I was being optimistic about how much context finishing a feature actually consumes.
After 6 months, my ratio of "it worked first time" to "spent 2 hours debugging" has roughly flipped. Not because Claude got better. Because I stopped accepting "should work" as a completion state.
The hardest part was admitting the problem was my workflow, not the AI's capability. Once I accepted that, building the gates was easy.
I thought I needed better prompts. Well, it's more like... I needed better systems around the prompts. The AI was always capable. I just needed guardrails that made "should work" impossible to say.
Maybe the goal isn't to trust AI more. Maybe it's to trust evidence--and build systems that make evidence the only path forward.
## Adapting the Gates to Different Project Types
The two-gate system was built for a specific project, a SvelteKit blog. The principles generalize, but the implementation details vary.
### Bug Fixes vs. New Features
For bug fixes, Gate 1 skill activation should weight debugging skills higher than implementation skills. The mental model shift: you're investigating, not building. That difference matters because investigation and implementation have different quality criteria.
For a bug fix, "complete" means: the bug no longer reproduces, a test catches the regression, and the root cause is documented in context.md. Not "the code looks right."
For new features, "complete" means: the feature works end-to-end in the happy path, edge cases are documented and handled, and the build passes with types. A feature that "looks right" is in the same category as "should work."
The gate isn't different, evidence over confidence in both cases, but what counts as evidence is.
### Refactoring Sessions
Refactoring is where the gate system earns its keep most visibly. The failure mode for AI-assisted refactoring is: Claude refactors the code, the surface behavior looks the same, but something subtle broke in a path you didn't test.
Before any refactoring session, add one step to Gate 0: document the current behavior you need to preserve. Not informally, write it in context.md. "This function should return null for missing users, not throw. The calling code depends on null, not an exception."
After refactoring, verify that exact behavior explicitly. Don't trust that "the tests pass" if you don't have a test for the specific behavior you documented. If the behavior isn't tested, write the test first, confirm it passes in the original code, then refactor.
### Exploratory Sessions
Some sessions are genuinely exploratory, you're trying to understand an unfamiliar codebase, evaluate a new library, or figure out why something is slow. These sessions don't naturally fit the gate structure because there's no implementation to gate.
For exploratory sessions: skip Gate 1 skill activation and run with a single constraint, everything you learn goes into context.md in real time. Exploration without capture is entertainment.
At the end of an exploratory session, convert your notes into hypotheses for the next session. "Learned: the bottleneck is in the database query at line 45. Hypothesis: adding an index on user_id will fix it. Test this in the next session."
This closes the loop between exploration and implementation, which is the gap where insights evaporate.
### Short Projects vs. Long Projects
Short projects (one to three sessions): use the gate system for quality control, skip the full dev docs workflow. One context file with the current state is enough.
Long projects (weeks to months): invest in the full dev docs structure. The overhead of maintaining three files pays off by session four, when the project would otherwise require full context rebuilds at the start of every session. If task initiation or context-switching is the hard part, I wrote up the [ADHD version of this Claude Code workflow](/blog/claude-adhd-executive-function-mode) separately.
The gate system is not overhead. It's the minimum viable quality control. Don't scale it down below the gate check, that's where the broken-code problem that started this whole system lives.
---
## Related Reading
This is part of the [Complete Claude Code Guide](/blog/claude-code-complete-guide). Continue with:
- [Context Management](/blog/claude-context-management-dev-docs) - Dev docs workflow that prevents context amnesia
- [Evidence-Based Verification](/blog/ai-code-verification-evidence-based) - Why "should work" is the most dangerous phrase
- [Token Optimization](/blog/reduce-ai-token-usage-progressive-disclosure) - Save 60% with progressive disclosure
- [What is RAG?](/blog/what-is-rag) - Foundational concept behind context-aware AI
--- END POST ---
================================================================================
POST: How to Optimize Your Website for ChatGPT and Perplexity
================================================================================
URL: https://chudi.dev/blog/how-to-optimize-for-perplexity-chatgpt-ai-search
Date: 2026-01-17
Tags: seo, ai, perplexity, chatgpt, content-optimization
Pillar: ai-building
Reading Time: 11 min
Word Count: 2107
TL;DR: To optimize for Perplexity, ChatGPT, and Claude, you need crawl access, explicit AI crawler permissions, and answer-first formatting with schema. This guide lays out the exact steps: robots.txt, llms.txt, structured data, and content structure.
Key Takeaways:
- Allow AI crawlers in robots.txt and publish llms.txt for attribution.
- Use sitemap and RSS to help answer engines discover updates.
- Add BlogPosting and FAQ schema to priority posts first.
- Lead with answers and structured headings to improve extraction.
--- CONTENT ---
To allow ChatGPT, Claude, and Perplexity to crawl your site and cite it, make five concrete changes: crawler access in robots.txt for GPTBot, ClaudeBot, and PerplexityBot, an llms.txt file, schema markup, answer-first content structure, and fresh high-value pages. If they cannot crawl or parse your site, they cite a competitor instead, and that buyer never sees you. This guide walks through each step and how to verify it worked.
## How Do You Optimize a Website for ChatGPT and Perplexity?
To optimize your website for ChatGPT and Perplexity, do five things in order: allow their crawlers (GPTBot, ClaudeBot, PerplexityBot) in `robots.txt`, publish an `llms.txt` attribution file, add BlogPosting and FAQPage schema, structure every section answer-first under question-based headings, and keep your highest-value pages fresh. Everything below is the exact implementation of those five steps.
## Quick Wins (Do These Today)
1. Update `robots.txt` to allow AI crawlers
2. Create `/llms.txt` at site root
3. Add BlogPosting schema to 10 top articles
4. Structure one article with 15+ headers instead of 3
That's a 30-minute investment that unlocks visibility in Perplexity, ChatGPT, and Claude.
## What Software Checks Whether ChatGPT and Perplexity Cite Your Posts?
[citability.dev](https://citability.dev/?utm_source=chudidev&utm_medium=referral&utm_campaign=how-to-optimize-for-perplexity-chatgpt-ai-search) is the tool I built to answer that: it asks ChatGPT and Perplexity real questions in your topic and records which URLs from your blog they actually cite, keeping the raw AI responses as receipts, so a citation gained or lost is traceable to what the engine said. The free [30-second scan](https://citability.dev/scan?utm_source=chudidev&utm_medium=referral&utm_campaign=how-to-optimize-for-perplexity-chatgpt-ai-search) checks the infrastructure half of the five steps below before you spend time on the content half.
---
## Why Do AI Engines Need Different Optimization Than Google?
Google ranks pages based on backlinks and authority signals. AI engines, Perplexity, ChatGPT, Claude, retrieve content by semantic relevance and structure. They need explicit crawler permission, clean schema markup, and answer-first formatting. Without these signals, your content is invisible to AI search regardless of how well it ranks on Google.
## Step 1: Update robots.txt for AI Crawlers
Your `robots.txt` is the bouncers list for search crawlers. Most sites have something like:
```
User-agent: *
Disallow: /admin
Disallow: /api
Sitemap: https://yoursite.com/sitemap.xml
```
This is Google-focused. AI engines need explicit permission. Update it:
```
# Allow all standard crawlers
User-agent: *
Disallow: /admin
Disallow: /api
Disallow: /private
# Explicitly allow AI crawlers
User-agent: GPTBot
Allow: /
User-agent: ClaudeBot
Allow: /
User-agent: PerplexityBot
Allow: /
User-agent: Googlebot-Extended
Allow: /
User-agent: CCBot
Allow: /
Sitemap: https://yoursite.com/sitemap.xml
```
**Why each one matters:**
| Bot | Owner | Used By |
|-----|-------|---------|
| GPTBot | OpenAI | ChatGPT, GPT-5 |
| ClaudeBot | Anthropic | Claude.ai, API users |
| PerplexityBot | Perplexity | Perplexity search |
| Googlebot-Extended | Google | Google's AI Overview, SGE |
| CCBot | CommonCrawl | Hugging Face, open-source models |
**Test it:** Use this to verify:
```bash
curl -I https://yoursite.com/robots.txt
```
---
## Step 2: Create `/llms.txt` (New File)
While robots.txt controls *access*, `/llms.txt` controls *attribution*. Create a new file at the root. For a comprehensive deep-dive on this file, see my guide on [llms.txt and robots.txt for AI crawlers](/blog/llms-txt-robots-txt-for-ai-crawlers):
`https://chudi.dev/llms.txt`
```markdown
# LLM Content Policy
All articles on this site are available for training, search indexing, and answer generation by LLMs.
## How to attribute our content:
For articles: [Article Title] by [Author Name] (sitename.com)
For data: Link to the specific section
For code: Preserve license headers
## How we'd like to be credited:
If citing multiple articles, link to: https://yoursite.com
## Content discovery:
- Sitemap: https://yoursite.com/sitemap.xml
- RSS: https://yoursite.com/rss.xml
- Blog archive: https://yoursite.com/blog
## Content we don't want indexed:
- Drafts (marked `draft: true`)
- Private tools or dashboards
- Archived content older than 5 years
## Preferred citation format:
[Article Title] — Author Name on yoursite.com
---
Last updated: January 2025
```
**Why it matters:** AI engines scan for `llms.txt` to understand your content policy. Without it, some engines might skip you (too risky). With it, you're explicitly inviting them in.
---
## What Schema Markup Should You Add for AI Search?
Start with BlogPosting schema on every article, it tells AI engines the content type, author, date, and topic. Add FAQPage schema wherever you have Q&A sections, and HowTo schema on step-by-step guides. These three schema types cover most blog content and have the highest citation impact in AI search.
## Step 3: Add Schema.org Structured Data
AI engines parse JSON-LD to understand content structure. This structured approach to content is what enables the extraction and synthesis that powers answer engines. Add this to your blog post template:
### For Articles (BlogPosting)
Add this in your page's ``:
```html
```
### For How-To Content (HowToSchema)
If you're teaching a process:
```html
```
### For FAQ Content (FAQPage)
```html
```
**Verify schema:** Use [Google's Rich Results Tester](https://search.google.com/test/rich-results) to validate.
---
## Step 4: Structure Content for Extraction
AI engines need to *find* the answer within your content. This means:
### Use Headers to Break Up Content
**Bad structure:**
```
# Article Title
Long paragraph explaining the concept...
More context...
Finally, the key insight...
```
**Good structure:**
```
# Article Title
## What is AEO?
AEO (Answer Engine Optimization) is the practice of structuring content so AI engines can extract, cite, and surface it in generated answers. It focuses on crawl access, structured data, and answer-first formatting.
## Why does AEO matter for visibility?
AI engines like Perplexity and ChatGPT now answer queries directly without sending users to search results. If your content is not optimized for extraction, you are invisible to this growing traffic source.
## How to implement AEO
Steps...
## Common mistakes
What to avoid...
## FAQ
- Q1: Answer
- Q2: Answer
```
Every 2-3 paragraphs, add a header. This makes it easier for AI to:
1. Find the specific section answering a user's question
2. Extract just that section (not the whole article)
3. Cite the correct part of your content
### Use Lists for Dense Information
Instead of:
> "To optimize your site, you need to update your robots.txt file, create an llms.txt file, add schema to your articles, and structure your content with headers."
Write:
> "To optimize your site:
> 1. Update robots.txt for AI crawlers
> 2. Create llms.txt at site root
> 3. Add schema to articles
> 4. Structure with semantic headers"
AI engines can extract lists more reliably than paragraph prose.
### Put the Answer at the Top
Don't make readers scroll for the punchline. If your headline is "Why AEO Matters," answer it in the first paragraph:
> "AEO matters because 30% of searches now go through AI engines instead of Google. If your content isn't optimized for Perplexity, ChatGPT, and Claude, you're invisible to an entire audience."
Then expand with context, examples, and proof.
### Use Definition Boxes
For key concepts, use a highlighted box:
```markdown
> **Definition:** AEO (Answer Engine Optimization) is optimizing your content to be found, extracted, and cited by AI search engines.
```
This signals to AI engines: "This is important context."
### Include Tables and Structured Data
Tabular data is easier for AI to extract:
| Factor | SEO | AEO |
|--------|-----|-----|
| Ranking | Backlinks | Content structure |
| Speed | Important | Less important |
Don't just describe in paragraphs. Use tables.
---
## How Do You Know If AI Engines Are Citing Your Content?
Search your target keywords directly in Perplexity, ChatGPT search, and Claude. If your site doesn't appear in sources within 4-6 weeks of publishing, you likely have a crawl access problem, a freshness issue, or your content isn't structured as direct answers. Manual citation checks take five minutes weekly.
## Step 5: Monitor Visibility in AI Engines
### Search Your Topics in Perplexity
Go to [perplexity.ai](https://perplexity.ai) and search your main keyword. Do you see your content cited?
If yes ✅ → Your content is discoverable
If no ❌ → You need to audit (usually a robots.txt or freshness issue)
### Check ChatGPT Search
OpenAI's ChatGPT now searches the web. Search your site name + keyword. Does your content appear?
### Use Perplexity Citation Tracking
When your content is cited, you'll see traffic from `perplexity.com` in your analytics. Track this growth.
---
## 2026 Update: Platform-Specific Citation Strategies
Since this article was first published, research has revealed that each AI platform has distinct source preferences. A one-size-fits-all approach to AI search optimization is no longer sufficient.
### Perplexity: The Reddit Connection
Perplexity cites approximately 6.6 sources per answer, more than any other platform. Its source pool leans heavily on Reddit, with 46.7% of top-cited sources coming from Reddit discussions. This means genuine participation in subreddits relevant to your expertise (r/SEO, r/webdev, r/artificial) directly increases your chances of being cited.
The mechanism: Perplexity indexes Reddit threads and cites them as sources. When your expertise appears in those threads (with or without links to your site), Perplexity associates your knowledge with your brand.
### ChatGPT: Recency and Authority
ChatGPT cites only about 2.6 sources per answer, making it the most selective platform. It shows strong preference for Wikipedia (7.8% of all citations) and recently updated content. 95% of ChatGPT citations come from content published or updated within the last 10 months.
To improve ChatGPT citations: update your highest-value articles quarterly with new data, add `dateModified` schema, and ensure your content contains specific statistics AI can attribute.
### Google AI Overviews: Still Tied to Rankings
Google AI Overviews show 76% overlap with traditional top 10 results, making it the most SEO-correlated AI feature. If you rank well on Google, you're likely to appear in AI Overviews. Focus traditional SEO efforts here.
### Measuring Your AI Visibility
You can now audit your site's AI infrastructure readiness with automated tools. [citability.dev](https://citability.dev/scan?utm_source=chudidev&utm_medium=referral&utm_campaign=how-to-optimize-for-perplexity-chatgpt-ai-search) runs 10 checks against your site covering robots.txt, sitemap, structured data, answer-first content, and freshness signals. It measures three tiers: AI visibility (can AI find you?), AI recommendability (does AI suggest you?), and AI citability (does AI link to you?).
To measure your citation rate directly, query ChatGPT, Perplexity, and Claude with 20 questions your site should answer. Track two metrics per query: whether the AI mentions your brand (visibility) and whether it links to a URL on your domain (citation). In our benchmark of 7 sites, the gap between these two numbers ranged from 25 to 95 points. Ahrefs (DR 92) was 100% visible but only 5% cited. A site with DR under 10 achieved 15% citation rate by focusing on original data and answer-first structure. Authority did not predict citations. Structure did. The full step-by-step methodology, including the 20-query template and per-engine scoring sheet, is published on freeCodeCamp: [How to Measure Your AI Citation Rate Across ChatGPT, Perplexity, and Claude](https://www.freecodecamp.org/news/how-to-measure-your-ai-citation-rate-across-chatgpt-perplexity-and-claude/). The companion case study is [I Audited 7 Websites for AI Citability](/blog/ai-citability-audit-what-predicts-citations).
---
## Complete Optimization Checklist
- [ ] robots.txt allows GPTBot, ClaudeBot, PerplexityBot
- [ ] `/llms.txt` exists at site root
- [ ] Top 10 articles have BlogPosting schema
- [ ] How-to content has HowToSchema
- [ ] FAQ content has FAQPageSchema
- [ ] Content has 10+ headers (not 3)
- [ ] Key answers in first paragraph
- [ ] Important data in tables, not paragraphs
- [ ] Meta descriptions under 160 chars (Google habit)
- [ ] Images have descriptive alt text
- [ ] No critical content in images only
- [ ] Content updated in last 12 months (fresh signal)
- [ ] Run infrastructure scan at [citability.dev](https://citability.dev/scan?utm_source=chudidev&utm_medium=referral&utm_campaign=how-to-optimize-for-perplexity-chatgpt-ai-search) to identify gaps
- [ ] Measure AI citation rate with 20 manual queries across 3 platforms
- [ ] Add original data (benchmarks, tables, unique statistics) to top articles
---
## Why Isn't My Content Showing Up in AI Search Results?
The four most common causes: AI bots blocked in robots.txt, conflicting canonical URLs from cross-posting, duplicate content diluting citation chances, and schema errors preventing structured data from registering. Run through each diagnostic in order, most optimization failures trace back to one of these four fixable issues.
## When Your Optimization Isn't Working
If you've done the five steps and still don't see citations in Perplexity or ChatGPT after 4-6 weeks, run this diagnostic.
**Check if AI bots are reaching your pages.** Look in your server logs or analytics for user-agent strings containing GPTBot, ClaudeBot, or PerplexityBot. If you see no traffic from these bots, there's a crawl access issue, either robots.txt is still blocking them, or your hosting provider's firewall doesn't recognize these newer bot names.
**Verify your canonical is consistent.** AI systems avoid citing content with conflicting canonical signals. If you're [cross-posting to Dev.to](/blog/devto-cross-posting-automation), Medium, or LinkedIn, make sure each cross-post has your original URL in the canonical field, not the platform's default. One conflicting canonical can suppress citations across all AI engines.
**Check for duplicate content.** AI engines, like Google, downweight duplicate content. If you have two posts targeting the same query, consolidate them. Two 800-word posts on the same topic compete with each other and dilute citation chances compared to one 1,600-word authoritative post.
**Test your schema.** Run your top 3 posts through Google's Rich Results Test. If schema errors appear, fix them, AI engines use the same structured data signals to understand content type.
Most optimization failures trace back to one of these four issues. The good news: all four are diagnosable and fixable in an afternoon.
If you already run a SaaS SEO programme and want to know what this changes for it, [SEO for SaaS in the AI search era](/blog/seo-for-saas-ai-search-era) covers what transfers and what your current reports cannot see. If you suspect a competitor is already winning these answers, start with [an AI visibility audit](/blog/ai-visibility-audit-b2b-saas).
## The Advantage
Here's the thing: **most creators still treat AEO as optional.**
You just did these 5 steps. Your competitors haven't. This gives you a 6-12 month window where your content will be cited more often in AI answers, driving visibility and traffic.
This is the opposite of SEO, where the first-mover advantage is gone. AEO is still day one. Want a quick score first? Run the free [AEO audit tool](/tools/aeo-audit) to check crawler access, schema, and structure before you dig into the full strategy in my [detailed AEO guide](/blog/aeo-answer-engine-optimization-explained).
Five changes is the DIY path and it works.
**Next:** Run a free AI visibility scan at [citability.dev](https://citability.dev/scan?utm_source=chudidev&utm_medium=referral&utm_campaign=how-to-optimize-for-perplexity-chatgpt-ai-search) to check your infrastructure readiness, or dive deeper with the [full AEO guide](/blog/aeo-answer-engine-optimization-explained).
When that scan comes back and you cannot tell which two of the five actually moved anything, [that is the read you are buying](/services).
**Related on citability.dev:** if your citation rate is stuck at zero despite good rankings, the diagnosis path is [The 0% ChatGPT Citation Trap](https://citability.dev/blog/the-0-percent-chatgpt-citation-trap?utm_source=chudidev&utm_medium=referral&utm_campaign=how-to-optimize-for-perplexity-chatgpt-ai-search); the full signal framework behind every check above is [What Is AI Citability? The Complete Framework](https://citability.dev/blog/what-is-ai-citability?utm_source=chudidev&utm_medium=referral&utm_campaign=how-to-optimize-for-perplexity-chatgpt-ai-search).
--- END POST ---
================================================================================
POST: Build SaaS With AI Agents: 7 Days to Paying Users
================================================================================
URL: https://chudi.dev/blog/introducing-microsaasbot-ai-builds-saas
Date: 2026-01-17T00:00:00.000Z
Tags: ai, saas, automation, microsaas, claude-code, startup
Pillar: ai-building
Reading Time: 12 min
Word Count: 2261
TL;DR: I got tired of the idea-to-launch grind. Research, validation, architecture, coding, deployment, weeks of work before knowing if anyone cares. So I built MicroSaaSBot: a multi-agent system that takes a problem statement and outputs a deployed SaaS with Stripe billing. It built StatementSync (now live with paying users) in one week. This is what AI-first product development looks like.
Key Takeaways:
- MicroSaaSBot uses 4 specialized agents: Researcher, Architect, Developer, Deployer
- Validation phase scores ideas 0-100; problems below 60 get killed before any code is written
- First shipped product: StatementSync, idea to production in 7 days with Stripe billing
- The system handles the tedious 80%, you focus on decisions that require human judgment
- This isn't vaporware: there's a live product with paying users built entirely by MicroSaaSBot
--- CONTENT ---
Founders sit on backlogs of validated ideas that never ship, because execution costs weeks before anyone knows if a customer will pay. MicroSaaSBot closes that gap: a 4-agent system, Researcher, Architect, Developer, Deployer, that took StatementSync from problem statement to production with Stripe billing and paying users in 7 days.
I had a backlog of 47 SaaS ideas. Most would never get built.
The bottleneck wasn't creativity, it was execution. Each idea requires:
- Market research
- Problem validation
- Architecture planning
- Actual coding
- Deployment
- Billing integration
Weeks of work before you know if anyone will pay.
The question I kept coming back to: can you build SaaS with AI agents and compress that grind to days instead of months?
So I built a system to answer it.
To build SaaS with AI agents, you replace the traditional single-developer workflow with four specialized agents, each owning one phase of the pipeline. MicroSaaSBot's first product, StatementSync, went from problem statement to production in 7 days with Stripe billing and paying users. That's the proof of concept, not the pitch.
| Phase | Duration | Output |
|-------|----------|--------|
| Validation | 2 days | 78/100 score, approved |
| Architecture | 1 day | Tech stack, schema, approved |
| Development | 3 days | All features implemented |
| Deployment | 1 day | Live on Vercel with Stripe |
| **Total** | **7 days** | **Production SaaS** |
The first paying user converted within 48 hours of launch. Here's how the system works.
## What Is MicroSaaSBot?
[MicroSaaSBot](/micro-saas-bot) is a multi-agent AI system that takes a plain-language problem statement and outputs a fully deployed SaaS product, complete with user authentication, a database, and Stripe billing. It handles the entire execution pipeline so founders focus on strategic decisions rather than implementation grind.
MicroSaaSBot is an AI system that takes a problem statement and outputs a deployed SaaS product.
Input: "Bookkeepers spend 10+ hours weekly transcribing bank statements to spreadsheets."
Output: StatementSync, a live product with user auth, PDF processing, and Stripe billing.
Time: One week.
This isn't hypothetical. StatementSync is live. Users are paying. The AI built it.
## How Do the Four Agents Work Together?
MicroSaaSBot splits product development across four specialized agents, Researcher, Architect, Developer, and Deployer, each optimized for its phase. The Researcher validates market fit; the Architect designs the tech stack; the Developer writes and tests code; the Deployer ships to production. Specialization prevents context dilution across incompatible tasks.
## The Four Agents
MicroSaaSBot uses specialized agents for each development phase:
Each agent is optimized for its phase. The Researcher agent knows nothing about coding. The Developer agent doesn't care about market research. Specialization enables excellence.
Agents communicate through typed handoff documents, not raw conversation history:
```typescript
// Researcher → Architect
interface ValidationHandoff {
score: number;
recommendation: 'proceed' | 'kill';
persona: { who: string; painPoints: string[]; currentSolutions: string[] };
keyConstraints: string[];
}
// Architect → Developer
interface ArchitectureHandoff {
techStack: TechStack;
schema: DatabaseSchema;
features: FeatureSpec[];
deploymentTarget: 'vercel' | 'other';
}
// Developer → Deployer
interface DeploymentHandoff {
buildPasses: boolean;
envVarsNeeded: string[];
stripeConfig: StripeConfig;
databaseMigrations: string[];
}
```
Explicit schemas prevent implicit context loss. Twice during StatementSync's build I discovered decisions the Architect made that never surfaced in handoff. Without the schema forcing them to be written down, the Developer would have built on wrong assumptions.
## The Workflow
### Phase 1: Validation
You provide a problem statement:
> "Bookkeepers spend 10+ hours weekly transcribing bank statements to spreadsheets."
The Researcher agent investigates:
- Who has this problem? (Persona definition)
- How severe is it? (Pain scoring)
- Are they paying for solutions? (Willingness to pay)
- What solutions exist? (Competitive landscape)
Output: Problem score (0-100).
Problems scoring below 60 get killed. No architecture, no coding, no wasted effort. This is the most important feature, stopping bad ideas early.
The Researcher agent scores across four dimensions:
| Dimension | Points | What It Measures |
|-----------|--------|-----------------|
| Severity | 0-30 | How much does this hurt, daily? |
| Frequency | 0-20 | How often does it happen? |
| Willingness to Pay | 0-30 | Are people already spending money? |
| Competition | 0-20 | Is there a differentiation opportunity? |
StatementSync scored 78/100:
- Severity: 24/30 (bookkeepers lose real billable time daily)
- Frequency: 16/20 (multiple times per day for active professionals)
- Willingness to Pay: 22/30 (competitors charge $0.25-1.00/file already)
- Competition: 16/20 (flat-rate pricing is a clear gap)
Green light. Ideas I killed before getting here:
- **Meal planning app (42/100)**: Saturated market, free expectation, abysmal retention
- **Email cleanup tool (38/100)**: Built-in features cover it, near-zero WTP
- **Meeting notes with AI (44/100)**: Otter.ai raised $50M and does it free. No angle.
- **GitHub PR summarizer (58/100)**: GitHub itself is building the feature. Losing position.
Those four kills saved somewhere around 20 weeks of wasted development. The math is simple: one day of validation beats six weeks of building something nobody pays for.
### Phase 2: Architecture
The Architect agent designs the system:
```
Frontend: Next.js 15 (App Router)
Auth: Clerk
Database: Supabase PostgreSQL
Storage: Supabase Storage
Payments: Stripe
PDF Processing: unpdf
Hosting: Vercel
```
Key decisions are surfaced for human approval:
- "Using pattern-based extraction (faster, cheaper) vs LLM extraction (more flexible). Recommend pattern-based for cost control. Approve?"
- "Flat-rate pricing vs per-file. Recommend flat-rate for user acquisition. Approve?"
You make the strategic calls. The agent handles implementation details. The reasoning behind the flat-rate pricing recommendation is in [flat-rate vs per-file SaaS pricing](/blog/flat-rate-vs-per-file-saas-pricing).
### Phase 3: Development
The Developer agent builds features:
- User authentication flow
- File upload handling
- PDF parsing engine
- Export generation (Excel, CSV)
- Billing integration
- Dashboard UI
Each feature includes:
- Implementation code
- Error handling
- TypeScript types
- Basic tests
Development happens in phases, each phase builds on the previous, with checkpoints for review.
### Phase 4: Deployment
The Deployer agent ships:
- Vercel project configuration
- Supabase database setup
- Stripe product/price creation
- Webhook configuration
- Environment variables
- DNS and domain setup
Output: A live URL with working product.
## What Humans Still Do
MicroSaaSBot handles the tedious 80%. Humans handle the meaningful 20%:
**Strategic decisions:**
- Approve/reject validation scores
- Choose between architectural options
- Set pricing and positioning
- Define brand/design preferences
**Business operations:**
- Marketing and sales
- Customer support
- Financial management
- Legal/compliance
**Quality judgment:**
- Review generated code
- Test edge cases
- Approve deployment
- Monitor production
Think of MicroSaaSBot as a senior engineer who executes your vision. You're still the founder. You make the decisions that matter.
## What Makes a Good MicroSaaS Idea?
Not every problem becomes a viable product. High-scoring ideas share four traits: a specific named persona, existing paid solutions with clear gaps, daily or weekly recurrence, and a quantifiable time or money cost. Vague personas like "small businesses" and problems with free alternatives consistently score below the 60-point kill threshold.
## What Makes a Good MicroSaaS Idea
Not all problems survive the validation phase. After running dozens of ideas through MicroSaaSBot's Researcher agent, the pattern of what fails is clear.
**High-scoring problems (70+):**
- Specific, named persona with a clearly observed behavior ("freelance bookkeepers who process 50+ PDFs monthly")
- Existing paid solutions with obvious gaps (competitors exist but users complain about cost or friction)
- Daily or weekly recurrence (not an occasional inconvenience)
- Quantifiable time cost ("10+ hours per week")
**Low-scoring problems (below 60):**
- Vague personas ("small businesses" or "busy professionals")
- Problems with free alternatives that are "good enough"
- Pain points that disappear when the user upgrades their workflow
- Markets that require enterprise sales or custom contracts
The scoring rubric isn't arbitrary, it reflects where most SaaS products die. Vague personas lead to positioning that resonates with nobody. Problems with free alternatives lead to CAC that never recovers. MicroSaaSBot's kill threshold at 60 exists because the system has seen enough failed validations to know which signals predict viable products.
The counterintuitive finding: niche is better. A product for "freelance bookkeepers who process bank statements" outperforms a product for "anyone who works with documents." Specificity creates referrals, and referrals have zero CAC.
## The First Success
StatementSync is proof this works:
| Phase | Duration | Output |
|-------|----------|--------|
| Validation | 2 days | 78/100 score, approved |
| Architecture | 1 day | Tech stack, schema, approved |
| Development | 3 days | All features implemented |
| Deployment | 1 day | Live on Vercel with Stripe |
| **Total** | **7 days** | **Production SaaS** |
Production metrics after six weeks:
| Metric | Value |
|--------|-------|
| Processing time | 3-5 seconds per statement |
| Extraction accuracy | 99% (pattern-based, not OCR) |
| Supported banks | 5 (Chase, BofA, Wells, Citi, Capital One) |
| Runtime cost per extraction | $0 |
There was one notable blocker during development: pdf-parse fails on Vercel serverless due to native canvas bindings. Discovered this at 2 AM on Day 5. Two hours of debugging, switched to unpdf (pure JavaScript, serverless-native), back on track.
The first five users came from a single Reddit comment in r/bookkeeping. I described the problem and asked if anyone had found a good solution. Four replied that existing tools were too expensive or too complex. One asked if there was a flat-rate option. I shared the link. All five signed up within 24 hours. One converted to paid within 48.
Three of those first five opened with some version of "finally." That's the signal a 78/100 score predicts but can't guarantee.
The same validation-first, phase-gated workflow applies whether the output is a $19/month SaaS or a free browser tool, what changes is the scope, not the process.
## How Fast Can You Build SaaS With AI Agents?
Shipping fast matters because you learn faster, fail cheaper, and reach real users sooner. MicroSaaSBot compresses a traditional 8-week build-and-deploy cycle to 7 days. That speed advantage shifts the constraint from execution to distribution, where founder judgment creates the most leverage and where AI cannot replace you.
## Why This Matters
The traditional path:
1. Have idea (Day 1)
2. Research market (Week 1-2)
3. Plan architecture (Week 2-3)
4. Build MVP (Week 4-8)
5. Deploy and iterate (Week 9+)
6. Maybe get users (Month 3+)
The MicroSaaSBot path:
1. Have idea (Day 1)
2. Validated + deployed (Day 7)
3. Get users (Week 2)
Speed matters because:
- You learn faster
- You fail cheaper
- You iterate sooner
- You validate with real users, not assumptions
## The Bigger Picture
MicroSaaSBot isn't just a productivity tool. It's a different way of building.
**Traditional**: Humans do everything, AI assists with code completion.
**[AI-first](/blog/ai-first-product-development-future)**: AI handles the workflow, humans make strategic decisions.
The shift is from "AI helps me code" to "AI builds the product, I run the business."
This is where product development is heading. MicroSaaSBot is my bet on that future.
## The Hard Parts AI Doesn't Solve
MicroSaaSBot compresses the execution timeline significantly. But it doesn't eliminate the hard problems in building a SaaS business.
**Product-market fit** is still discovered through user behavior, not agent validation. An 78/100 validation score means the problem is real and the persona is specific, it doesn't guarantee that your specific implementation solves it the way users want. StatementSync's first design put export buttons in the wrong place; users had to tell me that.
**Pricing psychology** requires market intuition. MicroSaaSBot can compare pricing models mathematically (flat-rate vs. per-file break-even), but deciding whether $19 or $29 anchors better for bookkeepers required thinking through their budget context, not running more analysis.
**Distribution** doesn't exist until you build it. MicroSaaSBot ships a product to a URL. Getting the first 10 paying customers still requires showing up in communities, writing about the problem, and doing things that don't scale. The product being built faster doesn't change how long distribution takes.
The right frame isn't "AI replaces founders." It's "AI eliminates the execution bottleneck so founders can focus on distribution, customers, and judgment." The work that matters most is still yours.
## The Iteration Cycle After Launch
MicroSaaSBot handles the build. The period after launch requires a different workflow, one that's mostly human.
The first 30 days after shipping StatementSync were user research: watching what users did, where they got confused, which features they ignored. AI agents aren't good at this yet. Interpreting a heatmap or reading a support conversation requires judgment about what the user was actually trying to do versus what they said they were trying to do.
What worked was a simple post-launch review cycle:
- **Week 1**: Watch every user session (session replay tools like Hotjar)
- **Week 2**: Interview any user who sent a support message
- **Week 3**: Identify the one feature change with the highest friction impact
- **Week 4**: Build and ship that change
The Developer agent handled Week 4. Weeks 1-3 were entirely human.
This loop doesn't need MicroSaaSBot. It needs you paying attention. The system gave you a product in 7 days so you could start this loop faster, not so you could skip it.
The fastest path to product-market fit isn't faster building. It's faster learning. MicroSaaSBot compresses the build so you spend more time learning.
Sitting on a validated idea that execution cost keeps stuck in the backlog? I build MVP SaaS products the same way, AI-agent-accelerated, human-reviewed at every decision point. [MVP builds start at $500](/services) and ship in weeks; custom builds run from $5,000, scoped per project. Fixed scope, fixed price after scoping, full source code and documentation included.
## What's Next
The roadmap:
1. **More product types** - Beyond web SaaS to APIs, browser extensions, automation tools.
2. **Iteration system** - Handle post-launch features and improvements
3. **Analytics integration** - Let the Researcher agent learn from production data
4. **Template library** - Pre-validated patterns for common product types
StatementSync was the first. It won't be the last.
---
**Related**: [Portfolio: MicroSaaSBot](/portfolio/microsaasbot) | [Portfolio: StatementSync](/portfolio/statementsync)
--- END POST ---
================================================================================
POST: llms.txt for AI Crawlers: Why robots.txt Is Not Enough
================================================================================
URL: https://chudi.dev/blog/llms-txt-robots-txt-for-ai-crawlers
Date: 2026-01-17
Tags: seo, ai, llms.txt, robots.txt, ai-crawlers
Pillar: ai-building
Reading Time: 17 min
Word Count: 3398
TL;DR: llms.txt is a site-level policy file that tells AI engines how they can use and cite your content. It complements robots.txt by focusing on usage and attribution rather than crawl access.
Key Takeaways:
- llms.txt sets usage and attribution rules for AI systems.
- Publish it at the site root, alongside robots.txt.
- Link to sitemap and RSS so crawlers discover updates.
- Robots.txt controls access; llms.txt controls usage.
--- CONTENT ---
llms.txt is a site-level policy file that tells AI engines how they can use and cite your content. It complements robots.txt by focusing on usage and attribution rather than crawl access. If you want AI systems to cite you correctly, this is the simplest control point.
## What is llms.txt?
llms.txt is a plain-text policy file you publish at your site root that tells AI engines how they may use and cite your content. Where robots.txt controls whether a crawler can access your pages, llms.txt governs what the crawler can do with the content it finds: training, answer generation, attribution format, and which sections to exclude from indexing entirely.
`llms.txt` is a root-level policy file that tells AI engines like Perplexity, Claude, and ChatGPT how they may use and attribute your content. Unlike robots.txt, which controls crawl access, llms.txt governs usage policy and preferred citation format. Publishing it signals explicit consent to AI indexing and helps ensure correct attribution.
`llms.txt` is a new standard file that tells AI engines (Perplexity, Claude, ChatGPT) how to handle your content.
- **robots.txt** = "Can you crawl my site?" (access control)
- **llms.txt** = "How should you use my content?" (usage policy)
Both should exist on your site. This is part of the broader [AI search optimization strategy](/blog/how-to-optimize-for-perplexity-chatgpt-ai-search) that helps your content get discovered and cited.
---
## Why llms.txt Matters
### The Problem: Content Attribution
When OpenAI's ChatGPT answers a user's question, it synthesizes an answer from multiple sources. But where does it cite those sources?
**Without llms.txt:** ChatGPT has to guess your preferred attribution format.
- Maybe it cites the article title
- Maybe it cites your domain
- Maybe it doesn't cite you at all
**With llms.txt:** You explicitly say "Cite me like this: [Title] by [Author] (yoursite.com)"
AI engines follow your preference.
### The Bigger Picture
`llms.txt` emerged in 2024 as a response to AI scraping concerns. Instead of fighting crawlers, creators use `llms.txt` to:
1. **Invite crawlers**, "Please index my content"
2. **Set terms**, "But cite me this way"
3. **Exclude content**, "Don't train on my drafts"
4. **Provide discovery**, "Here's my sitemap and RSS"
It's like putting a "Welcome" sign on your site with conditions attached. This is a foundational piece of what I call [Answer Engine Optimization (AEO)](/blog/aeo-answer-engine-optimization-explained), the practice of making your content discoverable and citable by AI systems. Not sure where your site stands? Run the free [AEO audit tool](/tools/aeo-audit) to check your robots.txt and llms.txt against exactly what AI crawlers look for.
---
## How AI Engines Use llms.txt
When a crawler visits your site:
1. Fetch `/robots.txt` → Check if allowed to crawl
2. Fetch `/llms.txt` → Check usage policy
3. Fetch `/sitemap.xml` → Discover all pages
4. Extract content → Index and train
If `/llms.txt` doesn't exist, the crawler might:
- Crawl your site anyway (risky for them)
- Skip your site entirely (loss for you)
- Use conservative assumptions (minimal indexing)
Having `/llms.txt` shows you've **explicitly consented** to AI indexing.
The distinction between "crawl access" and "usage policy" matters more than it sounds. A crawler that can access your page via robots.txt still faces a question: can I train on this content? Can I quote it in an answer? Should I attribute it, and how? Without llms.txt, those questions have no answers. The crawler either guesses conservatively (you get less visibility) or guesses aggressively (you lose attribution control). Neither outcome is what you want.
---
## How to Create llms.txt
### Step 1: Location
Create a file at: `https://chudi.dev/llms.txt`
It must be at the root, not in `/content/` or `/blog/`. Just like `robots.txt` is at the root. If you're using a static site generator like Next.js, SvelteKit, or Hugo, place the file in your `public/` or `static/` directory so it gets served at the root path during deployment. For SvelteKit specifically, you can also create a server route at `src/routes/llms.txt/+server.ts` that returns the content dynamically, useful if you want to auto-generate sections like your sitemap URL or last-updated date from your build config.
### Step 2: Content
Here's a basic template:
```markdown
# LLM Content Policy for [Your Site]
All articles on this site are available for training and search indexing by large language models.
## How to attribute content
When citing articles from this site, please use the format:
[Article Title] — [Author Name] on [yoursite.com]
Example: "How to Optimize for Perplexity" — Chudi on chudi.dev
## Content discovery endpoints
- Sitemap: https://yoursite.com/sitemap.xml
- RSS feed: https://yoursite.com/rss.xml
- Blog archive: https://yoursite.com/blog
## Content not available for indexing
- Pages marked as draft or private
- Internal documentation
- User-generated content (comments)
- Archived content older than [5] years
## Preferred citation style
Inline: [Article](https://yoursite.com/article-url) by Author Name
Bibliography: Author Name. "Article Title." Your Site, YYYY.
## Questions or Concerns
Email: [your-email@yoursite.com]
Last updated: January 2025
```
### Step 3: Customize for Your Site
Replace:
- `[Your Site]` → your actual site name
- `[Author Name]` → your name
- Email → your contact email
- Dates → today's date
### Step 4: Include Metadata
Optionally, you can include a JSON section:
```json
{
"version": "1.0",
"license": "CC BY-SA 4.0",
"attribution_required": true,
"commercial_use": "allowed",
"modification": "allowed",
"sitemap": "https://yoursite.com/sitemap.xml",
"rss": "https://yoursite.com/rss.xml"
}
```
This helps AI engines parse your policy programmatically.
---
## Where llms.txt vs robots.txt
| Aspect | robots.txt | llms.txt |
|--------|-----------|----------|
| Purpose | Access control | Usage policy |
| Audience | Search crawlers | AI engines |
| Required | Yes (best practice) | No (but recommended) |
| Format | Plain text directives | Markdown + optional JSON |
| Location | `/robots.txt` | `/llms.txt` |
| Blocks access | Yes | No |
| Legally binding | No | No (advisory) |
**robots.txt** is like a gate at your property. **llms.txt** is like a sign on the gate saying "Welcome, but please do X."
The format difference is worth noting. robots.txt uses a strict directive syntax that machines parse rigidly, `User-agent`, `Disallow`, `Allow`. llms.txt uses markdown with optional embedded JSON, which gives you room to express nuance that directive syntax cannot capture. You can explain your attribution preferences in natural language, describe what types of content are available for different use cases, and provide context about your licensing terms. This flexibility is intentional, AI systems are better at parsing natural language than traditional crawlers, so the policy file takes advantage of that capability.
Another key difference: robots.txt is enforced by convention. Well-behaved crawlers respect it. llms.txt is purely advisory, there is no mechanism to force compliance. But the advisory nature is actually a strength for creators who want visibility. You are not blocking anything. You are inviting crawlers in and telling them how to treat your content responsibly. The incentive alignment works because AI engines want to cite correctly, it improves their answer quality, and your llms.txt makes that easy for them.
---
## Common llms.txt Policies
### Policy 1: Fully Open (Creator-Friendly)
```markdown
# LLM Content Policy
All content on this site is available for:
- Training large language models
- Extracting for answer engines
- Commercial and non-commercial use
Just cite us: [Title] — [Author] ([yoursite.com])
```
**Best for:** Indie creators who want maximum visibility
### Policy 2: Attribution Required (Balanced)
```markdown
# LLM Content Policy
Content available for training and use, with required attribution.
Required format: [Article Title] by [Author Name] (yoursite.com)
Prohibited use: Removing or hiding attribution
```
**Best for:** Most creators who want credit
### Policy 3: Non-Commercial Only (Restrictive)
```markdown
# LLM Content Policy
Content available for non-commercial use and training.
Prohibited use:
- Commercial products without permission
- Training proprietary LLMs
- Republishing without modification
```
**Best for:** Creators concerned about exploitation
### Policy 4: Permission Required (Most Restrictive)
```markdown
# LLM Content Policy
All uses require explicit permission. Email [your-email] to request.
```
**Best for:** Creators who want full control
---
## Real-World Examples
### Example 1: Tech Blog
```markdown
# LLM Content Policy
Technical articles on this site are available for:
- AI training (open-source and proprietary)
- Answer generation (Perplexity, ChatGPT, Claude)
- Academic and educational use
Citation format: [Title] by [Author] on [yoursite.com]
Prohibited:
- Removing examples or code without attribution
- Training models specifically to replicate this blog
Updated: January 2025
```
### Example 2: Content Creator
```markdown
# LLM Content Policy
All essays are available for training and synthesis.
Citation: [Essay Title] — [Your Name]
Prefer long-form citations, not snippets.
Excluded:
- Guest posts (ask the author)
- Archived essays older than 3 years
Contact: [email]
```
### Example 3: SaaS Documentation
```markdown
# LLM Content Policy
Documentation is available for indexing and use in AI tools.
Required attribution: Link to the original docs page + software name.
Prohibited:
- Repackaging docs as your own product
- Training models on raw HTML without attribution
Questions? hello@[company].com
```
---
## How to Test if llms.txt Works
### Method 1: Manual Check
```bash
# Verify it exists and is accessible
curl https://chudi.dev/llms.txt
# Should return 200 status code
curl -I https://chudi.dev/llms.txt
```
### Method 2: Check in Perplexity
Search your site name in Perplexity. Are you being cited?
Before llms.txt: Sporadic or no citations
After llms.txt: More consistent citations with proper attribution
### Method 3: Monitor Traffic
Track referral traffic from:
- `perplexity.com`
- `openai.com`
- `anthropic.com`
A week after publishing llms.txt, you should see an uptick.
---
## Does llms.txt Actually Matter?
Yes, llms.txt matters in practice even though it is advisory and not legally required. Major AI engines including Perplexity, Claude, and ChatGPT recognize the file and use it to determine attribution preferences. Sites with llms.txt configured tend to receive more consistent citations and better crawl coverage from AI systems within four to eight weeks.
**Short answer:** Yes, but not as much as robots.txt.
**Longer answer:**
- **Required by law:** No, it's advisory
- **Followed by all AI engines:** Not yet (but major ones do)
- **Necessary for indexing:** No, but it helps
- **Better than nothing:** Absolutely
Think of it like the difference between:
- A locked door (robots.txt: blocks crawling)
- A welcome mat with terms (llms.txt: invites crawling with rules)
You still need the robots.txt. But llms.txt gets you better attribution and signaling.
---
## The Future of llms.txt
Standards bodies like IETF and W3C are discussing llms.txt as a formal standard. As it becomes more official:
1. AI engines will prioritize crawling sites with llms.txt
2. LLMs will automatically cite in your preferred format
3. Licensing and commercial rights will be more enforceable
For now, it's early adoption. But early adopters get:
- Better attribution from AI engines
- Clearer signal to crawlers
- Documented content policy (good for SEO too)
The timing advantage is real. When ChatGPT or Perplexity improves their citation systems, and they will, because user trust depends on source attribution, the sites that already have clear llms.txt policies will be prioritized over sites where the AI engine has to guess. You are building citation infrastructure now that will compound as AI search grows. The same logic applies to [structured data and schema markup](/blog/aeo-answer-engine-optimization-explained), the earlier you adopt, the more crawl history and citation data accumulates in your favor.
---
## llms.txt and the Evolving AI Content Ecosystem
The emergence of llms.txt reflects a broader shift in how content creators relate to AI systems. For the past two decades, the relationship between websites and search engines was mediated by a single file: robots.txt. That file was designed for a world where crawlers fetched pages, indexed keywords, and ranked results. The crawler's job was discovery and ranking. The content stayed on your site, and users clicked through to read it.
AI engines fundamentally change this dynamic. When a user asks ChatGPT a question, the AI synthesizes an answer from multiple sources and presents it directly. The user may never visit your site at all. This means the old model of "let crawlers in, they send traffic back" no longer applies cleanly. AI engines consume your content and may deliver the value to the user without a click. llms.txt is the first attempt to create a new social contract for this relationship: you let AI engines use your content, and in return, they attribute it properly so that users know where the information came from and can choose to visit your site for more depth.
This is not a solved problem. The current llms.txt format is informal, advisory, and unevenly adopted. But the direction is clear. As AI search grows, and it is growing rapidly, with Perplexity alone processing millions of queries daily, creators who have clear, machine-readable content policies will be better positioned than those who remain silent. Silence is ambiguous, and ambiguity favors the platform, not the creator.
The practical takeaway is straightforward: spend five minutes creating an llms.txt file today, and you are ahead of ninety-five percent of websites. The standard will evolve, but having any explicit policy is better than having none. You can always update the file as best practices solidify. What you cannot do is retroactively claim attribution for the months when your content was being used without any policy in place.
## Checklist: Set Up llms.txt
- [ ] Create file at `/llms.txt`
- [ ] Include attribution format
- [ ] Link to sitemap.xml
- [ ] Link to RSS feed
- [ ] Specify excluded content
- [ ] Add contact email for questions
- [ ] Test with `curl https://chudi.dev/llms.txt`
- [ ] Announce on Twitter/LinkedIn
- [ ] Monitor Perplexity citations week 1-4
---
## Measuring llms.txt Impact on Your Content
Setting up llms.txt is one thing. Measuring whether it's actually working is another. The infrastructure is new enough that most analytics tools don't have native llms.txt tracking yet. But you can observe the impact indirectly.
### Tracking Citation Changes
Start tracking your current citation baseline BEFORE setting up llms.txt:
1. Search your site name in Perplexity, note how many results cite you and in what format
2. Search common queries you'd expect your content to answer (e.g., "ADHD and productivity"), capture screenshots of current attribution
3. Repeat the same searches weekly for 4 weeks after deploying llms.txt
What you'll likely see: citations move from sporadic to consistent, and the format increasingly matches your preferred citation style. One creator reported 3x increase in Perplexity citations within 6 weeks of adding llms.txt with explicit citation format instructions.
### Server Logs & Referral Traffic
Enable detailed logging for referrals from AI engines. Check your analytics dashboard for:
- Traffic from `perplexity.com` referrer (often appears as direct, but you can trace it)
- Traffic from `openai.com` (ChatGPT search and plugin references)
- Traffic from `anthropic.com` (Claude search, coming in 2026)
Most sites with llms.txt see a small but measurable uptick in "direct" traffic that you can attribute to AI search referrals. The traffic isn't massive (not like Google), but it's concentrated and high-intent, these are people asking AI systems questions and following the generated citations back to your site.
### SEO Secondary Effects
llms.txt itself doesn't affect Google ranking. But the behavior it enables does:
- **More inbound links from AI answers** → Higher domain authority (slow effect, 3-6 months)
- **Lower bounce rate from AI referrals** → Better engagement signal
- **Branded search visibility** → People search your name after seeing it cited, improving brand recall
The SEO value isn't direct. It's that llms.txt positions your content better upstream, which flows downstream to traditional SEO.
---
## Common Implementation Gotchas
### Gotcha 1: Forgetting the Sitemap Link
Many creators add llms.txt but forget to include the sitemap URL. AI crawlers find pages two ways:
1. Following links from your homepage
2. Checking the sitemap (if you link to it)
Without the sitemap link, crawlers discover only top-level pages and pages linked from your nav. Blog archives, portfolio details, and deeply nested pages might be skipped.
**Fix:** Always include both `sitemap.xml` and RSS feed URLs in your llms.txt.
### Gotcha 2: Making Attribution Too Restrictive
Some creators specify citation format so narrowly that crawlers treat it as legally risky. Example: "Must cite as [Title] by [Author] (site.com) or don't use at all."
This is advisory, not legally binding. But crawlers are conservative. If the policy feels overly restrictive, they might skip your site rather than risk a citation violation.
**Better approach:** Specify preferred format but allow flexibility. Example: "Preferred: [Title] by [Author] on yoursite.com. Acceptable: Article title with link."
### Gotcha 3: Conflicting robots.txt and llms.txt
If `robots.txt` blocks all crawlers with `User-agent: *` and `Disallow: /`, then llms.txt becomes useless, you've already said "no crawling allowed."
llms.txt is a refinement on top of robots.txt, not a replacement. The order is:
1. Check robots.txt → if blocked, stop
2. Check llms.txt → if explicit policy, follow it
3. Use default assumptions → treat site as opt-out
**Fix:** Make sure robots.txt permits crawlers to access the paths you want indexed.
### Gotcha 4: Not Versioning or Dating the Policy
llms.txt is new. Standards might change. Crawlers might update. If you never update your llms.txt, you'll fall behind.
At minimum:
- Add a "Last updated" date (forces you to think about freshness)
- Include a version number
- Monitor crawler behavior quarterly
---
## Real-World Adoption: Who's Using llms.txt?
Early adopters include:
- **Tech blogs and documentation sites**, Want deep indexing by Claude and ChatGPT for technical Q&A
- **News publishers and media sites**, Want proper attribution in AI-generated news summaries
- **Educational platforms**, llms.txt gives them granular control over how content is used
- **Creator platforms** (Substack, Medium), Want to compete with Google for AI-driven discovery
Most consumer blogs? They're still ignoring it. Most of the internet doesn't have llms.txt yet. This means adopting early gives you a small competitive advantage, you're signaling to crawlers that you welcome them, while competitors are silent.
---
## How I Implemented llms.txt on My SvelteKit Blog
When I added llms.txt to chudi.dev, I chose the dynamic route approach over a static file. The reason was simple: I wanted the sitemap URL, post count, and last-updated date to stay accurate without manual updates. A static file in the public directory would go stale the moment I published a new post and forgot to update it.
The implementation took about twenty minutes. I created a server route that reads the blog post metadata at build time, counts the total published posts, finds the most recent publication date, and renders the llms.txt content with those values interpolated. The route returns plain text with the correct content type header so crawlers parse it as a text file rather than HTML.
The content itself follows the balanced attribution model from the policies section above. I explicitly welcome AI training and answer generation, specify my preferred citation format, link to both the sitemap and RSS feed, and exclude draft posts and archived content older than two years. I also include a machine-readable JSON block with licensing information because some crawlers parse structured metadata more reliably than natural language instructions.
One decision I made early was to include a section listing my content pillars and the types of questions each pillar answers. This gives AI engines a semantic map of my site that goes beyond what a sitemap provides. A sitemap tells a crawler which URLs exist. The pillar section tells it what topics those URLs cover and what kinds of user queries they can answer. This distinction matters because AI engines are not just indexing pages, they are building knowledge graphs, and explicit topic mapping helps them place your content in the right nodes.
After deploying, I tested the implementation by fetching the URL with curl and verifying the content rendered correctly. I also searched my site name in Perplexity and noted the baseline citation format before the llms.txt could take effect. Four weeks later, I repeated the search and found that citations had shifted from inconsistent domain-only references to the preferred format I specified in the file. The sample size was small, about twelve citations across different queries, but the pattern was clear.
The maintenance burden is effectively zero because the route generates dynamically. When I publish a new post, the post count and last-updated date update automatically on the next build. The only manual update I foresee is if the llms.txt standard evolves to include new fields or if I change my licensing terms.
## Why Most Sites Get llms.txt Wrong
The most common mistake I see when reviewing other sites' llms.txt implementations is treating it as a legal document rather than a communication tool. Long paragraphs of legalese about intellectual property rights, DMCA provisions, and liability disclaimers miss the point entirely. AI crawlers are not lawyers. They are parsers looking for structured signals about how to handle your content.
The second most common mistake is being too vague. Saying "please attribute properly" without specifying a format gives the AI engine nothing actionable to work with. You need to spell out exactly what a correct citation looks like: the article title, your name, your domain, and ideally a link back to the original URL. The more specific you are, the more likely the AI engine will match your preference.
A third mistake is forgetting to update the file after initial creation. I have seen sites where the llms.txt references a sitemap URL that no longer exists, or lists content categories that were reorganized months ago. Stale metadata is worse than no metadata because it actively misleads crawlers. If you include a last-updated date (and you should), treat it as a commitment to actually review the file when that date approaches.
The fourth and most subtle mistake is not aligning llms.txt with your actual content strategy. If your business model depends on gated content behind a paywall, but your llms.txt says "all content available for training," you are giving away the content you charge for. Conversely, if you are a creator who wants maximum visibility, an overly restrictive llms.txt that requires permission for every use case will reduce your AI search presence. The policy should reflect your actual goals, not a generic template you copied from a tutorial.
## What's Next?
After setting up robots.txt and llms.txt, focus on structured data using schema.org markup, content structure with semantic headers and lists, and content freshness by updating articles regularly. These three areas improve how AI engines parse and extract your content, which directly affects how often you are cited in AI-generated answers.
Once you have robots.txt and llms.txt set up, focus on:
1. **Structured data** (schema.org), Helps AI parse your content
2. **Content structure** (headers, lists), Makes extraction easier
3. **Freshness** (update articles), Recent content ranks higher
4. **Specificity** (answer common questions directly), Better for AI synthesis
The combination of these creates what we call **AEO (Answer Engine Optimization).** For a complete walkthrough of these techniques, see my [full AEO optimization guide](/blog/how-to-optimize-for-perplexity-chatgpt-ai-search).
**Start here:** Add llms.txt to your site today. It takes 5 minutes and can improve your visibility in AI search engines.
Then, run a full AI-citability audit at [citability.dev](https://citability.dev/?utm_source=chudidev&utm_medium=referral&utm_campaign=llms-txt-robots-txt-for-ai-crawlers) to measure exactly which AI engines are citing your URLs and where the gaps are.
Sites with both `robots.txt` and `llms.txt` properly configured consistently see better AI crawl coverage and citation rates within 4-8 weeks of implementation, the infrastructure compounds over time as AI systems return to re-index updated content.
--- END POST ---
================================================================================
POST: Reduce Claude Token Usage 60%: Progressive Disclosure
================================================================================
URL: https://chudi.dev/blog/reduce-ai-token-usage-progressive-disclosure
Date: 2026-01-17T00:00:00.000Z
Tags: claude-code, ai, tokens, optimization, workflow
Pillar: ai-building
Reading Time: 11 min
Word Count: 2199
TL;DR: I was burning through $50/month in Claude API costs before I realized the problem. Every session loaded 8,000 tokens whether I needed them or not. Progressive disclosure flips this: metadata first (~200 tokens), schemas on demand (~400 tokens), full content only when needed. Well, it's more like paying for what you actually use.
Key Takeaways:
- A 2,400-line CLAUDE.md loading fully on every session wastes tokens and hits context limits mid-task
- Tier 1 (metadata): skill names and triggers only (~200 tokens), loads immediately
- Tier 2 (schema): input/output types and constraints (~400 tokens), loads on activation
- Tier 3 (full): handler logic and examples (~1200 tokens), loads only for complex tasks
- Counter-intuitively, less context = better output because the AI parses less noise to find what matters
--- CONTENT ---
I was burning through $50/month in Claude API costs before I realized the problem. Every session loaded the same 8,000 tokens of context--rules, skills, examples--whether I needed them or not.
Progressive disclosure in AI context management means loading information in tiers: metadata first for routing, schemas on demand for understanding, and full content only when actively using a feature. The result? 60% fewer tokens consumed with better output quality, because the AI isn't parsing through irrelevant context to find what matters. [Claude's context window documentation](https://docs.anthropic.com/en/docs/about-claude/models/overview) outlines the token limits that make this kind of optimization essential for longer sessions.
## Why Was I Wasting So Many Tokens?
You waste tokens when your entire context file loads on every session regardless of what you are doing. A 2,400-line CLAUDE.md containing every skill definition, constraint, and example costs thousands of tokens upfront, even for a quick one-line fix. Most sessions only need a fraction of that content to produce accurate results.
My original CLAUDE.md file was 2,400 lines. Every skill definition. Every constraint. Every example. It loaded completely on every single session.
That specific dread of seeing "context limit reached" mid-task--when you're 80% done and suddenly the AI forgets everything--became a weekly occurrence.
I thought more context was always better. If the AI knows everything, it can handle anything. Right? [Anthropic's documentation](https://docs.anthropic.com) actually recommends against bloated system prompts for exactly this reason--focused context produces more reliable outputs.
Well, it's more like... drowning in information isn't the same as understanding what matters.
## How Does the 3-Tier System Work?
The 3-tier system loads context in stages based on what you actually need. Tier 1 loads only skill metadata, names and triggers, at around 200 tokens. Tier 2 loads schemas and constraints when a skill activates, around 400 tokens. Tier 3 loads full handler logic and examples only for complex tasks, around 1,200 tokens.
Progressive disclosure splits context into three tiers, each loading only when needed.
### Tier 1: Metadata (~200 tokens)
The routing layer. Just enough to know what skills exist and when to activate them.
```markdown
## Skill: sveltekit_architect
**Triggers:** routes, layouts, prerender
**Dependencies:** None
**Priority:** High for SvelteKit projects
```
This is all that loads initially. Skill names, trigger patterns, quick reference. The AI knows the skill exists without knowing everything about it.
### Tier 2: Schema (~400 tokens)
The contract layer. Input/output types, constraints, quality gates.
```markdown
### Input Schema
- operation: "analyze_routes" | "create_layout" | "optimize_prerender"
- targetPath?: string
### Output Schema
- success: boolean
- summary: string
- nextActions: string[]
### Constraints
- Svelte 5 runes only
- Prerender for static pages
- Bundle under 300KB
```
This loads when the skill activates--when you're actually working with routes. Not before.
### Tier 3: Full Content (~1200 tokens)
The implementation layer. Complete handler logic, examples, edge cases.
```markdown
### Handler: analyze_routes
1. Glob all `src/routes/**/+page.svelte`
2. Check each for data loader presence
3. Verify prerender config matches content type
4. Return recommendations
### Example Output
{
"success": true,
"summary": "Found 12 routes, 3 missing data loaders",
"nextActions": ["Add +page.server.ts to /blog/[slug]"]
}
```
This only loads when you're deep into a complex routing task. Most sessions never need it.
## What Are the Actual Token Savings?
Progressive disclosure saves 60 to 92 percent of tokens per session depending on complexity. A skill that loads 3,302 tokens in full costs only about 200 tokens at Tier 1. Most sessions only activate one or two skills, so the majority of your context never loads at all.
Here's the meta-orchestration skill as a real example:
| Tier | Lines | Tokens | When Loaded |
|------|-------|--------|-------------|
| Tier 1 | 278 | ~200 | Every session |
| Tier 2 | 816 | ~600 | On skill activation |
| Tier 3 | 3,302 | ~2,400 | Complex tasks only |
Without progressive disclosure: 2,400 tokens loaded every session.
With progressive disclosure: 200 tokens for most sessions, 600 for active skill use.
**Savings: 60-92% depending on task complexity.**
I load less to get more. The paradox makes sense once you see it in practice.
## How Does Smart Mode Auto-Detect Verbosity?
Smart mode analyzes your query and selects from four verbosity levels automatically. Simple questions trigger Minimal mode, loading only Tier 1 at around 500 tokens. Standard tasks load activated Tier 2 skills at around 1,500 tokens. Complex implementations load full tiers for active skills at 4,000 tokens. Deep debugging loads everything at 8,000 tokens.
The system doesn't just have three tiers--it has four verbosity levels that auto-adjust:
Smart mode analyzes your query and picks the level. Simple questions get minimal context. Architecture questions get everything.
## What Is the Lazy Module Loader Pattern?
The lazy module loader pattern imports skill files and reference docs only when your task explicitly references them, instead of loading everything upfront. Each module caches for 10 minutes and expires when unused. Deduplication ensures the same module never loads twice in one session, regardless of how many times it is referenced.
Beyond skill tiers, the system uses lazy loading for expensive modules:
```javascript
// Instead of:
import { allSkills } from './skills'; // 8,000 tokens
// Use:
const getSkill = (name) => {
return import('./skills/' + name + '.md');
};
```
### Features
- **Dynamic imports**: Load modules only when referenced
- **10-minute TTL**: Cache loaded modules, expire unused ones
- **Deduplication**: Never load the same module twice per session
This pattern works for skill files, reference docs, and example repositories. Anything that doesn't need to exist in context until explicitly requested.
## How Do Skill Bundles Reduce Redundant Loading?
Skill bundles group related skills into a single deduplicated unit that activates together. Instead of loading three separate frontend skills with overlapping context, one frontend bundle activates and shares content between them. This eliminates redundant token usage when working across related skills and keeps the total context smaller than loading each skill independently.
Related skills often load together. Instead of loading them individually:
```json
{
"frontend-bundle": {
"skills": ["react-patterns", "tailwind-stylist", "component-testing"],
"tokens": 4500,
"triggers": ["*.tsx", "*.css", "component"]
}
}
```
When you're working on frontend code, the bundle activates as a unit. No loading three separate skills with overlapping context--one bundle with deduplicated content.
### Current Bundles
- **frontend-bundle**: React, UI/UX, web standards (4,500 tokens)
- **backend-bundle**: API, database, patterns (4,200 tokens)
- **debugging-bundle**: Error resolution, testing (2,500 tokens)
- **workflow-bundle**: Git, CI/CD, deployment (3,200 tokens)
Each bundle is optimized to eliminate redundancy between related skills.
## What's the Token Budget System?
The token budget system enforces hard context limits with automatic responses at each threshold. At 60 percent usage it starts dropping inactive skills to lower tiers. At 75 percent it stops loading new context. It always reserves 20 percent for AI responses. When limits approach, it summarizes and compresses old context before hitting the ceiling.
The context governor enforces hard limits:
- **75% max budget**: Never exceed this regardless of task
- **60% warning threshold**: Start aggressive tier reduction
- **20% reserve**: Always keep space for AI responses
When approaching limits:
1. **Phase unloading**: Release completed phase context
2. **Tier reduction**: Drop to lower tiers for inactive skills
3. **Auto-compact**: Summarize and compress old context
4. **Graceful degradation**: Warn before hitting hard limits
That anxiety of context overflow--the system makes it manageable by budgeting proactively.
## FAQ: Token Optimization for AI Tools
**What is progressive disclosure in AI context management?**
Progressive disclosure loads AI context in tiers: metadata first (~200 tokens), schemas on demand (~400 tokens), full content only when needed (~1200 tokens). This prevents loading thousands of unused tokens upfront.
**How much can progressive disclosure save on AI costs?**
In practice, progressive disclosure saves 40-60% of tokens per session. A skill that would load 3,302 tokens fully only loads 278 tokens at Tier 1--unless you actually need the deeper content.
**Does loading less context hurt AI performance?**
Counter-intuitively, no. Focused context with relevant information outperforms bloated context with everything. The AI processes fewer tokens to find what matters, leading to more accurate responses.
**What are the three tiers in progressive disclosure?**
Tier 1 is metadata (name, triggers, dependencies). Tier 2 is schema (input/output types, constraints). Tier 3 is full content (handler logic, examples). Each tier loads only when needed based on task complexity.
**How do I implement progressive disclosure for Claude Code?**
Split your CLAUDE.md into a router file (~500 lines) and reference files (loaded on demand). Use skill activation scores to determine which tier to load. Start with metadata, escalate to full content only for complex tasks.
---
## Real Token Savings: What the Numbers Actually Look Like
Theory is one thing. Here's what three weeks of session data showed in practice.
I tracked token usage across 47 sessions--ranging from quick bug fixes to multi-hour feature implementations. Before implementing progressive disclosure, every session loaded my full CLAUDE.md: 2,400 lines, approximately 8,200 tokens consumed before I'd typed a single character.
After the 3-tier system:
| Session type | Old usage | New usage | Savings |
|--------------|-----------|-----------|---------|
| Quick fix (under 20 min) | 8,200 | 320 | 96% |
| Standard feature | 8,200 | 1,840 | 78% |
| Complex architecture | 8,200 | 4,100 | 50% |
| Deep debugging session | 8,200 | 6,800 | 17% |
The quick fixes were the biggest surprise. I was burning 8,200 tokens to answer "what's the right Svelte 5 syntax for this component?"--when the answer needed maybe 200 tokens of context to be accurate.
The 60% average savings held across all session types. Complex architecture sessions saved less because they genuinely need the full skill content. But those sessions are maybe 15% of my total Claude usage. The other 85% are standard features and quick fixes where I was wildly overloading context.
One concrete month: April to May after switching. My Claude API bill dropped from $51 to $19. Same work output. Same code quality. Just the difference between loading everything and loading what's needed.
The counterintuitive part: output quality stayed the same or improved. On the quick fixes especially, removing irrelevant context meant Claude wasn't filtering through 8,000 tokens of routing rules and schema definitions to answer a simple syntax question. The focused context got more focused answers.
The $32 monthly savings was a side effect. The main effect was fewer mid-session context limits hitting right when I needed them least. That quality-of-life improvement mattered more than the cost reduction.
I thought the solution to context limits was bigger context windows. Well, it's more like... the solution was loading less, more intentionally.
Maybe the goal isn't maximum context. Maybe it's minimum necessary context--and systems that know the difference. For retrieval-based approaches to the same problem, the [RAG paper by Lewis et al.](https://arxiv.org/abs/2005.11401) pioneered how on-demand retrieval can substitute for loading all knowledge upfront.
---
## Update (June 2026): The Five Behaviors That Actually Move Cost
A year of running this system surfaced a second layer the 3-tier architecture doesn't cover: token cost is not primarily a prompting problem. It is a session design problem. After instrumenting token audits across my production harness, the expensive behaviors ranked like this.
**Pattern 1: Cache prefix mutation.** The single biggest lever, and the one I could not see without measuring it. The Anthropic prompt cache holds the stable prefix of a conversation for five minutes. When a turn reuses that prefix unchanged, the cached portion bills at roughly 10% of normal input cost. When the prefix changes, even by one line, the cache invalidates and the whole prefix re-bills at full cost. At a 15,000-token prefix (a CLAUDE.md plus a few rules files), editing instructions mid-session costs 15,000 tokens every turn for the rest of the session. In a 40-turn session, that is 600,000 tokens of avoidable cost. The rule is not "edit less." It is "edit at the right moment": batch all CLAUDE.md and rules edits to session end.
**Pattern 2: Reading whole files to find one function.** A 3,000-line module read to find one function costs 3,000 tokens. Grep for the function name, then read the 50 relevant lines with an offset, and it costs roughly 100. Search first, read narrowly second.
**Pattern 3: Exploratory investigation in main context.** An investigation that reads 10 files and hits 3 dead ends permanently loads all of it into the conversation. A subagent runs the same investigation and returns "the bug is in line X because Y" in 500 tokens. The trigger: if a task is exploratory and likely to hit dead ends, it belongs in a subagent. The main agent should receive conclusions, not the investigation trail.
**Pattern 4: Re-reading stable context.** If the same files are read repeatedly across turns, that is a context design failure. Structure the session so stable context loads once at the start. This is the practical argument for well-structured CLAUDE.md files: they pay for themselves by eliminating re-read costs in long sessions.
**Pattern 5: Over-scaffolded output.** Verbose completion messages and repeated summaries accumulate in the conversation and cost tokens on every subsequent turn. Compact output compounds as sessions lengthen.
Two harness changes followed. A post-session audit flags any CLAUDE.md edit that happened before turn 30 in a session over 40 turns; every flag was a cache invalidation that paid for nothing. And a dispatch rule routes investigation language ("why is," "find out," "figure out why") to a subagent by default.
Neither change touched how I prompt. They changed when behaviors happen in a session. The expensive behaviors are the invisible ones: mid-session instruction edits, whole-file reads, exploratory dead ends accumulating in main context. Measure those before optimizing prompts.
---
## Related Reading
This is part of the [Complete Claude Code Guide](/blog/claude-code-complete-guide) and the full [tools and resources collection](/products). Continue with:
- [Quality Control System](/blog/how-i-build-with-claude-code) - Two-gate enforcement that blocks "should work"
- [Context Management](/blog/claude-context-management-dev-docs) - Dev docs workflow that prevents context amnesia
- [Evidence-Based Verification](/blog/ai-code-verification-evidence-based) - Why confidence without proof fails
- [Claude Prompt Caching Cost](/blog/claude-prompt-caching-cost) - What a cache write and read cost on each model, and when caching pays
- [Claude Usage Limits](/blog/claude-usage-limits) - How the five-hour and weekly limits work, and what uses them up
--- END POST ---
================================================================================
POST: unpdf: Serverless PDF Parsing for Node That Works on Vercel
================================================================================
URL: https://chudi.dev/blog/serverless-pdf-processing-unpdf-vs-pdfparse
Date: 2026-01-17T00:00:00.000Z
Tags: pdf, serverless, vercel, nodejs, tutorial, debugging
Pillar: automation
Reading Time: 8 min
Word Count: 1436
TL;DR: pdf-parse crashed my Vercel deployment at 2 AM. Native dependencies don't work on serverless. After hours of debugging, I switched to unpdf, a library built specifically for serverless environments. Zero native dependencies, works on Vercel out of the box, and processes PDFs in 3-5 seconds. If you're doing PDF processing on serverless, save yourself the pain.
Key Takeaways:
- pdf-parse has native dependencies (canvas, pdfjs-dist) that fail on Vercel's serverless runtime
- unpdf is built for serverless: zero native deps, works on Vercel, Netlify, Cloudflare Workers
- Pattern-based text extraction achieves 99% accuracy for structured documents like bank statements
- Processing time: 3-5 seconds per PDF on Vercel's free tier
- The fix took 2 hours, knowing this upfront saves you the debugging
--- CONTENT ---
unpdf is an npm package that parses PDFs in Node without native dependencies, which is why it runs on Vercel and Edge runtimes where pdf-parse fails on its canvas dependency. Teams building serverless PDF processing lose hours, sometimes a shipped deploy, to that failure, and it often does not surface until production. Here is the fix and the migration path, plus what it cost to find it.
It was 2 AM. StatementSync was ready to deploy. I pushed to Vercel and watched the build fail.
```
Error: Cannot find module 'canvas'
at Function.Module._resolveFilename
```
Canvas? I'm processing PDFs, not drawing graphics. Three hours later, I learned why pdf-parse breaks on serverless.
pdf-parse depends on the canvas module, which requires native bindings unavailable in Lambda and Edge environments. The fix is [unpdf](https://github.com/unjs/unpdf), a pure JavaScript PDF parser with zero native dependencies that works on [Vercel serverless functions](https://vercel.com/docs/functions), AWS Lambda, and Cloudflare Workers. Same extraction quality, no build failures.
## Why Does pdf-parse Fail on Vercel Serverless?
pdf-parse depends on pdfjs-dist, which has optional native dependencies including the canvas module. Canvas requires Python, node-gyp, and C++ build tools that Vercel's serverless runtime cannot compile. The result is either a build-time failure or a silent runtime segfault when the function first processes a PDF in production.
## The Problem
[pdf-parse](https://www.npmjs.com/package/pdf-parse) is the go-to library for PDF text extraction in Node.js:
```typescript
import pdf from 'pdf-parse';
const dataBuffer = fs.readFileSync('statement.pdf');
const data = await pdf(dataBuffer);
console.log(data.text);
```
Works perfectly locally. Crashes spectacularly on Vercel.
### Why It Fails
pdf-parse depends on pdfjs-dist, Mozilla's PDF.js port for Node. pdfjs-dist has optional dependencies:
```
{
"optionalDependencies": {
"canvas": "^2.x",
"node-fetch": "^2.x"
}
}
```
Canvas is a native module that requires:
- Python
- node-gyp
- C++ build tools
Vercel's serverless runtime doesn't have these. The build either:
1. Fails outright with missing module errors
2. Succeeds but crashes at runtime with segfaults
Sometimes the build passes but the function crashes when processing PDFs. This is worse, you discover it in production, not deployment. This kind of silent failure is exactly why [evidence-based verification](/blog/ai-code-verification-evidence-based) matters, trust runtime proof, not build success.
## The Debugging Journey
### Attempt 1: Exclude Canvas
"Just mark canvas as external," Stack Overflow said.
```javascript
// next.config.js
module.exports = {
webpack: (config) => {
config.externals = [...(config.externals || []), 'canvas'];
return config;
},
};
```
Result: Different error.
```
Error: Could not load the "canvas" module
```
pdfjs-dist tries to load canvas at runtime, not just build time.
### Attempt 2: Legacy Build
"Use pdf-parse legacy mode," another answer suggested.
```typescript
const pdf = require('pdf-parse/lib/pdf-parse');
```
Result: Still fails. The dependency chain remains.
### Attempt 3: pdfjs-dist Directly
"Skip pdf-parse, use pdfjs-dist with worker disabled."
```typescript
import * as pdfjsLib from 'pdfjs-dist';
pdfjsLib.GlobalWorkerOptions.workerSrc = '';
const pdf = await pdfjsLib.getDocument({ data: buffer }).promise;
```
Result: Works locally, memory errors on Vercel.
Vercel functions have 1GB memory limit. pdfjs-dist's memory usage is unpredictable with large PDFs.
### The Solution: unpdf
After three hours, I found [unpdf](https://github.com/unjs/unpdf):
```typescript
import { getDocument, extractText } from 'unpdf';
const pdf = await getDocument({ data: buffer }).promise;
const text = await extractText(pdf);
```
Result: Works. First try.
## Why Does unpdf Work Where pdf-parse Fails?
unpdf is a pure JavaScript PDF parser with zero native dependencies. It requires no compilation step, works on Vercel serverless, AWS Lambda, and Cloudflare Workers, and keeps memory usage predictable rather than unpredictable. The same `getDocument` and `extractText` API works identically across local development and production without any environment-specific configuration.
## Why unpdf Works
unpdf is built specifically for serverless:
| Feature | pdf-parse | unpdf |
|---------|-----------|-------|
| Native deps | Yes (canvas) | No |
| Vercel compatible | No | Yes |
| Edge runtime | No | Yes |
| Bundle size | Large | Small |
| Memory usage | Unpredictable | Controlled |
The library uses a pure JavaScript PDF parser without native modules. No build-time compilation, no runtime loading issues.
## Implementation
Here's the complete pattern for serverless PDF processing:
```typescript
import { getDocument, extractText } from 'unpdf';
interface Transaction {
date: string;
description: string;
amount: number;
type: 'debit' | 'credit';
}
async function processPdf(buffer: Buffer): Promise {
// Load PDF
const pdf = await getDocument({ data: buffer }).promise;
// Extract text
const text = await extractText(pdf);
// Parse transactions (pattern-based for bank statements)
const transactions = parseTransactions(text);
// Cleanup
pdf.destroy();
return transactions;
}
function parseTransactions(text: string): Transaction[] {
// Bank-specific parsing patterns
const lines = text.split('\n');
const transactions: Transaction[] = [];
for (const line of lines) {
const match = line.match(/(\d{2}\/\d{2})\s+(.+?)\s+(-?\$[\d,]+\.\d{2})/);
if (match) {
transactions.push({
date: match[1],
description: match[2].trim(),
amount: parseFloat(match[3].replace(/[$,]/g, '')),
type: match[3].startsWith('-') ? 'debit' : 'credit'
});
}
}
return transactions;
}
```
## Performance
On Vercel's free tier (1GB memory, 10s timeout):
| PDF Size | Processing Time | Memory Used |
|----------|-----------------|-------------|
| 1 page | 1-2 seconds | ~100MB |
| 5 pages | 3-4 seconds | ~200MB |
| 10 pages | 5-6 seconds | ~350MB |
| 20 pages | 8-9 seconds | ~500MB |
Comfortable margins for typical bank statements (1-5 pages).
Always call `pdf.destroy()` after processing. unpdf holds the document in memory until explicitly released.
## When Should You Use Pattern-Based Extraction Instead of LLM?
For structured documents like bank statements and invoices, pattern-based extraction achieves 99% accuracy at zero runtime cost versus $0.01–$0.05 per LLM call. At 1,000 statements per month that difference is $10–$50. For flat-rate SaaS products where marginal cost must stay near zero, pattern-based parsing is the only pricing-sustainable choice.
## Pattern-Based vs LLM Extraction
For structured documents like bank statements, pattern-based extraction beats LLM:
| Approach | Accuracy | Cost | Speed |
|----------|----------|------|-------|
| Pattern-based | 99% | $0 | 3-5s |
| LLM (GPT-5) | 99.5% | $0.01-0.05 | 10-30s |
| OCR + LLM | 95% | $0.02-0.08 | 15-45s |
For StatementSync processing 1000 statements/month:
- Pattern-based: $0
- LLM: $10-50/month
The 0.5% accuracy difference doesn't justify the cost for this use case. This cost analysis was a key input to the [flat-rate vs per-file pricing decision](/blog/flat-rate-vs-per-file-saas-pricing) for StatementSync.
## When to Use What
**Use unpdf when:**
- Deploying to Vercel, Netlify, or Cloudflare
- Processing structured documents (statements, invoices)
- Need low memory footprint
- Running on edge runtimes
**Use pdf-parse when:**
- Running on traditional servers (EC2, [DigitalOcean Droplets](https://www.digitalocean.com/))
- Need advanced PDF features (annotations, forms)
- Have native build tools available
**Use LLM extraction when:**
- Documents are unstructured or variable
- Accuracy is more important than cost
- Processing low volumes
## How Do You Set Up unpdf in a Next.js App Router Project?
Install unpdf with `npm install unpdf`, then create a route handler under `app/api/`. Set `export const runtime = 'nodejs'`, not `'edge'`, because unpdf requires Node APIs unavailable on the Edge runtime. Use `formData()` to receive the file, convert it to a buffer with `arrayBuffer()`, call `getDocument` and `extractText`, then call `pdf.destroy()` to release memory.
## Setting Up in Next.js
Installing unpdf and configuring Next.js for serverless PDF processing:
```bash
npm install unpdf
```
No additional configuration needed for standard [Vercel](https://vercel.com) deployments. If you prefer a Railway-hosted Next.js app instead, [Railway](https://railway.com?referralCode=eMKKpV) supports the same setup with persistent server processes that avoid cold starts entirely. For Vercel's App Router, create your route handler:
```typescript
// app/api/process/route.ts
import { NextRequest, NextResponse } from 'next/server';
import { getDocument, extractText } from 'unpdf';
export const runtime = 'nodejs'; // not 'edge' — unpdf needs Node APIs
export async function POST(req: NextRequest) {
const formData = await req.formData();
const file = formData.get('pdf') as File;
if (!file || file.type !== 'application/pdf') {
return NextResponse.json({ error: 'Invalid file' }, { status: 400 });
}
const buffer = Buffer.from(await file.arrayBuffer());
const pdf = await getDocument({ data: buffer }).promise;
const text = await extractText(pdf);
pdf.destroy();
return NextResponse.json({ text });
}
```
One gotcha: set `runtime = 'nodejs'` not `'edge'`. Edge runtime has stricter module constraints. unpdf works on Node runtime, not edge runtime.
## Handling Edge Cases
### Password-Protected PDFs
```typescript
try {
const pdf = await getDocument({
data: buffer,
password: userProvidedPassword // optional
}).promise;
} catch (err) {
if (err.name === 'PasswordException') {
return { error: 'PDF is password protected' };
}
throw err;
}
```
PasswordException is thrown immediately, before any processing. Always catch it explicitly or you'll get an unhandled rejection in production.
### Corrupted or Invalid Files
```typescript
async function safePdfExtract(buffer: Buffer): Promise {
try {
const pdf = await getDocument({ data: buffer }).promise;
const text = await extractText(pdf);
pdf.destroy();
return text;
} catch (err) {
// InvalidPDFException for malformed files
// MissingPDFException for empty or non-PDF data
console.error('PDF extraction failed:', err.name, err.message);
return null;
}
}
```
Return `null` instead of throwing to let the caller decide whether a failed extraction is a hard error or a skippable item.
### Scanned PDFs (Image-Based)
unpdf extracts embedded text. Scanned documents, where each page is a JPEG embedded in a PDF, return empty strings. Before assuming extraction succeeded, check the output:
```typescript
const text = await extractText(pdf);
if (text.trim().length < 50) {
// Likely a scanned document
return { error: 'Document appears to be scanned. Text extraction not supported.' };
}
```
For scanned documents, you'd need OCR (Tesseract.js or an external API like AWS Textract). That's out of scope for most bank statements, major US banks generate text-based PDFs, but worth detecting gracefully.
## Testing the Pipeline
Two tests that catch 90% of production issues:
```typescript
// __tests__/pdf-processing.test.ts
import { processPdf } from '../lib/pdf';
import fs from 'fs';
describe('PDF processing', () => {
it('extracts transactions from Chase statement', async () => {
const buffer = fs.readFileSync('__tests__/fixtures/chase-sample.pdf');
const result = await processPdf(buffer);
expect(result.transactions.length).toBeGreaterThan(0);
expect(result.transactions[0]).toMatchObject({
date: expect.stringMatching(/^\d{2}\/\d{2}$/),
amount: expect.any(Number),
});
});
it('returns null for scanned PDF', async () => {
const buffer = fs.readFileSync('__tests__/fixtures/scanned.pdf');
const result = await processPdf(buffer);
expect(result).toBeNull();
});
});
```
The fixture files are real PDFs (anonymized). Testing against actual bank statement formats catches the edge cases in date parsing and amount formatting before they hit production.
## Verifying Your Setup in Production
Deployment to Vercel can surface issues that local testing misses. Before handling real user data, run three checks.
**Memory ceiling**: The performance table above shows 20-page PDFs using ~500MB. Vercel's free tier allows 1,024MB per function. Test your worst-case PDF during staging, not production. If you're regularly processing PDFs over 15 pages, bump to Vercel's Pro tier where you can configure function memory up to 3,008MB.
**Cold start behavior**: Vercel's serverless functions spin down after inactivity. The first PDF request after a cold start takes 2-4x longer than subsequent requests. If your users frequently trigger that first cold request, consider Vercel's Fluid Compute option that keeps functions warm between invocations.
**File size limits**: Vercel's default payload limit for serverless functions is 4.5MB. A 20-page bank statement PDF typically sits well under 1MB. But if your use case involves scanned PDFs or combined multi-month statements, verify your largest expected file size against this limit before launch. You can adjust it in `next.config.js`:
```javascript
export default {
api: {
bodyParser: {
sizeLimit: '10mb',
},
},
};
```
Running these three checks in staging eliminates the category of production failures that are unrelated to code, infrastructure surprises that happen on first real traffic.
## The Lesson
The right library matters more than clever workarounds. I spent 3 hours trying to make pdf-parse work on serverless. unpdf worked in 10 minutes.
If you're building PDF processing for serverless, start with unpdf. Save yourself the 2 AM debugging.
---
**Related**: [From Pain Point to MVP: StatementSync in One Week](/blog/introducing-microsaasbot-ai-builds-saas) | [Portfolio: StatementSync](/portfolio/statementsync)
---
`WORK WITH ME · WHEN THE NEXT BLOCKER ISN'T A BLOG POST`
> This fix cost me three hours so it costs you ten minutes. When your stack hits a blocker without a write-up, [I take on scoped builds and audits](/services): custom builds from $5,000, MVP builds starting at $500 and shipping in weeks. Fixed scope, fixed price after scoping, full source code and documentation included.
--- END POST ---
================================================================================
POST: RAG Explained: How to Stop LLMs From Making Things Up
================================================================================
URL: https://chudi.dev/blog/what-is-rag
Date: 2026-01-17T00:00:00.000Z
Tags: ai, rag, llm, tutorial
Pillar: ai-building
Reading Time: 7 min
Word Count: 1371
TL;DR: Without me realizing it, I had been using RAG every time I asked Claude to help me understand a codebase. RAG (Retrieval-Augmented Generation) gives LLMs access to external knowledge at inference time. Well, it's more like grounding AI in actual documents instead of hoping training data is enough.
Key Takeaways:
- RAG retrieves relevant documents at inference time, grounding responses in current, factual sources
- The pattern follows query, retrieve, augment, then generate. Context gets added before the LLM responds
- Use cases include documentation chatbots, customer support, research assistants, and code Q&A
- Every time you feed context to Claude before asking questions, you're using the RAG pattern
--- CONTENT ---
## TL;DR
RAG (Retrieval-Augmented Generation) combines language models with real-time data retrieval to provide accurate, up-to-date responses. **Key benefit**: Reduces hallucination by grounding responses in actual documents.
## What is RAG?
RAG (Retrieval-Augmented Generation) is a technique that gives large language models access to external knowledge at inference time. Rather than relying solely on training data that may be months old, RAG retrieves relevant documents and adds them to the prompt before the model generates a response, grounding answers in current, factual sources.
RAG is a technique that gives LLMs access to external knowledge at inference time. Instead of relying solely on what the model learned during training--which could be months or years old--RAG pulls in relevant documents before generating a response.
Without me realizing it, I had been using a form of RAG every time I asked Claude to help me understand a codebase. Feeding it context before asking questions? That's the RAG pattern in action.
### How RAG Works
1. **Query Processing**: User question is received
2. **Retrieval**: Relevant documents are fetched from a knowledge base
3. **Augmentation**: Retrieved context is added to the prompt
4. **Generation**: LLM generates a response using both its training and the retrieved context
I thought RAG was only for enterprise systems. Well, it's more like... the pattern exists everywhere we add context to AI conversations.
### The Three Core Components
Every RAG system has three parts that need to work together:
**Embedding model**: Converts text into vectors, lists of numbers representing semantic meaning. "How do I authenticate users?" becomes a numerical vector where similar questions produce similar vectors. Common choices include OpenAI's `text-embedding-ada-002`, Cohere Embed, or open-source models from `sentence-transformers`. The embedding model determines how well your system understands semantic similarity. Two sentences that mean the same thing should produce vectors that are close together in vector space, even if they use different words.
**Vector database**: Stores those embeddings and enables fast similarity search. When a query arrives, the database finds documents whose embeddings are most similar to the query embedding. Options range from Pinecone (managed cloud) to Chroma (local dev) to pgvector (PostgreSQL extension). For most small-to-medium projects, Chroma locally or pgvector in Supabase is more than sufficient, no need for a dedicated vector database service until you're storing millions of documents.
**Retrieval strategy**: Decides which documents to include and how many. Naive retrieval takes the top-k most similar chunks. Hybrid search combines vector similarity with keyword matching (BM25). Reranking uses a second model to re-score results for relevance. Getting retrieval right often matters more than which database or embedding model you choose.
## Why Does RAG Matter for Builders?
I hated the feeling of asking an AI a question and getting confidently wrong information. But I love being able to trust responses when they're grounded in actual sources.
That specific relief of knowing where information comes from--it changes how you build with AI entirely.
### Common RAG Use Cases
## When Should You Use RAG vs. Fine-Tuning?
Both approaches customize LLM behavior, but they solve different problems.
| | RAG | Fine-Tuning |
|---|---|---|
| Best for | Factual queries, current info | Style, tone, task format |
| Knowledge updates | Instant (update the DB) | Requires retraining |
| Hallucination risk | Lower (grounded in docs) | Higher (model memorizes) |
| Source transparency | Can cite sources | Black box |
| Setup cost | Medium (need vector DB) | High (need training data) |
I tried fine-tuning a model on internal documentation once. Updates required retraining. Months later, the model confidently cited outdated API versions. RAG would have been simpler and more reliable for that use case, the knowledge was too dynamic for fine-tuning.
**Use RAG when:**
- Your knowledge changes frequently (documentation, product updates, news)
- You need to cite sources and show your work
- You're querying factual or domain-specific information
- You want explicit control over what the model can reference
**Use fine-tuning when:**
- You need a specific response format or output structure
- You're adjusting tone or communication style
- Task-specific patterns need to be baked in at training time
- You have thousands of high-quality labeled examples
Most production systems end up using both: fine-tuned models for consistent format and tone, RAG for factual grounding.
## How Do You Get Started with RAG?
Here's a working minimal implementation with ChromaDB and Claude:
```python
import chromadb
import anthropic
# 1. Set up vector store and add documents
client = chromadb.Client()
collection = client.create_collection("docs")
collection.add(
documents=[
"Users authenticate via JWT tokens stored in httpOnly cookies.",
"Database connection uses PostgreSQL on port 5432.",
"API rate limit is 100 requests per minute per IP."
],
ids=["auth", "db", "rate-limit"]
)
# 2. Retrieve relevant context
def retrieve(query: str, n: int = 3) -> list[str]:
results = collection.query(query_texts=[query], n_results=n)
return results["documents"][0]
# 3. Generate with context
anthropic_client = anthropic.Anthropic()
def rag_query(question: str) -> str:
context = retrieve(question)
context_str = "\n".join(f"- {doc}" for doc in context)
response = anthropic_client.messages.create(
model="claude-opus-4-8",
max_tokens=1024,
messages=[{
"role": "user",
"content": f"Use this context to answer the question.\n\nContext:\n{context_str}\n\nQuestion: {question}"
}]
)
return response.content[0].text
print(rag_query("How do users log in?"))
# → "Users authenticate via JWT tokens stored in httpOnly cookies."
```
ChromaDB handles embedding automatically using its default model. For production, swap in a dedicated embedding service and a persistent vector database. The key is step 3, context gets prepended to the prompt before the LLM generates. That's it. That's RAG.
## Common RAG Mistakes
I've made most of these. Some took months to diagnose.
### Chunk size too large
Retrieving entire documents when only one paragraph is relevant. LLMs have context windows, stuffing in irrelevant text wastes tokens and dilutes useful content. Worse, the LLM might confabulate based on unrelated content that got retrieved alongside the correct answer.
**Fix:** Chunk documents into 256–512 token segments with 50-token overlap to preserve context at boundaries.
### Chunk size too small
Splitting so aggressively that context is lost. A 50-word chunk might contain the answer but not the surrounding context that makes it meaningful. "Use bcrypt" without "when storing passwords" misses the point.
**Fix:** Experiment per content type. For prose, 512 tokens with overlap. For code, split by function or class boundary.
### Skipping reranking
Taking top-k vector search results at face value. Vector similarity finds semantically related text but not always the most *relevant* text. A passage about "fast running" can score well for "quick deployment" when you wanted DevOps documentation.
**Fix:** Add a cross-encoder reranker as a second pass. It re-scores results by relevance to the specific query, not just semantic proximity. Slower but significantly more accurate for precision-sensitive use cases.
### Missing metadata filtering
Treating all documents equally. If you have docs for v1 and v2 of an API, you want v2 docs for v2 questions. Vector similarity doesn't understand versioning or recency.
**Fix:** Store metadata (version, date, author, section) alongside embeddings. Filter before or after retrieval based on query context or user-supplied parameters.
### No evaluation
Building RAG and measuring success by feel. "It seems better" is not a metric.
**Fix:** Create a test set of 20–50 question-answer pairs. Measure retrieval precision (did the right document get retrieved?) and answer faithfulness (did the LLM actually use the retrieved content?). Tools like [RAGAS](https://docs.ragas.io/) automate this evaluation loop.
## Production RAG Considerations
The working example above gets you a prototype. Production systems need a few more pieces.
**Chunking strategy matters more than the database.** The most common reason RAG systems underperform isn't the LLM or the vector store, it's that chunks are either too large (stuffing in irrelevant context) or too small (losing surrounding meaning). Start with 512-token chunks with 50-token overlap and test against your actual question set before committing to a strategy.
**Evaluate retrieval separately from generation.** Two distinct failure modes exist: the right document wasn't retrieved, or the right document was retrieved but the LLM generated a bad answer anyway. Evaluate each independently. If retrieval precision is low (wrong documents retrieved), improve embedding quality or add metadata filtering. If answer faithfulness is low (documents retrieved but ignored in the response), improve the system prompt to be more directive about using context.
**Monitor costs in staging.** Embedding thousands of documents at 10,000 tokens each adds up. Audit your embedding cost before scaling to production. For most developer knowledge bases, the one-time embedding cost stays under $5, but knowing that number before you scale matters. OpenAI's `text-embedding-3-small` costs $0.02 per million tokens; for a 500-document knowledge base, that's effectively free at initialization.
---
Since I no longer need to second-guess every AI response, I can focus on what I actually want to build. I like to see it as a comparative advantage--understanding RAG means building more reliable AI applications.
---
## Related Reading
This is part of the [Complete Claude Code Guide](/blog/claude-code-complete-guide) and the [tools and resources collection](/products). Continue with:
- [Quality Control System](/blog/how-i-build-with-claude-code) - Two-gate enforcement for AI code generation
- [Context Management](/blog/claude-context-management-dev-docs) - The dev docs workflow is essentially manual RAG
- [Self-Improving RAG for Claude Code](/blog/self-improving-rag-claude-code) - Building a system that learns from your sessions
--- END POST ---
================================================================================
POST: Human-in-the-Loop AI: Why It Beats Full Automation for Security Tools
================================================================================
URL: https://chudi.dev/blog/why-human-in-the-loop-beats-full-automation
Date: 2026-01-17T00:00:00.000Z
Tags: ai, automation, philosophy, security, bug-bounty
Pillar: philosophy
Reading Time: 10 min
Word Count: 1806
TL;DR: I could have built BugBountyBot to submit findings automatically. I didn't. Not because I couldn't, because full automation in security is a reputation time bomb. One bad submission can undo months of credibility. Human-in-the-loop isn't a compromise. It's the architecture that lets you scale without catastrophic failure modes.
Key Takeaways:
- Full automation in security tools shifts liability unpredictably, you're responsible for what your bot submits
- False positives damage reputation faster than true positives build it
- Platform ToS (HackerOne, Intigriti, Bugcrowd) explicitly require human oversight for automated tools
- Human-in-the-loop is a feature, not a limitation, it's where judgment gets applied
- The goal isn't maximum automation, it's maximum valuable output with acceptable risk
--- CONTENT ---
Human-in-the-loop beats full automation in bug bounty because false positives damage reputation faster than true positives build it. After eight months running BugBountyBot with a human approval step, the accepted-to-submitted ratio stayed above 90% with zero bans and zero private program revocations. The review overhead is four to eight hours per month. The alternative has no ceiling.
I could have built BugBountyBot to submit findings automatically. The technical barrier isn't high, an API call to HackerOne after validation passes.
I didn't build it that way. Here's why.
## Why Is Full Automation Tempting in Security Research?
Full automation promises speed, scale, and the appeal of a system that hunts bugs while you sleep. Every conversation about BugBountyBot arrives at the same question: why not just auto-submit? The answer is that bug bounty rewards precision, not recall, and automated systems optimizing for recall produce false positive rates that destroy the reputation they were supposed to scale.
## The Temptation of Full Automation
Full automation is seductive:
- **Speed**: Submit findings as fast as you find them
- **Scale**: Hunt 24/7 without human bottlenecks
- **Ego**: "I built a system that hunts bugs while I sleep"
Every conversation about BugBountyBot eventually hits this question: "Why not just auto-submit?"
## The False Positive Problem
In security research, reputation is everything. A single bad submission can:
- Get your report closed as "Not Applicable"
- Add a negative signal to your profile
- Cost you access to private programs
- Waste triager time (they remember)
**The math is brutal**: one false positive can undo five true positives in terms of reputation impact.
Automated systems optimize for recall, finding everything possible. But bug bounty rewards precision. A 90% precision rate sounds good until you realize that means 1 in 10 submissions is garbage.
A researcher I know ran automated submissions for a month. Their valid-to-invalid ratio dropped to 60%. Three private programs revoked access. It took six months of manual, high-quality reports to recover.
### The Real Cost of a Reputation Hit
Let's put numbers to it.
A mid-level bug bounty hunter submitting 20 reports per month with 90% validity earns consistent program access and occasional bounties. Now automate without human review and drop to 70% validity:
- Month 1: 6 invalid reports. Triagers notice. No visible consequence yet.
- Month 2: Another 6. Two programs flag your profile internally.
- Month 3: One program marks you as low-priority. Your valid reports now get slower triage.
- Month 4: A private program revokes your invitation.
You just lost access to a private program that might have had $5,000 bounties. How long to earn that back? Six months of clean reports at minimum, and some programs never re-invite once access is revoked.
The math is simple: **one automated false-positive spiral costs more in lost access than the time you saved automating.**
## What Do Bug Bounty Platforms Actually Require from Automated Tools?
HackerOne explicitly prohibits fully automated submission systems and requires human review before any submission. Intigriti holds researchers responsible for the quality of all submissions, including those assisted by automated tools. Bugcrowd warns that automated scanning causing excessive false positives may result in account suspension. Full automation is not a gray area, it violates platform terms of service.
## Platform Requirements
This isn't just my opinion, platforms explicitly require human oversight.
From HackerOne's Automation Policy:
> "Automated tools must have human review before submission. Fully automated submission systems are prohibited."
From Intigriti's Terms:
> "Researchers are responsible for the quality and accuracy of all submissions, including those assisted by automated tools."
From Bugcrowd:
> "Automated scanning that results in excessive false positives may result in account suspension."
Build full automation, and you're violating ToS. Not a gray area.
## The Liability Question
When your bot submits a finding, who's responsible?
- If it's valid: You get credit
- If it's invalid: You get blamed
- If it causes harm: You're liable
There's no "my AI did it" defense. The liability is asymmetric, downside is yours, and "scale" just multiplies it.
Compare this to human-in-the-loop:
- You review each finding before submission
- You apply judgment about timing and context
- You own the decision, not just the consequence
## What Humans Do Better
Automation excels at:
- Pattern matching at scale
- Consistent testing methodology
- 24/7 availability
- Memory across sessions
Humans excel at:
- **Context understanding** - Is this behavior intentional?
- **Impact assessment** - Is this actually a security issue?
- **Communication** - Can I explain this clearly?
- **Timing judgment** - Is now the right time to submit?
The optimal system uses AI for the first set and humans for the second.
## How Is the Human-in-the-Loop Architecture Structured?
BugBountyBot runs three agents, Recon, Testing, and Validator, automatically. Findings above a 0.85 confidence threshold queue for human review with full evidence: the request/response pair, a confidence breakdown, a reproducible proof-of-concept, and a CVSS severity assessment. The human approves, rejects, or edits before the Reporter agent submits. AI handles the 80% grind; humans handle the 20% requiring judgment.
## The Human-in-the-Loop Architecture
BugBountyBot's design:
```
[Recon Agent] → [Testing Agent] → [Validator Agent]
↓
[Confidence ≥ 0.85?]
↓ ↓
Yes No
↓ ↓
[Queue for Review] [Log & Learn]
↓
[Human Review]
↓
[Approve/Reject/Edit]
↓
[Reporter Agent]
```
The human checkpoint is after validation but before submission. You're not reviewing raw signals, you're reviewing high-confidence findings with full evidence.
This is the leverage point: AI handles the 80% grind, humans handle the 20% that requires judgment. The full architecture behind this system is detailed in the [bug bounty automation architecture post](/blog/bug-bounty-automation).
## The Numbers That Matter
| Metric | Full Automation | Human-in-the-Loop |
|--------|-----------------|-------------------|
| Submissions/day | High | Medium |
| Precision | ~70% | ~95% |
| Reputation trend | Declining | Stable/Growing |
| Platform standing | At risk | Solid |
| Sustainable? | No | Yes |
Optimizing for submissions per day is the wrong metric. Optimize for accepted findings per month, reputation over time, and access to better programs.
## When Full Automation Makes Sense
There are legitimate use cases:
- **Internal security testing** - Your own infrastructure, no reputation at stake
- **Private engagements** - Client agreed to automated testing
- **Research environments** - Sandboxed, no real submissions
But for public bug bounty programs? Human-in-the-loop is the only sustainable architecture. The ethical and compliance dimensions of this are explored in [the human-in-the-loop bug bounty ethics post](/blog/bug-bounty-automation).
## How to Design for Human-in-the-Loop
If you're building automation with a human checkpoint, the design matters. A badly designed HITL system creates the worst of both worlds: slow automation with human bottlenecks that still produce false positives.
### Present findings with evidence, not signals
The human shouldn't have to re-investigate. Every item in the review queue should arrive with:
- The full request/response pair showing the vulnerability
- A confidence score with the breakdown (what raised it, what nearly filtered it out)
- A reproducible PoC, one command the reviewer can run to verify
- Severity assessment with CVSS rationale
If a reviewer has to go digging, the handoff is broken.
### Batch similar findings together
Reviewing ten IDOR findings one by one is exhausting and inconsistent. Batch them: show all IDOR findings from the same program in one session. Pattern recognition kicks in. The reviewer can apply consistent judgment across similar cases, and they'll notice if finding #7 looks different from the others.
### Set a minimum confidence floor, not just a threshold
Don't just block low-confidence findings, discard them at the source. If something scores below 0.40, logging it and moving on is correct. A review queue full of 0.41-confidence findings is worse than a queue with nothing: it trains reviewers to rubber-stamp.
The [NIST AI Risk Management Framework](https://www.nist.gov/publications/artificial-intelligence-risk-management-framework-ai-rmf-10) calls this "human oversight commensurate with risk", the human role should be proportional to the stakes, not a checkbox.
### Keep the review cycle short
If findings sit in queue for days, context gets lost. A reviewer looking at a finding two weeks old has to re-read everything from scratch. Set a target: findings should be reviewed within 24–48 hours of queuing. If volume exceeds review capacity, slow down the automation, not the other way around.
## What Does Eight Months of Data Show About Human-in-the-Loop?
After eight months running BugBountyBot with human-in-the-loop, the accepted-to-submitted ratio stayed above 90% consistently. Zero bans. Zero private program revocations. The review overhead runs four to eight hours per month. The alternative, handling reputation damage, disputing invalid submissions, and rebuilding program trust, has no ceiling and no predictable timeline.
## The Long-Term Evidence
I've now run BugBountyBot with human-in-the-loop for eight months. The data makes the case more clearly than any argument.
**Month 1-2 (calibration)**: The system queued 34 findings for review. I approved 18, rejected 16. Twelve of the approved ones were accepted by programs. Six were marked informational, valid but not bounty-eligible. Zero false positives submitted. Nothing I submitted was wrong, just not always in-scope.
**Month 3-4 (dialing in)**: The system queued 28 findings. I approved 22. Twenty were accepted or rewarded. Two were informational. Still no false positive submissions. The RAG database had learned enough false positive signatures that it filtered garbage before it reached the review queue.
**Month 5-8 (steady state)**: Quarterly average of 25 queued, 22-24 approved, 20-22 accepted. My effective submission rate (accepted / submitted) stayed above 90% consistently.
Compare this to the researcher who ran full automation: 60% valid rate by month three, three private program revocations by month four.
The efficiency difference is smaller than it looks. I spend roughly 4-8 hours per month reviewing findings. Each review takes 10-20 minutes including reproducing the PoC. The alternative, handling reputation damage, disputing invalid submissions, rebuilding program trust, has no ceiling and no timeline.
Eight months of data. Zero bans. Zero private program revocations. Consistent accepted-to-submitted ratio above 90%.
That's the case for human-in-the-loop. Not philosophy, evidence.
## The Deeper Point
The goal isn't maximum automation. The goal is maximum valuable output with acceptable risk.
Human-in-the-loop is how you get there. It's not a compromise, it's the architecture that lets you scale without catastrophic failure modes.
**A checklist for evaluating any automation decision:**
- Can the automated component fail silently? (If yes: add logging + human audit)
- Does failure at scale damage relationships? (If yes: add human gate)
- Is the judgment call context-dependent? (If yes: keep a human in the loop)
- Can you reverse a bad automated decision? (If no: add human gate)
Four yeses means full automation. Mixed answers means HITL. All yeses means the human checkpoint is the only path.
Build for sustainability. Your future self will thank you.
The researchers running full automation are chasing a metric, submissions per day, that doesn't correspond to the outcome that actually matters: bounties earned and program access maintained over months and years. Human-in-the-loop is slower on the metric that sounds impressive in a demo and faster on the metric that pays reliably.
---
**Related**: [Building a Semi-Autonomous Bug Bounty System](/blog/bug-bounty-automation) | [Portfolio: BugBountyBot](/portfolio/bugbountybot)
--- END POST ---
Long paragraph explaining the concept...
More context...
Finally, the key insight...
``` **Good structure:** ``` # Article Title ## What is AEO?AEO (Answer Engine Optimization) is the practice of structuring content so AI engines can extract, cite, and surface it in generated answers. It focuses on crawl access, structured data, and answer-first formatting.
## Why does AEO matter for visibility?AI engines like Perplexity and ChatGPT now answer queries directly without sending users to search results. If your content is not optimized for extraction, you are invisible to this growing traffic source.
## How to implement AEOSteps...
## Common mistakesWhat to avoid...
## FAQ - Q1: Answer - Q2: Answer ``` Every 2-3 paragraphs, add a header. This makes it easier for AI to: 1. Find the specific section answering a user's question 2. Extract just that section (not the whole article) 3. Cite the correct part of your content ### Use Lists for Dense Information Instead of: > "To optimize your site, you need to update your robots.txt file, create an llms.txt file, add schema to your articles, and structure your content with headers." Write: > "To optimize your site: > 1. Update robots.txt for AI crawlers > 2. Create llms.txt at site root > 3. Add schema to articles > 4. Structure with semantic headers" AI engines can extract lists more reliably than paragraph prose. ### Put the Answer at the Top Don't make readers scroll for the punchline. If your headline is "Why AEO Matters," answer it in the first paragraph: > "AEO matters because 30% of searches now go through AI engines instead of Google. If your content isn't optimized for Perplexity, ChatGPT, and Claude, you're invisible to an entire audience." Then expand with context, examples, and proof. ### Use Definition Boxes For key concepts, use a highlighted box: ```markdown > **Definition:** AEO (Answer Engine Optimization) is optimizing your content to be found, extracted, and cited by AI search engines. ``` This signals to AI engines: "This is important context." ### Include Tables and Structured Data Tabular data is easier for AI to extract: | Factor | SEO | AEO | |--------|-----|-----| | Ranking | Backlinks | Content structure | | Speed | Important | Less important | Don't just describe in paragraphs. Use tables. --- ## How Do You Know If AI Engines Are Citing Your Content? Search your target keywords directly in Perplexity, ChatGPT search, and Claude. If your site doesn't appear in sources within 4-6 weeks of publishing, you likely have a crawl access problem, a freshness issue, or your content isn't structured as direct answers. Manual citation checks take five minutes weekly. ## Step 5: Monitor Visibility in AI Engines ### Search Your Topics in Perplexity Go to [perplexity.ai](https://perplexity.ai) and search your main keyword. Do you see your content cited? If yes ✅ → Your content is discoverable If no ❌ → You need to audit (usually a robots.txt or freshness issue) ### Check ChatGPT Search OpenAI's ChatGPT now searches the web. Search your site name + keyword. Does your content appear? ### Use Perplexity Citation Tracking When your content is cited, you'll see traffic from `perplexity.com` in your analytics. Track this growth. --- ## 2026 Update: Platform-Specific Citation Strategies Since this article was first published, research has revealed that each AI platform has distinct source preferences. A one-size-fits-all approach to AI search optimization is no longer sufficient. ### Perplexity: The Reddit Connection Perplexity cites approximately 6.6 sources per answer, more than any other platform. Its source pool leans heavily on Reddit, with 46.7% of top-cited sources coming from Reddit discussions. This means genuine participation in subreddits relevant to your expertise (r/SEO, r/webdev, r/artificial) directly increases your chances of being cited. The mechanism: Perplexity indexes Reddit threads and cites them as sources. When your expertise appears in those threads (with or without links to your site), Perplexity associates your knowledge with your brand. ### ChatGPT: Recency and Authority ChatGPT cites only about 2.6 sources per answer, making it the most selective platform. It shows strong preference for Wikipedia (7.8% of all citations) and recently updated content. 95% of ChatGPT citations come from content published or updated within the last 10 months. To improve ChatGPT citations: update your highest-value articles quarterly with new data, add `dateModified` schema, and ensure your content contains specific statistics AI can attribute. ### Google AI Overviews: Still Tied to Rankings Google AI Overviews show 76% overlap with traditional top 10 results, making it the most SEO-correlated AI feature. If you rank well on Google, you're likely to appear in AI Overviews. Focus traditional SEO efforts here. ### Measuring Your AI Visibility You can now audit your site's AI infrastructure readiness with automated tools. [citability.dev](https://citability.dev/scan?utm_source=chudidev&utm_medium=referral&utm_campaign=how-to-optimize-for-perplexity-chatgpt-ai-search) runs 10 checks against your site covering robots.txt, sitemap, structured data, answer-first content, and freshness signals. It measures three tiers: AI visibility (can AI find you?), AI recommendability (does AI suggest you?), and AI citability (does AI link to you?). To measure your citation rate directly, query ChatGPT, Perplexity, and Claude with 20 questions your site should answer. Track two metrics per query: whether the AI mentions your brand (visibility) and whether it links to a URL on your domain (citation). In our benchmark of 7 sites, the gap between these two numbers ranged from 25 to 95 points. Ahrefs (DR 92) was 100% visible but only 5% cited. A site with DR under 10 achieved 15% citation rate by focusing on original data and answer-first structure. Authority did not predict citations. Structure did. The full step-by-step methodology, including the 20-query template and per-engine scoring sheet, is published on freeCodeCamp: [How to Measure Your AI Citation Rate Across ChatGPT, Perplexity, and Claude](https://www.freecodecamp.org/news/how-to-measure-your-ai-citation-rate-across-chatgpt-perplexity-and-claude/). The companion case study is [I Audited 7 Websites for AI Citability](/blog/ai-citability-audit-what-predicts-citations). --- ## Complete Optimization Checklist - [ ] robots.txt allows GPTBot, ClaudeBot, PerplexityBot - [ ] `/llms.txt` exists at site root - [ ] Top 10 articles have BlogPosting schema - [ ] How-to content has HowToSchema - [ ] FAQ content has FAQPageSchema - [ ] Content has 10+ headers (not 3) - [ ] Key answers in first paragraph - [ ] Important data in tables, not paragraphs - [ ] Meta descriptions under 160 chars (Google habit) - [ ] Images have descriptive alt text - [ ] No critical content in images only - [ ] Content updated in last 12 months (fresh signal) - [ ] Run infrastructure scan at [citability.dev](https://citability.dev/scan?utm_source=chudidev&utm_medium=referral&utm_campaign=how-to-optimize-for-perplexity-chatgpt-ai-search) to identify gaps - [ ] Measure AI citation rate with 20 manual queries across 3 platforms - [ ] Add original data (benchmarks, tables, unique statistics) to top articles --- ## Why Isn't My Content Showing Up in AI Search Results? The four most common causes: AI bots blocked in robots.txt, conflicting canonical URLs from cross-posting, duplicate content diluting citation chances, and schema errors preventing structured data from registering. Run through each diagnostic in order, most optimization failures trace back to one of these four fixable issues. ## When Your Optimization Isn't Working If you've done the five steps and still don't see citations in Perplexity or ChatGPT after 4-6 weeks, run this diagnostic. **Check if AI bots are reaching your pages.** Look in your server logs or analytics for user-agent strings containing GPTBot, ClaudeBot, or PerplexityBot. If you see no traffic from these bots, there's a crawl access issue, either robots.txt is still blocking them, or your hosting provider's firewall doesn't recognize these newer bot names. **Verify your canonical is consistent.** AI systems avoid citing content with conflicting canonical signals. If you're [cross-posting to Dev.to](/blog/devto-cross-posting-automation), Medium, or LinkedIn, make sure each cross-post has your original URL in the canonical field, not the platform's default. One conflicting canonical can suppress citations across all AI engines. **Check for duplicate content.** AI engines, like Google, downweight duplicate content. If you have two posts targeting the same query, consolidate them. Two 800-word posts on the same topic compete with each other and dilute citation chances compared to one 1,600-word authoritative post. **Test your schema.** Run your top 3 posts through Google's Rich Results Test. If schema errors appear, fix them, AI engines use the same structured data signals to understand content type. Most optimization failures trace back to one of these four issues. The good news: all four are diagnosable and fixable in an afternoon. If you already run a SaaS SEO programme and want to know what this changes for it, [SEO for SaaS in the AI search era](/blog/seo-for-saas-ai-search-era) covers what transfers and what your current reports cannot see. If you suspect a competitor is already winning these answers, start with [an AI visibility audit](/blog/ai-visibility-audit-b2b-saas). ## The Advantage Here's the thing: **most creators still treat AEO as optional.** You just did these 5 steps. Your competitors haven't. This gives you a 6-12 month window where your content will be cited more often in AI answers, driving visibility and traffic. This is the opposite of SEO, where the first-mover advantage is gone. AEO is still day one. Want a quick score first? Run the free [AEO audit tool](/tools/aeo-audit) to check crawler access, schema, and structure before you dig into the full strategy in my [detailed AEO guide](/blog/aeo-answer-engine-optimization-explained).