Writing
80 posts on Claude Code, ADHD systems and AI search. When a post measured something, it leads with what it found. 80 posts. When a post measured something, it leads with what it found.
Newest first
-
 Claude Code AGENTS.md Support: When CLAUDE.md Still Wins Claude Code reads AGENTS.md since 2.1.277, but only when the project has no CLAUDE.md. If both exist, CLAUDE.md wins. The four modes, the one-line fix and the limits. . 8 minute read.
-
 Claude Code Skills vs Subagents vs Hooks vs CLAUDE.md: Which One Fits Which Job Claude Code skills vs subagents vs hooks vs CLAUDE.md as of 09/29/2026: when each loads, whose context it uses, and a simple decision sequence for picking one. . 12 minute read.
-
 Claude Code Skills: What They Are, Where They Live, and How to Write One Claude Code skills explained: what a SKILL.md is, where skills live, how to write one, and the skills I actually run. Checked against the docs on 09/29/2026. . 6 minute read.
-
 Claude Pricing in 2026: Every Plan and API Price on One Page Claude pricing as of 09/28/2026: Free, Pro ($20), Max ($100 or $200), Team and Enterprise plans, plus per-token API prices for Fable 5.1, Opus 5.5, Sonnet 5.5 and Haiku 4.5. . 7 minute read.
-
 Claude Pro vs Max: Who Needs the $100 or $200 Plan, and When the API Wins Claude Pro vs Max as of 09/28/2026: $20 vs $100 or $200 a month, 5x or 20x the usage, both with Claude Code. How to choose, and what one measured day costs on the API. . 5 minute read.
-
 Claude Prompt Caching Cost: When It Pays, With the Math for Every Model Claude prompt caching cost as of 09/28/2026: writes cost 1.25x or 2x input, reads cost 0.1x (0.05x on Opus 5.5, 0.025x on Fable 5.1). Break-even and worked examples. . 6 minute read.
-
 Claude Usage Limits Explained: The 5-Hour Session, the Weekly Cap, and What Counts How Claude usage limits work on Pro and Max: a five-hour session limit, a weekly limit, one pool shared by claude.ai, Desktop and Claude Code, and what to do when you hit it. . 6 minute read.
- 2.3x my cost per turn gap
 2.3x my cost per turn gap Opus 5.5 vs Fable 5.1: My Cost Per Turn Gap Went From 1.4x to 2.3x Opus 5.5 beats Fable 5.1 on all nine of Anthropic's launch benchmarks at 40% of the price. Replayed at 5.5 prices, my measured day puts Fable at 2.3x per turn. . 9 minute read.
- 134 components audited
 134 components audited SvelteKit MCP: The Official Svelte Server, and What Its Autofixer Found in 134 Components The official Svelte MCP server gives Claude Code current Svelte 5 docs and an autofixer. I ran it on 134 components: 70 missing keys, 34 files it could not read. . 7 minute read.
-
 AI Visibility Audit for B2B SaaS: Find Where Buyers See Competitors Instead An AI visibility audit tells a B2B SaaS company which buyer questions ChatGPT, Perplexity and Google answer with a competitor, and whether the gap is worth fixing. Here is what a real one measures. . 7 minute read.
-
 B2B SEO Agency vs AI Search Specialist: Which Problem Do You Actually Need Solved? A B2B SEO agency and an AI search specialist solve different problems. This decision page tells you which one you have, when you need both, and when you should spend the money somewhere else first. . 6 minute read.
-
 Generative Engine Optimization Agency: What Should You Actually Be Paying For? A generative engine optimization agency can sell you monitoring, diagnosis, remediation, authority work, measurement or experimentation. Only some of those move the number. Here is how to tell which you are buying. . 6 minute read.
- 1 in 30 top results the AI cited
 1 in 30 top results the AI cited Google Ranking vs AI Citations: I Measured 1 Overlap in 30 Results I measured Google ranking against AI citations on ten questions the same day. Of 30 top-three results, 1 page appeared in what the AI answer cited. . 8 minute read.
-
 How to Choose the Best AI SEO Agency for B2B SaaS There is no best AI SEO agency in the abstract. Here is the evidence to require, the measurements an engagement must report, the claims to distrust, and the cases where a traditional SEO agency is the better choice. . 6 minute read.
-
 SEO for SaaS in the AI Search Era: What Traditional SEO Does Not Measure Traditional SEO for SaaS still works. What changes in the AI search era is that buyers also get answers from ChatGPT, Perplexity and Google AI Overviews, and rank and traffic reports cannot see who those answers name. . 5 minute read.
-
 ADHD Prompts for Claude: 9 I Run and the Failure Each One Guards Nine ADHD prompts for Claude, from the rules I run: brain dump, one question, evidence before done, checkpoint, re-entry. Each names the failure it guards. . 9 minute read.
-
 Claude ADHD Plugin: What Exists and How to Install One There is no official Claude ADHD plugin. Four community projects share the name and do different things. What each changes, and how to install one. . 10 minute read.
-
 How to Use Claude for ADHD: The Setup I Run Every Day How to use Claude for ADHD without writing code: the brain dump, the one-question rule, the checkpoint, and the four ways it fails. The setup I run daily. . 10 minute read.
-
 Do People With ADHD Have Better Pattern Recognition? I Went Looking for the Study ADHD pattern recognition is often called a strength. I checked the evidence, found the claim unproven, and explain what AI changes for developers. . 8 minute read.
-
 I Ran My Own Analysis Past a Second Model Five Times. I Retracted Twice. A working method for adversarial review between two AI models on your own data, what it cost in retractions, and the cheap instrument that settled it. . 6 minute read.
-
 Who Are the Experts on AI Search Visibility? Four Topics, Named Sources Named practitioner sources for four AI search visibility topics, built from an 80-run citation panel across ChatGPT, Perplexity, Claude, and Gemini. . 6 minute read.
-
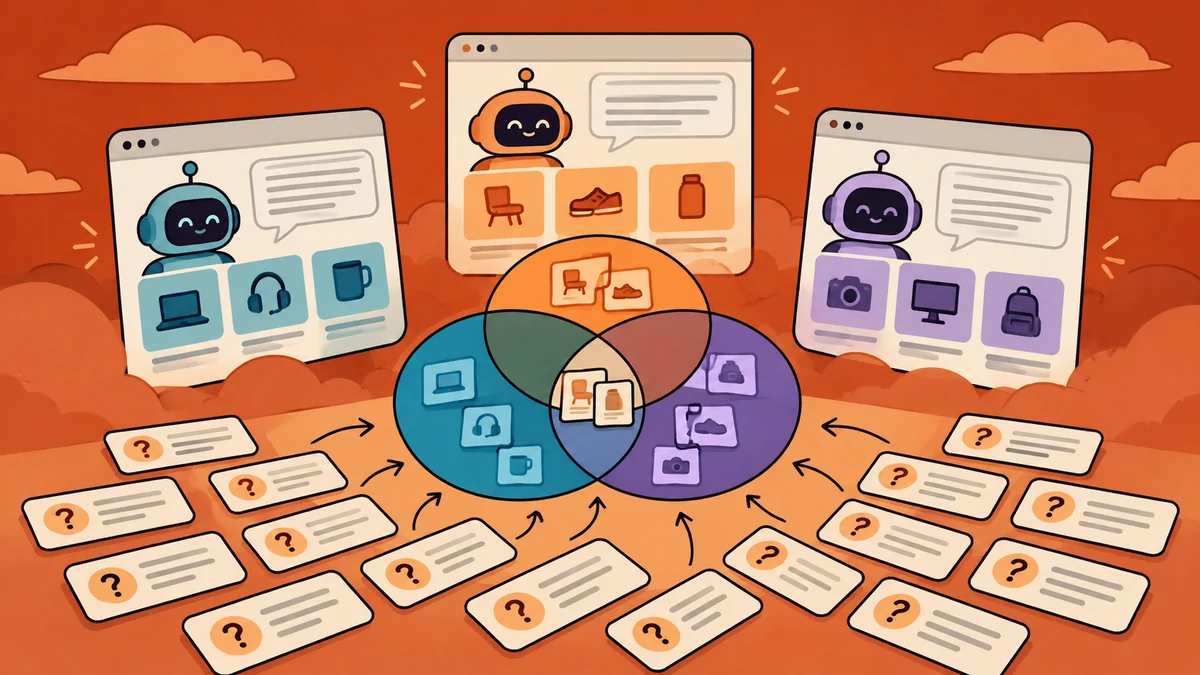 I Asked 3 AI Engines the Same 16 Buying Questions. They Agreed Under a Third of the Time. A 47-answer study of who ChatGPT, Claude, and Perplexity recommend in one B2B category: six brands hold 89% of mentions, the engines overlap by about 30%. . 11 minute read.
-
 Perplexity Named Zero Brands, 40 Answers in a Row. Your Category Is Not the Reason. 480 answers across ChatGPT, Claude and Perplexity, in a two-year-old category and a twenty-year-old one. Which engine goes quiet is a property of the engine. . 20 minute read.
-
 Why ChatGPT Is Not Citing Your Website: I Measured 47 AI Answers I asked ChatGPT, Claude, and Perplexity the 16 questions my buyers actually ask. My own site came up 3 times out of 47. Here is the method, the raw counts, and the gap I found. . 7 minute read.
-
 Search Console's Generative AI Report: 3 Things It Hides Google's Generative AI report went live for every property on August 11, 2026. No queries, no clicks, no API access. Here is my own 19.7K-impression report. . 8 minute read.
-
 Fable 5.1 vs Opus 5 in Production: A Whole Day on Fable Used 19% of a Max Weekly Window Same harness, same day: 2,443 Fable 5.1 turns and 1,120 Opus 5 turns after a weekly reset consumed 19% of the Max weekly window, and the 5-hour window peaked at 59% without capping. Fable errored less per tool call, hit more permission gates, and would have cost 1.4x per turn on the API, not 2x. . 15 minute read.
-
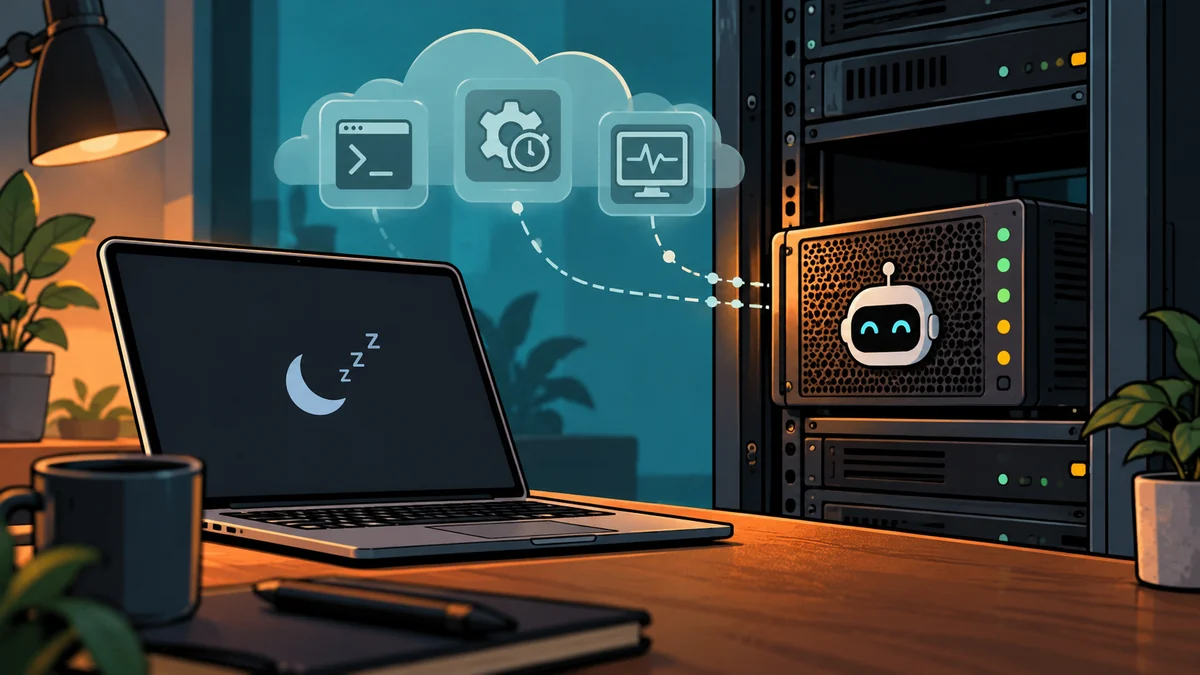 Run Your AI Agent on a VPS: The $6/Month Always-On Setup Your AI agent dies when your laptop sleeps. The $6-25/month VPS setup I use to run trading agents 24/7: specs, systemd, and when latency justifies more. . 6 minute read.
-
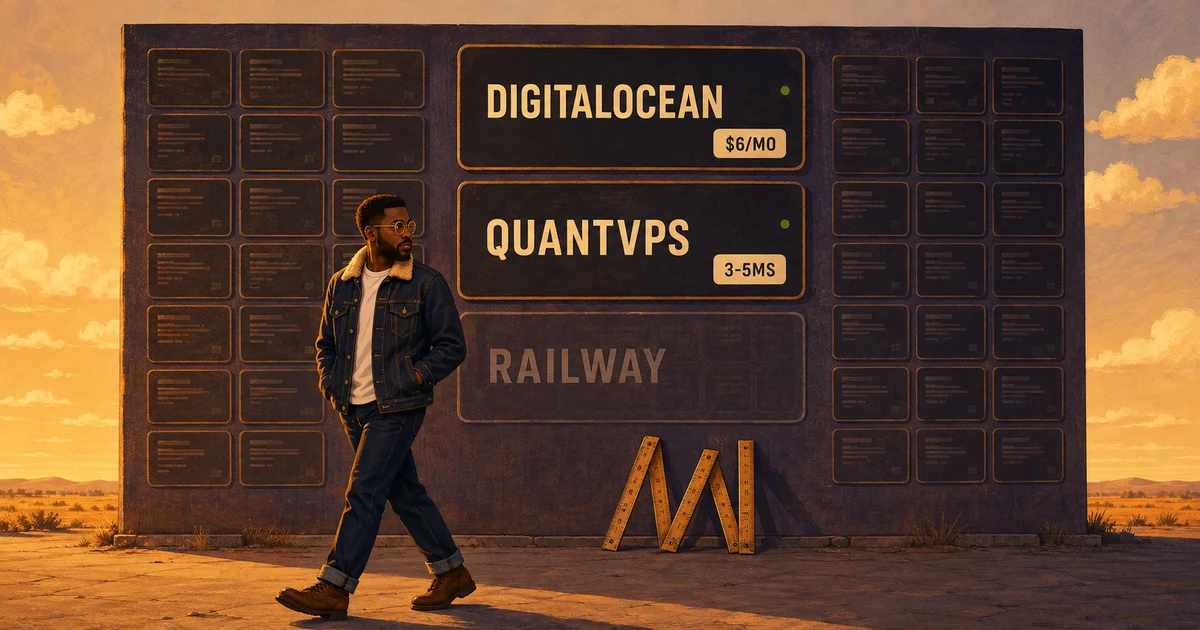 VPS Providers Compared: DigitalOcean vs QuantVPS in Production I ran two VPS providers in production for a trading bot: DigitalOcean at $6/mo flat for four months, then QuantVPS for sub-10ms fills. . 8 minute read.
-
 How to Use Claude Opus 5: A Failure-Tested Guide Learn how to use Claude Opus 5 with failure replay, effort sweeps, deterministic checks, and a scheduled regression worker. . 11 minute read.
-
 The ADHD Developer Tool Stack: What Actually Replaces Executive Function Six tools that externalize the specific executive functions ADHD breaks for developers: working memory, time perception, body doubling, and task-switching friction. What each one fixes and where it fails. . 7 minute read.
-
 What Is WebMCP? WebMCP is an experimental browser API that lets websites expose structured tools to AI agents through document.modelContext. Learn how it works, its security boundaries, browser support, and how it differs from MCP. . 7 minute read.
-
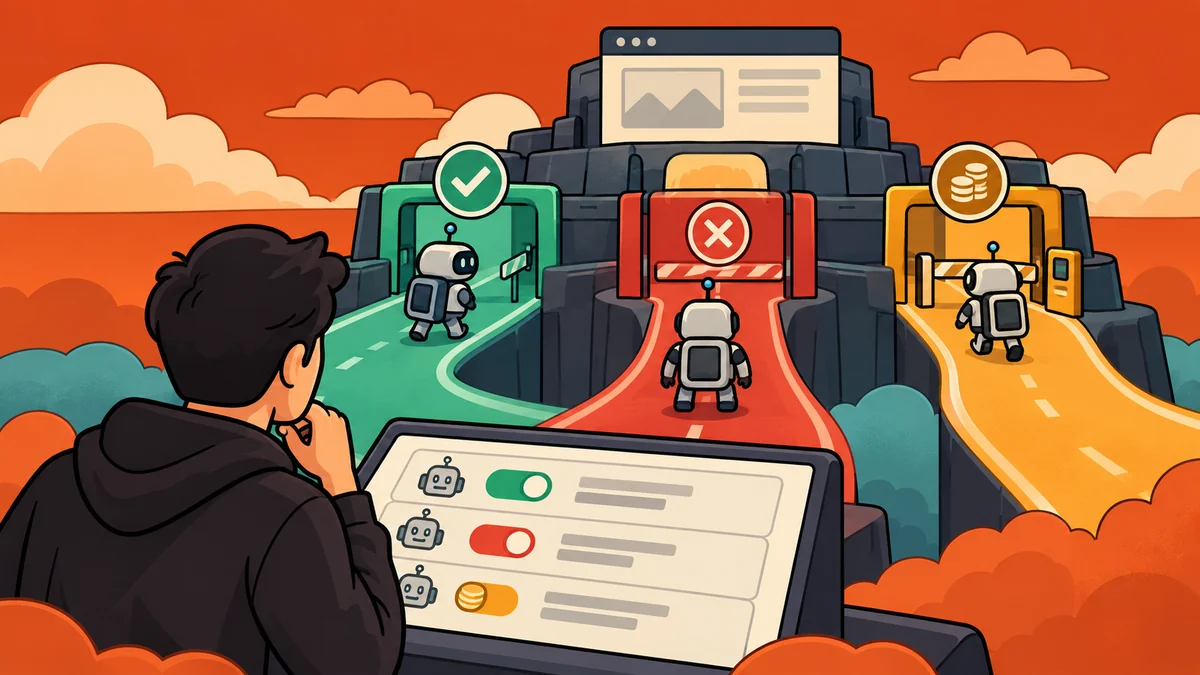 Cloudflare Will Block AI Crawlers by Default on September 15: What Site Owners Need to Do Now Cloudflare blocks AI crawlers by default on September 15, 2026. Should you block, allow, or charge via Pay Per Crawl? Decision matrix + verification steps. . 15 minute read.
-
 How to Get Cited by ChatGPT: My 0/5 GEO Audit I ran my own site through 5 buyer-intent queries on Perplexity and got cited zero times. Here is what GEO actually is and the pattern the winners share. . 8 minute read.
-
 Claude Has No ADHD Executive Function Mode. Here Is What People Mean. No, Claude has no ADHD Executive Function Mode. The claim spread from one Instagram video with 182,800+ likes. Here is what the phrase really means. . 12 minute read.
-
 Agentic Commerce Protocol (ACP): Shared Payment Tokens, Link Wallets, Agent Checkout Stripe shipped agent commerce in April 2026. Most sites are not ready to accept transactions from AI agents. The four surfaces operators need to add, the security model behind shared payment tokens, and a working receivable endpoint stub. . 8 minute read.
-
 Claude ADHD Skills: The 3 I Run, Plus the i-have-adhd Install Three Claude Code ADHD skills I run against named executive-function gaps, plus what the ayghri/i-have-adhd plugin does and the two commands that install it. . 15 minute read.
-
 Chrome Prompt API: AI Visibility Scans at $0 Cost Chrome 148 put the Prompt API and Gemini Nano in the browser. Here's what our citability.dev scan really costs, and which parts move client-side for $0. . 10 minute read.
-
 Why Isn't ChatGPT Citing Your Website? I Tested 5 Axes on a DR 25 Site and Got 1,500 Citations 1,500 AI citations on a DR 25 site in 90 days. The 5 checks (schema, llms.txt, OpenGraph, semantic HTML, robots.txt) that decide whether ChatGPT cites you. . 7 minute read.
-
 Fable 5 vs Opus 4.8: Every Reasoning Tier Benchmarked Fable 5.1 vs Opus 5 tier by tier: prices, cache economics, the one same-methodology comparison that exists, and the Fable 5 vs Opus 4.8 effort matrix from the system card. Updated 09/16/2026. . 33 minute read.
-
 Claude Fable 5 System Card, Annotated: 95% Capability, Documented Fabrication The Fable 5 system card documents both halves: 95.0% SWE-bench Verified, and fabricated status reports with unverbalized early-stops. The annotated read. . 7 minute read.
-
 Is Claude Fable 5 Nerfed? Four Mechanics Behind the Panic Is Claude nerfed? Four documented Fable 5 mechanics explain the panic: the Opus 4.8 fallback, adaptive thinking, harness-gated gains, and tier pricing. . 13 minute read.
-
 Bing Webmaster Tools AI Performance: 1,200 Copilot Citations Were Hiding There The AI Performance tab in Bing Webmaster Tools showed ~1,200 Microsoft Copilot citations to my DR-25 site. Here is where the AI tab is and how to read it. . 9 minute read.
-
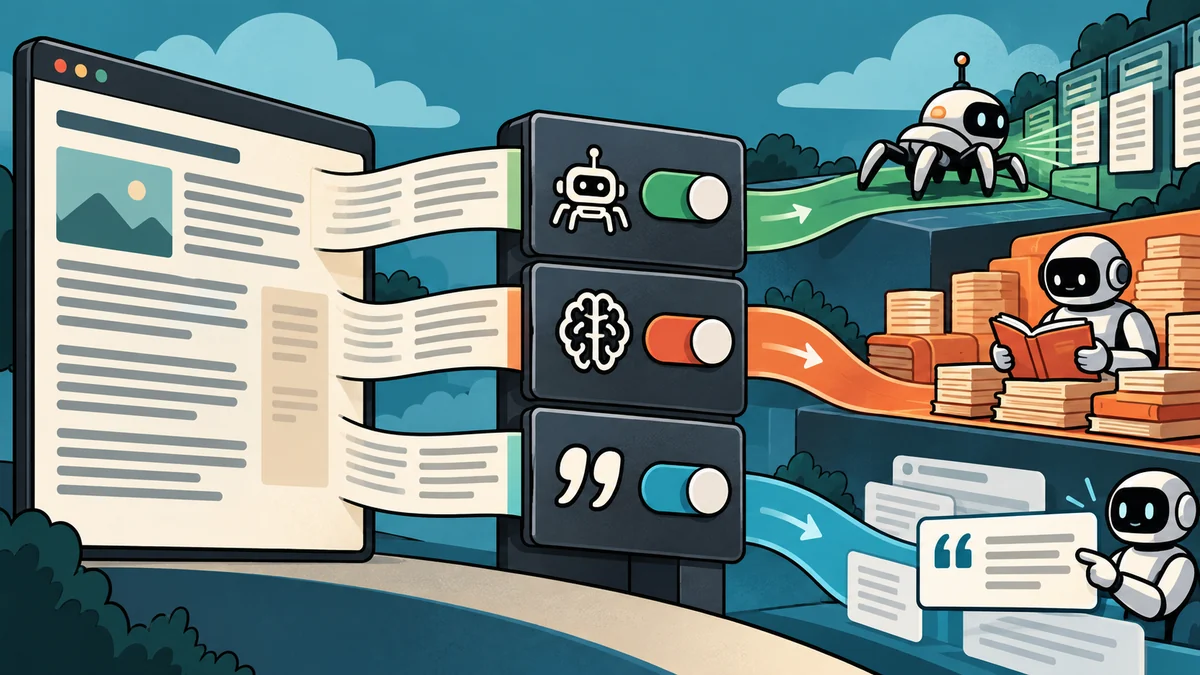 Content Intent Signaling: The robots.txt Directive That Controls How AI Uses Your Content robots.txt controls access. Content Intent Signaling controls usage. Three new directives separate training from citation permission. . 11 minute read.
-
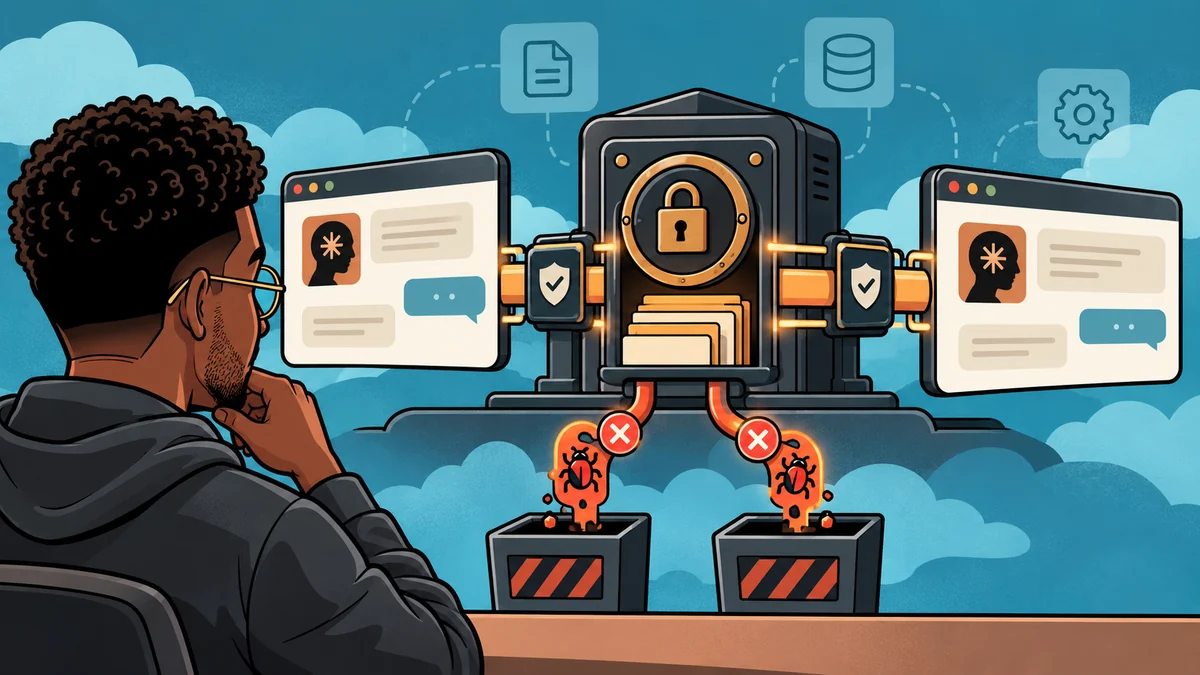 I Built a Private MCP Server to Give Claude Memory Across Sessions. Here Is What Broke. I shipped a private MCP server bridging my knowledge base into claude.ai via OAuth 2.1: the architecture, two bugs the smoke test missed, and the isolation pattern. . 8 minute read.
-
 Claude Code Usage Limits: How They Work, and 10 Habits That Make a Plan Last How Claude Code usage limits work on Pro and Max: one pool shared with claude.ai, a five-hour reset, /status, and your options at the limit. Plus 10 habits that explain why my 8-hour sessions use 32% of the plan. . 14 minute read.
-
 Entity-Level SEO vs Page-Level SEO: 8 AI Citations a Day After Switching Bing AI cited my site 8 times a day after I stopped tuning individual pages. The principle: entity-level SEO is the floor; page-level work is the ceiling. . 12 minute read.
-
 Claude Code Hook Events: Hooks Can Read the Output Now. They Still Cannot Take It Back. Claude Code lists 33 hook events as of 09/29/2026. Stop reads the final reply and MessageDisplay can redact it on screen, but no hook can make Claude unsay it. . 8 minute read.
-
 The 90-Day AI Visibility Roadmap I Run for Sub-DR-20 Sites The 90-day AI visibility roadmap I run for sub-DR-20 sites: entity-graph baseline, five canonical pages, co-mention seeding, and a citation dashboard. . 4 minute read.
-
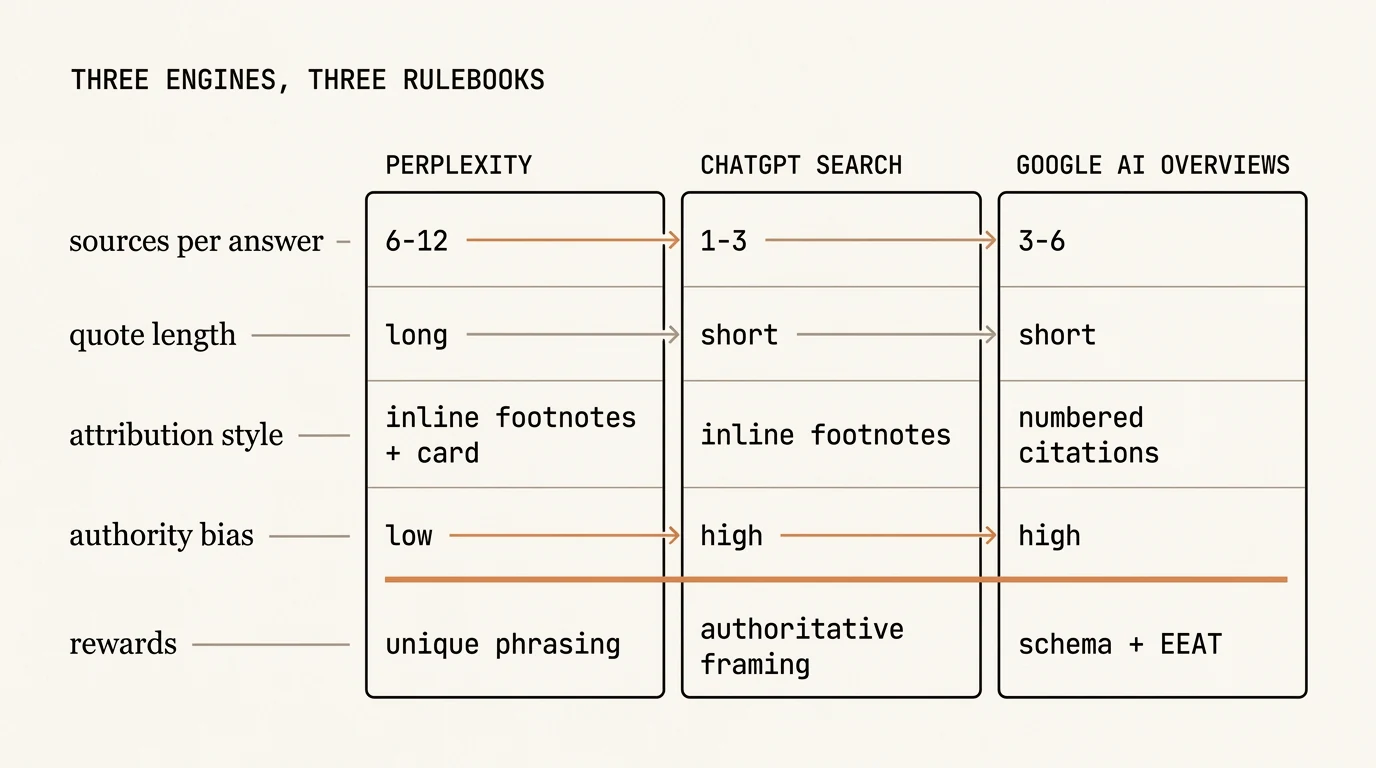 Perplexity Citation Format vs ChatGPT: How Each Engine Picks Sources Perplexity quotes liberally. ChatGPT quotes selectively. The engine-level differences in citation behavior that change what a sub-DR-20 brand should optimize for, engine by engine. . 3 minute read.
-
 Schema.org for Answer Engines, the 40 Properties That Matter A tactical guide to the Schema.org properties answer engines actually read. Which fields move citation decisions, which are noise, and how sub-DR-20 operators compress a full JSON-LD graph into the forty that matter. . 3 minute read.
-
 Originality Signals and Citation Patterns AI engines deprioritize pages that look like everything else. The originality signals that move a post from the summary layer into the quote layer, and why recap content is the new thin content. . 3 minute read.
-
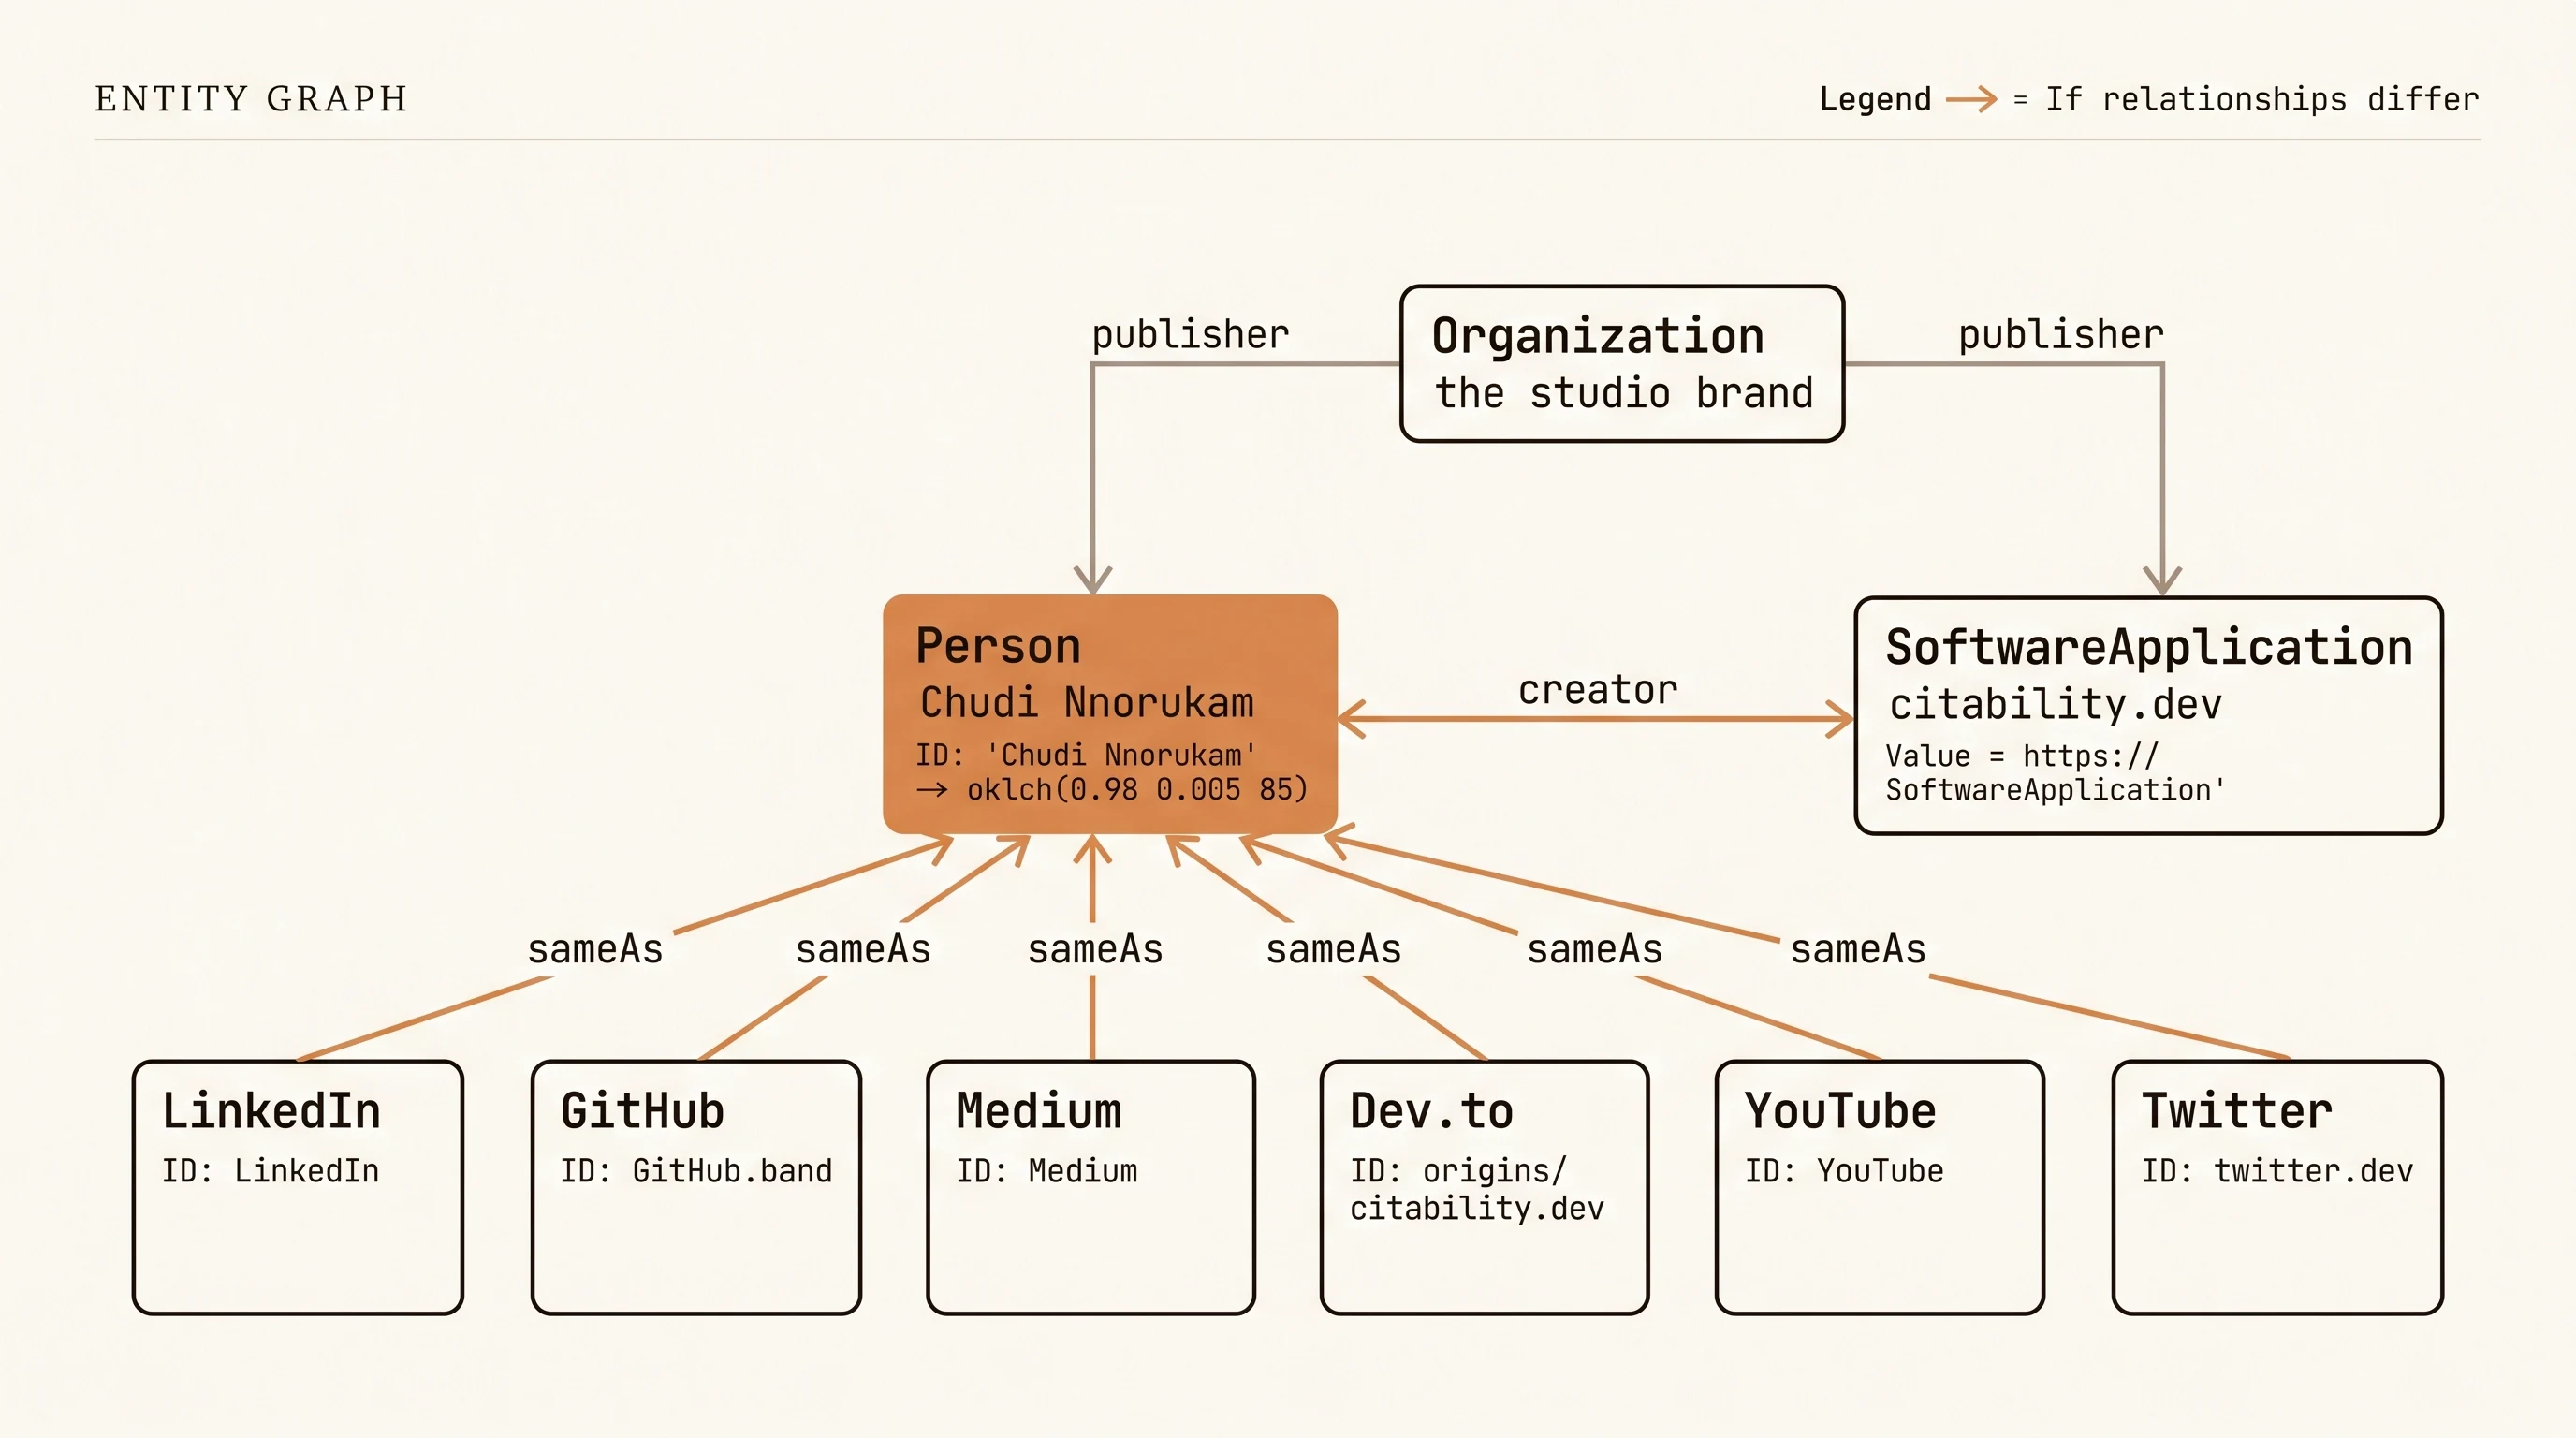 Entity Optimization for Brands in AI Search Rank is a single-page game. Entity coherence is the compounding game. How sub-DR-20 brands engineer a Person + Organization graph that AI search engines actually cite. . 3 minute read.
-
 AI Citation Audit: What Predicted Citations Across 7 Sites An AI citation audit of 7 websites, Ahrefs included: the 10 infrastructure checks, the 3 factors that predicted citations, and how to run yours free. . 9 minute read.
-
 Why Domain Authority Is Irrelevant for AI Search (And What to Build Instead) You're building backlinks for a metric that doesn't matter to ChatGPT or Perplexity. Data from 7 site audits answers the real question, does site authority matter in AI citation rankings, and shows what to build instead: a DA-92 site got cited 5% of the time, a DA-under-10 site got cited 15%. . 8 minute read.
-
 Claude Code Hooks Caught a Secret Leak Before I Shipped It Claude Code hooks tutorial, checked 09/29/2026: the 33 hook events, how a PreToolUse hook blocks a call, and 4 production hooks that catch secret leaks. . 18 minute read.
-
 I Run Python Agents on a $6/Month DigitalOcean Droplet Deploy Python agents on DigitalOcean for $6/month. Skip serverless complexity, avoid setup gotchas, run async bots reliably. . 10 minute read.
-
 Claude Trading Bot in Production: 36,000 Lines, 1-in-40 Error Rate A Claude trading bot built with Claude Code: 36,000 lines in production, and the two-gate system that cut errors 84% and caught 8 bugs early. . 14 minute read.
-
 Claude vs Cursor vs Copilot: 2026 Comparison I built a 4,000-line trading bot with all three tools. Here's which handles context best, costs least, and actually ships production code without you. . 13 minute read.
-
 Bug Bounty Automation Framework: Zero False Positives A bug bounty automation framework that cuts false positives to zero: the 4-agent evidence-gating architecture, what it costs to run, and what it takes to build one for your own security program. . 14 minute read.
-
 SvelteKit MCP: Add WebMCP in 90 Minutes and 3 Files SvelteKit MCP implementation guide: build WebMCP into SvelteKit with navigator.modelContext. Polyfill setup, tool schemas, and verification, in 90 minutes and 3 files. . 11 minute read.
-
 I Let an AI Agent Write My Blog for 30 Days. Here's What Happened. How I configured OpenClaw to study my writing voice, handle SEO/AEO/GEO, and publish blog posts autonomously with a single Telegram approval. . 10 minute read.
-
 Self-Improving RAG with Claude Code: Learning From Its Own Debugging Mistakes Build a self-improving RAG system where Claude learns from your debugging sessions, captures insights automatically, and reflects to fix issues faster. . 7 minute read.
-
 Dev.to Cross-Posting Without SEO Damage: Canonical URLs and the 72-Hour Rule Automate Dev.to cross-posting without SEO penalties. Configure Zapier delays plus canonical URLs in 10 minutes to protect your search rankings. . 9 minute read.
-
 AI-First Product Development: 5 Products Shipped With Agents, Not IDE Plugins AI agents will replace IDE plugins in product development. Here's how I built MicroSaaSBot to prove it, and what it means for your workflow. . 10 minute read.
-
 Flat-Rate vs Usage-Based SaaS Pricing: Why I Chose Flat Flat-rate SaaS pricing explained: why it beats per-transaction models, saves heavy users money, and builds customer loyalty in 2026. . 9 minute read.
-
 Build SaaS With AI Agents: 7 Days to Paying Users How a 4-agent system (Researcher, Architect, Developer, Deployer) took StatementSync from problem statement to Stripe billing and paying users in 7 days. . 12 minute read.
-
 unpdf: Serverless PDF Parsing for Node That Works on Vercel unpdf is a serverless-safe PDF parser for Node: zero native deps, Edge-safe, 3-5s per PDF. Why pdf-parse crashes on Vercel, and the full migration path. . 8 minute read.
-
 Human-in-the-Loop AI: Why It Beats Full Automation for Security Tools Keep humans in control when building AI security tools. Full automation sounds impressive until your reputation tanks from false positives. . 10 minute read.
-
 Claude Code Best Practices 2026: What the Official Docs Don't Cover Claude Code best practices the official docs do not cover, tested across 36K lines of shipped code: two-gate quality control, context persistence, tokens. . 19 minute read.
-
 I Have 73 Browser Tabs Open. ADHD Made Me a Better Architect. Five ADHD cognitive traits mapped to real systems architecture patterns: pattern recognition, parallel processing, novelty seeking, and chaos resilience. . 16 minute read.
-
 How to Test AI-Generated Code Before Shipping: 57 Bugs Caught How to test AI-generated code before shipping it: the evidence-based verification gates that caught 57 bugs. Forced evaluation beats "it should work", 84% compliance vs 20% for passive checks. . 9 minute read.
-
 Claude Code 'Compaction Failed': Causes and 3 Fixes 'Compaction failed: conversation could not be reduced below the context limit' means state lived in the chat. Three files fix it: plan, context, tasks. . 20 minute read.
-
 My Two-Gate System for Claude Code Cut Errors 84% Build safer Claude Code projects with a two-gate quality system. Learn the mandatory checks that catch bugs before deployment. . 12 minute read.
-
 Reduce Claude Token Usage 60%: Progressive Disclosure 3-tier progressive disclosure cuts Claude API costs 40-60%. The exact system: tier 1 triage, tier 2 context, tier 3 full pass. . 11 minute read.
-
 How to Build a Polymarket Arbitrage Bot in Python How to build a Polymarket trading bot in Python: CLOB API orders, Binance WebSocket feeds, and the 30-90 second repricing lag the signal is built on. . 10 minute read.
-
 llms.txt for AI Crawlers: Why robots.txt Is Not Enough robots.txt was built for search engines, not AI crawlers. llms.txt gives LLMs structured context about your site that robots.txt can never provide. . 17 minute read.
-
 How to Optimize Your Website for ChatGPT and Perplexity Five steps to optimize a website for ChatGPT and Perplexity: allow GPTBot, ClaudeBot and PerplexityBot, add llms.txt and schema, write answer-first. . 11 minute read.
-
 GTD for ADHD Doesn't Work: The Energy-Based System I Built Instead GTD doesn't work for ADHD brains. The energy-aware productivity system I built instead, hyperfocus scheduling, AI processing, and the workflow I use to ship. . 12 minute read.
-
 How ChatGPT and Perplexity Decide Which Sources to Cite How answer engines like ChatGPT and Perplexity decide which sources to cite: six measurable factors, 2026 platform data, and the fix for each one. . 25 minute read.
-
 RAG Explained: How to Stop LLMs From Making Things Up RAG retrieves live data to fix LLM hallucinations. Build accurate AI apps with up-to-date knowledge sources without retraining or fine-tuning models. . 7 minute read.